# YantrikDB — full documentation snapshot
> Cognitive memory database for AI agents. Same engine ships as embeddable Rust/Python, multi-tenant network server, and MCP server. Open source under Apache-2.0.
This file is the full concatenated content of every page at https://yantrikdb.com, generated at build time. It exists as a sibling to /llms.txt (the curated index) so AI assistants can answer questions about YantrikDB from a single fetch instead of crawling the sitemap. Pages are grouped by section and appear in the same order as the site sidebar.
For the curated index with just the most important links, see https://yantrikdb.com/llms.txt.
For machine-friendly reference data:
- Repositories: https://github.com/yantrikos
- Packages: https://pypi.org/project/yantrikdb/ , https://crates.io/crates/yantrikdb
- Docker: ghcr.io/yantrikos/yantrikdb
- Issues / discussions: https://github.com/yantrikos/yantrikdb-server/issues
---
# Engine Deep Dives
URL: https://yantrikdb.com/concepts/capabilities-detail/
The long-form capability material — retrieval, the write path, encryption at rest, and Knowledge Packs.
The capability detail that used to sit on the homepage, kept whole and organised by what the engine does rather than by release.
## Retrieval
`recall()` is one call, and five things happen inside it. Every number here was
measured end-to-end on a labelled clone of a production store, not on a
synthetic set.
BM25 keyword scoring is fused into the vector lane, then an optional cross-encoder reranks the survivors. MRR on the labelled clone moved **0.519 → 0.600 → 0.762** across the two stages — past the embedding model's own exact-cosine ceiling. A verbatim phrase is findable again instead of being averaged into a long record's dominant topic.
There is no additive recency wall; MMR diversity and re-tuned scoring do the work instead. End-to-end MRR on a production clone moved **0.054 → 0.541** when that changed. A relevant old memory beats a fresh irrelevant one, which is the entire premise of relevance-conditioned scoring.
Records longer than the embedder's window are chunked and indexed per window, so a long note is findable by *any* part of it rather than blurred into one averaged vector.
Recall returns the window that actually matched, not the whole record — **~58% fewer characters** across a 400-hit run with the ranking unchanged — plus a *relative* score cutoff that trims the weak tail. The token saving grows with your record length.
`recall(explain=True)` returns the candidate **pool**: every record that entered selection, each with a stable id, the lanes that admitted it, its bm25 strength, and its rank *before and after* fusion. A lane that didn't run says **why** (`never_ran: expand_entities=false`) instead of reporting an ambiguous zero. You can see why a result came back — and why one didn't.
---
## The write path
Most memory systems will store a lie, count a retry as new evidence, and leave
half a write behind after a crash. Each of those is closed here, and each
guarantee is enforced by a release-blocking trace contract — 13 of 13
implemented — and proven by crash-kill tests that run in CI.
A write that declares `source=inference` cannot claim `kind=fact` without a verification basis — refused at write time, before any side effect, on **every** write path (record, batch, corrections, replication apply). An agent's guess cannot quietly become your ground truth.
Durable idempotency keys: the same write retried returns the original record — no duplicate, no importance inflation, no certainty bump — even mid-crash, even under full backpressure. A different payload under the same key is a typed conflict, never a silent merge.
A rejected write — backpressure, gate refusal, failed transaction — leaves the engine byte-for-byte untouched: no row, no oplog entry, no calibration drift, no counters. Proven by crash-kill tests in CI, not by comments.
Two read behaviours worth knowing before you branch on them: `recall()`
**excludes superseded records by default** (pass `include_superseded=True` for
history — current truth is what an agent should act on), and errors worth
handling arrive as **typed exceptions** (`yantrikdb.IdempotencyConflict`,
`.Backpressure`, `.RecallContended`, …), all subclassing `RuntimeError` so
existing handlers keep working.
---
## Encryption at rest
AES-256-GCM with per-database keys, in the engine and in the server. The
write-ahead oplog is sealed and its freed pages are erased, so "encrypted"
means no record content anywhere in the raw file — enforced by a byte-scan
test that ships in CI alongside a plaintext control that must fail the same
scan. That gap was reported and fixed under
[GHSA-84vx-5fgq-5p59](https://github.com/yantrikos/yantrikdb/security/advisories/GHSA-84vx-5fgq-5p59),
which names the affected versions if you are pinned to an old one.
---
## Knowledge Packs
*A pack is a sealed, signed, measured YantrikDB file. Your local model mounts
it and gains the knowledge, rules and skills inside — then gives them back,
leaving your own memory byte-for-byte as it was.*
First-party packs live at [packs.yantrikdb.com](https://packs.yantrikdb.com)
— post-cutoff APIs, breaking releases, domain corpora — all
`official`, `signed`, and measured against control questions before
publication.
[Browse packs →](https://packs.yantrikdb.com)
The sealed manifest carries the retrieval settings its author measured
(`recommended_top_k`, `recommended_min_similarity`), signed with
everything else — a consumer never has to guess a similarity floor for
a corpus they didn't write.
RFC 031: packs mount server-side on a replicated cluster, so a fleet of
agents shares one mounted corpus instead of each carrying its own copy.
The **Ask** button on this site and on the marketplace is
[yantrikdb-assistant](/guides/assistant/) — a support widget that
answers **only** from mounted packs, and refuses before any model is
called when the packs don't cover the question.
[The packs guide →](/guides/packs/)
---
---
# What the engine does
URL: https://yantrikdb.com/concepts/capabilities/
Every YantrikDB capability, organised by what you are trying to do, with the verified API surfaces each one is available on.
The same taxonomy the homepage summarises, in full — rendered from
`src/data/capabilities.json`, which the homepage atlas reads too. There is one
source and no generated copy, so this page cannot go stale while the summary
moves.
Each capability lists the surfaces it is **verified** on. A category badge on
the homepage is the union of its items; it does not mean every operation in
that category exists on every transport. Where a claim has a boundary, the
boundary is stated with it.
## Going deeper
- [Engine Deep Dives](/concepts/capabilities-detail/) — retrieval, the write path, encryption at rest and Knowledge Packs in long form
- [Components, versions and architecture](/reference/components/)
- [Benchmarks](/research/benchmarks/)
---
# Cognitive Memory Architecture for AI Agents — Beyond Vector DBs
URL: https://yantrikdb.com/concepts/cognitive-memory/
How YantrikDB models AI agent memory — temporal decay, semantic consolidation, contradiction detection, procedural learning, and a knowledge graph. The architectural difference between cognitive memory and a vector database.
## Memory Types
Inspired by cognitive science (Tulving's taxonomy), YantrikDB supports four memory types:
| Type | What it stores | Example |
|------|---------------|---------|
| **Episodic** | Events, experiences with context | "User had a rough day at work on Feb 20" |
| **Semantic** | Facts, knowledge, abstractions | "User is a software engineer who likes AI" |
| **Procedural** | Strategies, behaviors, what worked | "User prefers concise answers with code examples" |
| **Emotional** | Valence-weighted memories | "Dog's death → high emotional weight → never forget" |
## Memory Lifecycle
Every memory goes through a lifecycle:
1. **Active** — recently created or accessed, high importance
2. **Warm** — moderate age, decaying importance
3. **Consolidation candidate** — similar memories detected, ready to merge
4. **Consolidated** — merged with related memories into a summary
5. **Archived** — very old, low importance, compressed storage
6. **Tombstoned** — explicitly forgotten or superseded
## Temporal Decay
Memories decay over time using a half-life model:
```
decay_score = importance * (0.5 ^ (elapsed / half_life))
```
- High-importance memories decay slowly (long half-life)
- Low-importance memories fade quickly
- Accessing a memory reinforces it (spaced repetition)
- Emotional valence modulates decay — emotionally significant memories persist longer
## Consolidation
When multiple memories about the same topic accumulate, YantrikDB automatically:
1. Clusters similar memories by embedding similarity
2. Extracts a summary that captures the essential information
3. Creates a consolidated memory with higher importance
4. Tombstones the original fragments (preserving them for audit)
This mirrors how human memory works — individual episodes compress into general knowledge over time.
## Contradiction Detection
When YantrikDB detects conflicting memories (e.g., "user works at Google" vs "user works at Meta"), it creates a **conflict record** with typed classification:
- **Identity facts** — flagged immediately (critical): "works at Google" vs "works at Meta"
- **Preferences** — resolved naturally in conversation: "prefers VSCode" vs "prefers Neovim"
- **Temporal conflicts** — prefer most recent, flag if uncertain: "meeting on March 30" vs "meeting on April 15"
- **Minor contradictions** — keep both, resolve lazily
Conflicts are resolved conversationally, not programmatically — the AI asks the user.
### Substitution Categories
How does YantrikDB know that "PostgreSQL" vs "MySQL" is a conflict, not just two similar memories?
**Substitution categories** — curated vocabularies of interchangeable terms. When two high-similarity memories differ only by tokens from the same category, it's flagged as a real conflict rather than redundancy.
8 built-in seed categories ship with every database:
| Category | Examples | Mode |
|----------|----------|------|
| databases | PostgreSQL, MySQL, MongoDB, Redis, ... | exclusive |
| cloud_providers | AWS, GCP, Azure, Vercel, ... | exclusive |
| programming_languages | Python, Rust, Go, TypeScript, ... | exclusive |
| frameworks | React, Vue, Django, FastAPI, ... | exclusive |
| roles | backend, frontend, devops, ML, ... | exclusive |
| infrastructure | Kubernetes, Docker, Terraform, ... | exclusive |
| editors_tools | VSCode, Neovim, IntelliJ, Cursor, ... | exclusive |
| llm_providers | OpenAI, Anthropic, Google, Mistral, ... | exclusive |
### Learning Loop
Categories grow over time through a confidence-gated feedback loop:
1. **Seed vocabulary** (confidence 0.95) — ships with the database, covers ~80 common terms
2. **User corrections** (confidence 1.0) — when a user reclassifies a conflict, differing tokens are learned as new category members
3. **LLM suggestions** (confidence 0.35) — AI agents can suggest new members, but they're marked "pending" and cannot drive conflict detection until confirmed
Only members with confidence ≥ 0.6 can trigger conflict detection. This means LLM suggestions alone never create false conflicts — they need human confirmation first.
**Anti-pollution**: The learning system filters stopwords and requires single-candidate matching to prevent contaminating categories with irrelevant tokens.
## Procedural Memory
Beyond storing facts, YantrikDB tracks *what works*:
- **Record strategies**: "When the user asks about code, show examples before explanation"
- **Track effectiveness**: Each procedural memory has an EMA-based score that adapts with reinforcement
- **Surface relevant procedures**: When facing a similar task, retrieve strategies that worked before
This enables AI agents to genuinely improve over time — not just remember what happened, but learn from it.
## Sessions
YantrikDB tracks conversation sessions, enabling:
- **Cross-session continuity**: Remember what was discussed last time
- **Session-aware triggers**: "It's been 3 days since we last talked about the migration"
- **Entity relationship depth**: How many sessions have you discussed a topic across?
## Proactive Intelligence
`think()` doesn't just detect problems — it surfaces opportunities:
- **Redundancy detection**: Similar memories that should be consolidated
- **Conflict detection**: Contradictions including substitution-based conflicts
- **Pattern mining**: Recurring themes in memory (behavioral patterns)
- **Gossip triggers**: Categories ready for LLM-assisted expansion
- **Stale memory alerts**: Facts that haven't been verified recently
- **Session awareness**: Context from previous conversation gaps
---
# YantrikDB Knowledge Graph — Entity Edges + Adaptive Recall
URL: https://yantrikdb.com/concepts/graph/
The YantrikDB cognitive state graph — typed entity relationships for AI agent memory. Track people, projects, and concepts with semantic edges. Graph-aware recall that follows relationships, not just similarity.
## Beyond Knowledge Graphs
Traditional knowledge graphs store entity-relationship triples. YantrikDB's cognitive state graph uses **typed nodes** and **typed edges** designed for AI reasoning about a user's mental state.
## Node Types
| Category | Types | Purpose |
|----------|-------|---------|
| **Primary** | Belief, Goal, Intent, Action Schema | Core cognitive states |
| **Data-Linked** | Entity, Episode, Conversation Thread | Grounded in real data |
| **Situational** | Opportunity, Risk, Constraint, Task | Current context |
| **Behavioral** | Routine, Need, Preference | Learned patterns |
## Edge Types
| Edge | Meaning | Example |
|------|---------|---------|
| `supports` | Evidence for | Belief → Goal |
| `contradicts` | Conflicts with | Belief A ↔ Belief B |
| `causes` | Leads to | Intent → Action |
| `predicts` | Anticipates | Routine → Need |
| `competes` | Alternative to | Opportunity ↔ Risk |
| `refines` | Specializes | Risk → Constraint |
| `generalizes` | Abstracts | Action → Schema |
| `depends` | Requires | Task → Preference |
## Patent Coverage
The cognitive state graph architecture is covered by Claim 2 of U.S. Patent Application No. 19/573,392.
---
# YantrikDB Relevance Scoring — Decay, Importance, Similarity
URL: https://yantrikdb.com/concepts/scoring/
How YantrikDB ranks AI agent memories using temporal decay, importance weighting, and semantic similarity. Mathematical model for relevance-conditioned recall — beyond cosine similarity for cognitive memory.
## The Problem with Additive Scoring
Traditional retrieval systems combine signals additively:
```
score = w₁·similarity + w₂·recency + w₃·importance + w₄·graph_proximity
```
This creates a fundamental problem: **an irrelevant but important memory can outscore a relevant but less important one.**
Example: If a user asks "What's for dinner?", the system might retrieve "User got promoted at work" because it has high importance — even though it has nothing to do with dinner.
## Relevance-Conditioned Scoring
YantrikDB uses a multiplicative gate:
```
gate = σ((similarity - τ) / temperature)
score = gate × (w₁·decay + w₂·recency + α·importance)
```
Where:
- `σ` is the sigmoid function
- `τ` (tau) is the relevance threshold (default: 0.25)
- `temperature` controls gate sharpness
### How the Gate Works
| Similarity | Gate Value | Effect |
|-----------|-----------|--------|
| 0.8 (high relevance) | ~1.0 | Full score passes through |
| 0.5 (moderate) | ~0.7 | Partial dampening |
| 0.2 (low relevance) | ~0.1 | Score nearly zeroed |
| 0.0 (irrelevant) | ~0.0 | Completely blocked |
**The key insight:** when relevance is low, the gate collapses the entire score to near-zero — regardless of how important, recent, or graph-connected the memory is.
## Comparison
| Query: "What's for dinner?" | Additive Score | YantrikDB Score |
|---|---|---|
| "User likes pasta carbonara" (sim=0.75) | 0.62 | **0.58** |
| "User got promoted at work" (sim=0.15, imp=1.0) | **0.71** | 0.04 |
| "User is vegetarian" (sim=0.60) | 0.55 | **0.48** |
With additive scoring, the promotion memory dominates despite being irrelevant. With relevance-conditioned scoring, it's properly suppressed.
## Adaptive Weights
YantrikDB learns optimal weights over time through feedback:
- When users access a recalled memory → positive signal
- When users ignore a recalled memory → negative signal
- Weights update via gradient-free optimization
The learned weights are stored per-database and persist across sessions.
## Patent Coverage
This scoring method is covered by Claim 1 of U.S. Patent Application No. 19/573,392.
---
# YantrikDB Proactive Triggers — Autonomous Memory Surfacing
URL: https://yantrikdb.com/concepts/triggers/
Proactive triggers in YantrikDB — stale memory detection, upcoming events, and cognitive maintenance that let AI agents initiate contextually relevant conversations without being prompted.
## Not Engagement Farming
Every proactive message from YantrikDB is **grounded in real memory data**. The system doesn't message to increase engagement — it messages because something meaningful changed.
## Trigger Types
| Trigger | What fires it | Example |
|---------|--------------|---------|
| **Decay Review** | Important memory about to fade | "I'm fuzzy on your new coworker's name" |
| **Consolidation Ready** | Cluster of related memories detected | "I noticed you always feel better after talking to your sister" |
| **Conflict Escalation** | Unresolved contradiction aging | "You mentioned two different moving dates" |
| **Pattern Discovered** | New behavioral pattern mined | "You seem stressed every Sunday evening" |
| **Temporal Trigger** | Time-based event approaching | "Your mom's birthday is tomorrow" |
| **Entity Anomaly** | Unusual graph change detected | "You stopped mentioning the gym two weeks ago" |
## Safety Constraints
| Rule | Purpose |
|------|---------|
| Cooldown periods | No messaging every hour |
| Priority threshold | Only reach out when it matters |
| Time-of-day awareness | Don't message at 3am |
| User-controlled frequency | "Check in weekly" vs "only urgent" |
| Groundedness requirement | Every message must trace to real memories |
## The Think Loop
The `think()` method runs the full cognition cycle:
1. **Consolidation pass** — compress, summarize, abstract
2. **Conflict detection** — find contradictions
3. **Pattern mining** — discover behavioral patterns
4. **Trigger evaluation** — anything worth reaching out about?
5. **Decay pass** — age out low-importance memories
---
# YantrikDB FAQ — Cognitive Memory, MCP, Cluster Mode, Pricing
URL: https://yantrikdb.com/faq/
Frequently asked questions about YantrikDB — what cognitive memory is, how it differs from a vector database, MCP integration with Claude Code/Cursor/Windsurf, hardware requirements, Apache-2.0 license, production readiness.
> Common questions about YantrikDB, cognitive memory for AI agents, MCP integration, cluster mode, and licensing.
## What is YantrikDB?
YantrikDB is a **cognitive memory database for AI agents**. It gives LLMs and agents persistent long-term memory with semantic recall, a knowledge graph, contradiction detection, autonomous consolidation, and temporal decay.
It ships in four shapes — pick the one that fits:
- **Embeddable Rust library** — `cargo add yantrikdb`. Link it into your app.
- **Python package** — `pip install yantrikdb`. For Python apps and notebooks.
- **MCP server** — `pip install yantrikdb-mcp`. Drop-in memory for [Claude Code](/guides/mcp/), Cursor, Windsurf.
- **Network database** — `yantrikdb serve`. Multi-tenant HTTP gateway with [Raft cluster mode](/server/cluster/) and [at-rest encryption](/server/encryption/).
## How is YantrikDB different from a vector database?
A vector database stores embeddings and returns top-k by cosine similarity. **YantrikDB models how memory actually works.** Every memory has importance, valence, half-life (decay), source attribution, and validity windows. The engine has an integrated [knowledge graph](/concepts/graph/) with typed entity edges, [contradiction detection](/concepts/cognitive-memory/) between stored claims, autonomous consolidation that merges duplicates and surfaces patterns, and [proactive triggers](/concepts/triggers/).
A vector DB is one of five indexes inside YantrikDB, not the whole picture.
## Does YantrikDB work with Claude Code, Cursor, and Windsurf?
Yes. YantrikDB ships an [MCP server](/guides/mcp/) (`yantrikdb-mcp`) that drops into any MCP-compatible AI client — Claude Code, Cursor, Windsurf, Copilot, and Claude Desktop. Its grouped tool surface includes remember, recall, think, graph, conflict handling, skills, and personality. The exact set can vary by release, selected tool profile, engine capability, and deployment mode.
```bash
pip install yantrikdb-mcp
```
## What is cognitive memory?
[Cognitive memory](/concepts/cognitive-memory/) models the human memory system:
- **Encoding** — what to store (with importance, valence, source)
- **Consolidation** — merging duplicates and surfacing patterns
- **Retrieval** — importance- and recency-weighted recall, not just similarity
- **Forgetting** — temporal decay so old low-importance memories fade
- **Contradiction handling** — detecting and resolving conflicting beliefs
Vector search is one component; cognitive memory is the architecture.
## Can I run YantrikDB without an internet connection?
Yes, but read the detail — it changed in 2026-08. A **new file-backed** store defaults to `potion-base-8M` (256 dims), which is **downloaded once on first use** (~28 MB, SHA-256 pinned, cached under your cache dir). It is not bundled because the crate already ships 7.9 MB of `potion-base-2M` weights and crates.io caps a published crate at 10 MB.
If that download cannot happen — you are offline, or the fetch fails — the store is created on the **bundled `potion-base-2M`** instead and a warning is logged, so YantrikDB still works with no network. That choice is **permanent for that store**: a database's dimension is fixed at creation, so switching later means re-embedding.
Two paths never touch the network: **in-memory** (`":memory:"`) stores stay on the bundled model deliberately, so test suites never require a download, and the **Rust** default is the bundled `potion-base-2M`. An **existing** store always reopens at the dimension it already holds, so upgrading the library never strands a database.
Optional higher-quality embedders (`potion-base-8M` at ~92% MiniLM, `potion-base-32M` at ~95% MiniLM) are downloadable and SHA-256 pinned; once downloaded they also work offline.
## Is YantrikDB free?
Yes — open source under [Apache-2.0](https://www.apache.org/licenses/LICENSE-2.0). Free to use, modify, self-host, and embed in closed-source products.
No copyleft and no commercial licence to buy. Apache-2.0 also grants patent rights for this implementation, so using YantrikDB does not expose you to the patent covering its methods.
## What's the difference between yantrikdb, yantrikdb-server, and yantrikdb-mcp?
| Repo | What it is | Install |
|---|---|---|
| [`yantrikos/yantrikdb`](https://github.com/yantrikos/yantrikdb) | Embeddable Rust engine + Python bindings | `cargo add yantrikdb` / `pip install yantrikdb` |
| [`yantrikos/yantrikdb-server`](https://github.com/yantrikos/yantrikdb-server) | Multi-tenant network database — HTTP, wire protocol, cluster | `brew install yantrikos/tap/yantrikdb` |
| [`yantrikos/yantrikdb-mcp`](https://github.com/yantrikos/yantrikdb-mcp) | MCP server wrapper for Claude Code / Cursor / Windsurf | `pip install yantrikdb-mcp` |
## How do I install YantrikDB?
See the full [install guide](/server/install/) and [quickstart](/guides/quickstart/). One-liners:
```bash
# Embeddable engine (Python)
pip install yantrikdb
# Embeddable engine (Rust)
cargo add yantrikdb
# MCP server for AI clients
pip install yantrikdb-mcp
# Network server (macOS/Linux)
brew install yantrikos/tap/yantrikdb
# Docker
docker pull ghcr.io/yantrikos/yantrikdb:latest
```
## What hardware does YantrikDB need?
**Single-node:** any 64-bit Linux, macOS, or Windows machine with 1 GB RAM and 1 GB disk handles tens of thousands of memories. A Raspberry Pi 4 runs a working single-agent instance.
**Production cluster:** 3-node deployment with 4 GB RAM and SSD recommended. See [cluster setup](/server/cluster/).
## Does YantrikDB support clustering and replication?
Yes. [YantrikDB Server cluster mode](/server/cluster/):
- **YRP native replication** (RFC 028) — leader election, quorum-durable writes, automatic failover in ~3 seconds
- **Exactly-once keyed writes** — retries dedupe through any replication state, never a double write
- **Linearizable reads** + **quarantine-not-wedge recovery** + **beyond-GC engine backfill**
- **Witness quorum** — safe HA with only 2 data nodes
- **Multi-tenant** — each database replicates independently
- **At-rest encryption** ([AES-256-GCM](/server/encryption/))
Every committed write is applied to engine state on every replica, and chaos scenarios gate every release.
## What does the Apache-2.0 license mean for my use?
Apache-2.0:
- ✅ Free to use, modify, distribute — including inside closed-source and commercial products
- ✅ Self-host, embed, or offer as a hosted service, with no obligation to publish your changes
- ✅ Includes an explicit patent grant covering this implementation
- ℹ️ Keep the LICENSE and NOTICE files, and state any changes you made to the source
YantrikDB was AGPL-3.0 through v0.15.x. Those releases remain available under AGPL; everything from the relicense onward is Apache-2.0.
## How does YantrikDB detect contradictions?
YantrikDB stores facts as structured claims with **polarity** (positive / negative), **validity windows**, **source attribution**, and **confidence**. The conflict detector compares claims about the same entity-relation-target tuple. When two claims with opposite polarity and overlapping validity coexist, a conflict record fires with both source memories cited.
See [Wirecard showcase](/showcase/wirecard/) for a real-world worked example: eight polarity contradictions on €1.9 billion across six years of public record.
## What is temporal decay in YantrikDB?
Temporal decay models how memories fade over time. Each memory has a configurable **half-life** (default 168 hours / 7 days). After one half-life, retrieval relevance is halved. Recent memories outrank older ones at equal semantic similarity, while old high-importance memories stay accessible.
Importance and access frequency counter-balance decay — frequently-recalled memories stay sharp. See [relevance scoring](/concepts/scoring/) for the mathematical model.
## Is YantrikDB production-ready?
**Embedded and single-node:** yes — powers real workloads on a 3-node Proxmox homelab with multiple tenants.
**Cluster mode:** structurally production-ready in v0.8.13. Empirical RYW validation on a real 2-node cluster is ongoing. For multi-node deployments, follow the [interim cluster-routing runbook](https://github.com/yantrikos/yantrikdb-server/blob/main/docs/operations/cluster-routing.md).
## How does YantrikDB compare to mem0?
mem0 is an LLM-driven memory layer — it uses an LLM to extract and store facts from conversations, backed by a configurable vector store.
YantrikDB is a cognitive memory **database** — it stores structured memories with importance, decay, polarity, and a knowledge graph at the substrate level, regardless of how the agent generates them.
mem0 is great for adding memory to LLM apps quickly. YantrikDB is for systems where memory mechanics — contradiction handling, validity windows, autonomous consolidation, audit-ready substrate — need to live below the LLM rather than alongside it.
## Does YantrikDB support skills as a first-class primitive?
Yes. As of v0.8.11, the [skill substrate](/server/http-api/#skill-substrate-v0811) exposes:
- `POST /v1/skills/define` — register a skill (`skill_id`, `body`, `applies_to`, `skill_type`)
- `GET /v1/skills/{skill_id}` — exact lookup
- `POST /v1/skills/search` — semantic search with optional filters
- `POST /v1/skills/{id}/outcome` — append-only outcome event log
- `POST /v1/skills/{id}/forget` — tombstone
**Schema-not-semantics design line:** the engine validates shape (skill_id pattern, body length, applies_to format) but does NOT enforce semantic ontology — that's the agent-layer's job. Outcome events are append-only; success-rate aggregation, ECU routing, and other pedagogy compose client-side.
## Where can I get help?
- 📖 [Documentation](/) — start here
- 💬 [GitHub Discussions](https://github.com/yantrikos/yantrikdb-server/discussions) — questions and ideas
- 🐛 [GitHub Issues](https://github.com/yantrikos/yantrikdb-server/issues) — bug reports
- 📺 [Live agi.yantrikdb.com](https://agi.yantrikdb.com) — see YantrikDB powering an AGI experiment in real time
---
# Support Assistant Widget
URL: https://yantrikdb.com/guides/assistant/
A drop-in support widget that answers only from a sealed YantrikDB pack — and refuses, before any model is called, when the pack doesn't cover the question.
The **Ask** button on this site — and on
[packs.yantrikdb.com](https://packs.yantrikdb.com) — is
`yantrikdb-assistant`: a support widget that answers **only** from a
mounted YantrikDB pack. Try it; ask it something the docs don't cover
and watch it decline instead of improvising.
## Why it refuses
Most documentation chatbots answer everything, because a retrieval
system that always returns *something* always has something to answer
from. This one refuses when nothing clears the pack's own similarity
floor — and the refusal happens **before any model is called**, so it
costs nothing and a visitor cannot argue it into answering.
That one property makes the rest trustworthy, and it makes refusals the
most useful thing the assistant produces: a refused question is a
documentation gap, stated by a real visitor, without anyone filing
anything. The admin panel turns those refusals into an authoring queue.
Sources stream **before** the first token: the visitor watches the
answer being written out of records they can see — the honest ordering
for a product whose claim is that the knowledge is in the pack, not the
model.
The model itself is given **no tools** — it receives retrieved records
as text and produces text. Nothing it outputs can execute anywhere.
## The widget
Two files, no framework, no build step, scoped so it cannot collide
with the host page's styles:
- CDN: [`https://yantrikdb.com/widget/widget.js`](/widget/widget.js)
(the stylesheet loads from beside the script automatically)
- Download:
[`yantrikdb-assistant-widget-0.4.2.zip`](/widget/yantrikdb-assistant-widget-0.4.2.zip)
One tag, with everything configurable as attributes:
```html
```
`data-theme` follows the visitor's light/dark preference (or pins one);
`data-accent` takes any CSS color — the text color *on* the accent is
computed from luminance so a pale brand stays legible; copy, placement,
radius and font are attributes too. Finer control is a CSS variable
override on `.ast`, which never leaks into (or out of) the host page's
cascade.
## The backend
The widget talks to a small server that mounts your pack and calls
whatever chat endpoint you configure (Ollama or OpenAI-compatible —
point it at a local model and visitor questions never leave your
infrastructure). It records every turn — a refusal is a content gap
whether or not anyone rates it — and ships an admin panel with the gap
queue, full transcripts, ratings, and retention controls. No IPs, no
cookies, no identity: question text is what improves a pack, and
nothing else is collected.
The server package is headed to PyPI as `yantrikdb-assistant`. Until
then, the widget you can take today is the one running on this page.
---
# Autonomous Skills on YantrikDB — Agent-Authored Procedures That Compound Across Sessions
URL: https://yantrikdb.com/guides/autonomous-skills/
Hermes Agent's core value prop is "the agent that grows with you" — a self-improving agent that writes skills from successful task completions. YantrikDB makes those skills DB-native instead of filesystem files — semantic-searchable, outcome-tracked, contradiction-aware, shared across consumers. Real data — 17 agent-authored skills on one production substrate, 9 with cross-session reuse.
[Hermes Agent](https://hermes-agent.nousresearch.com/) ships with the headline promise of being **the agent that grows with you** — its [learning loop](https://hermes-agent.nousresearch.com/docs/skills/) analyzes successful task completions, identifies reusable patterns, and writes Markdown skill files capturing the workflow as a reusable procedure. Filesystem skills are durable, version-controllable, human-editable. They're a good fit for human-curated procedures.
They're a worse fit for **agent-authored** procedures, which is what the learning loop actually produces. Filesystem skills are queryable only by filename and grep. The agent has no way to ask "which skill applies here?" without loading every file. There's no outcome ledger. There's no contradiction tracking when a skill gets superseded. There's no way for two agents on different stacks to share a skill catalog without each writing files into the other's directory tree.
That's the gap [`yantrikdb-hermes-plugin`](https://github.com/yantrikos/yantrikdb-hermes-plugin) fills. It exposes a **DB-native skill substrate** as a peer surface to Hermes' filesystem skills — semantic search, outcome ledger, contradiction tracking, shared namespace across consumers, all behind three tools the agent calls explicitly when it judges a pattern worth crystallizing.
## Watch it close the loop
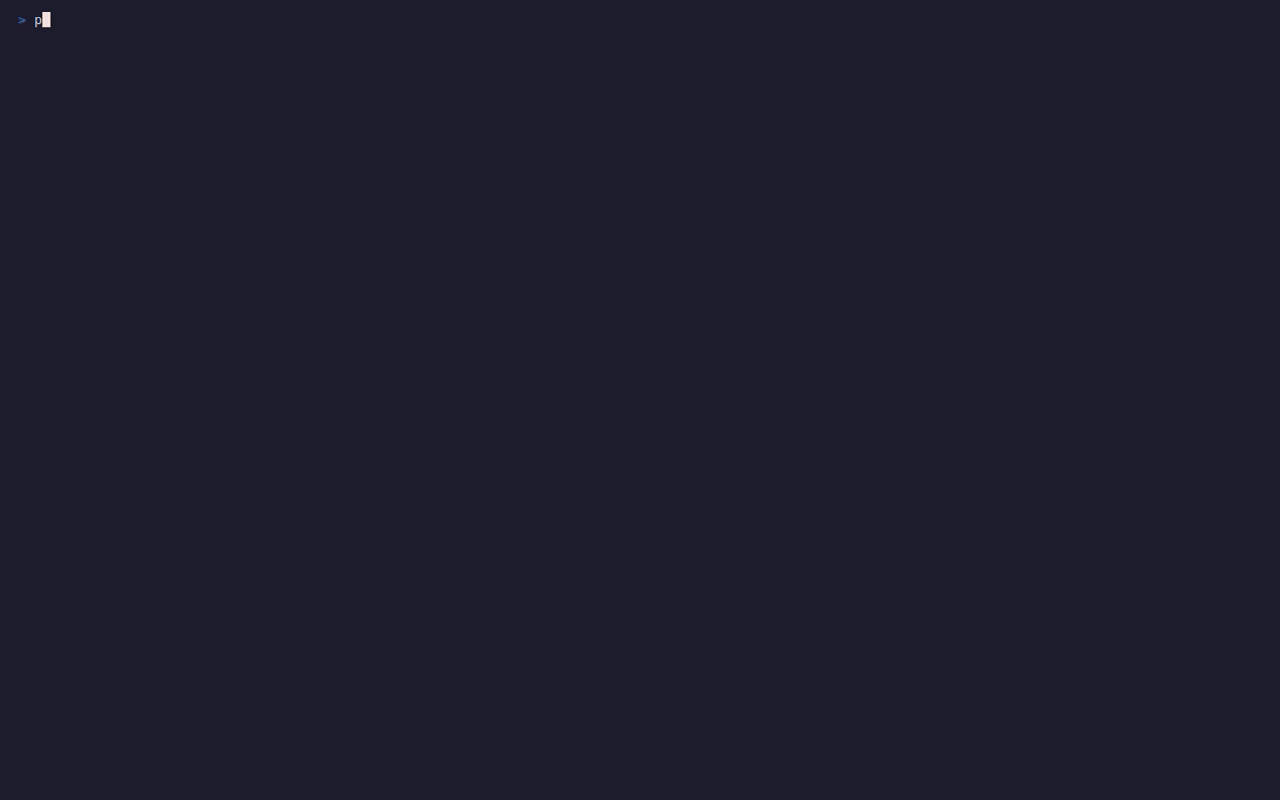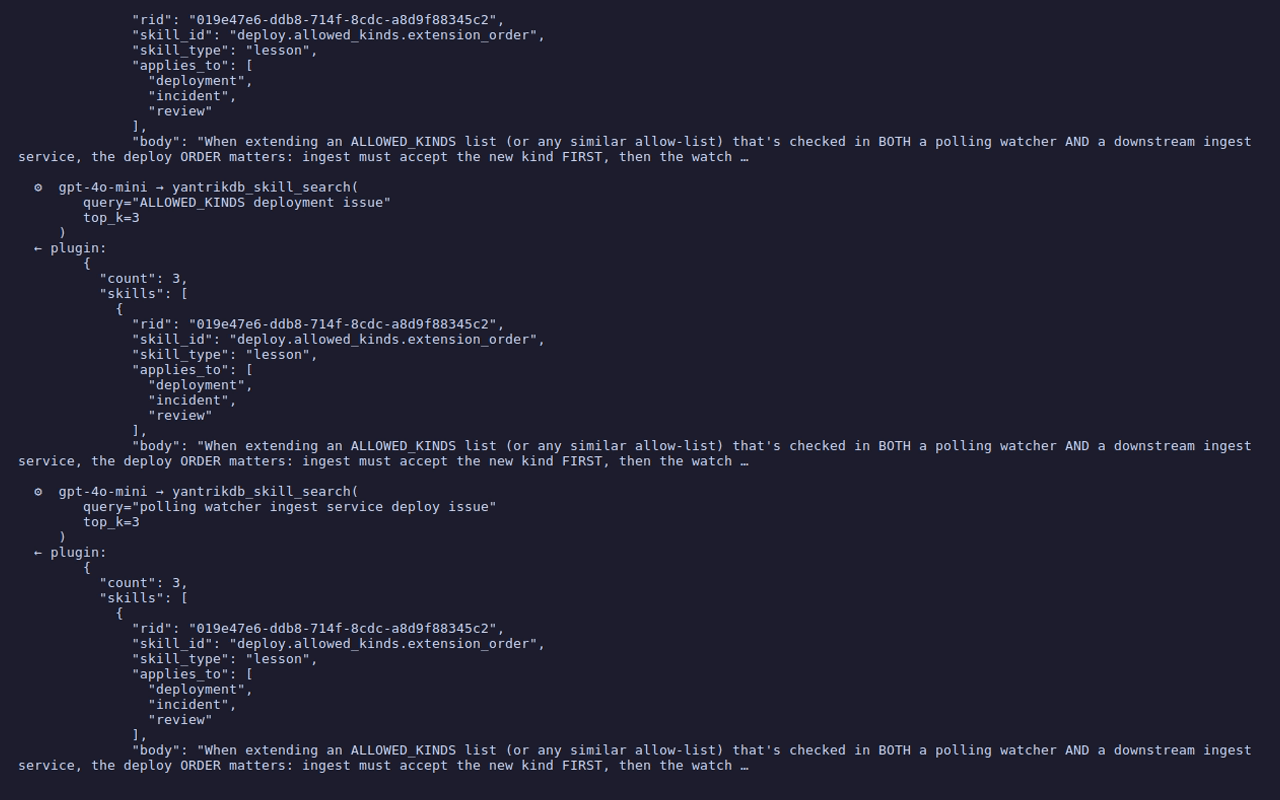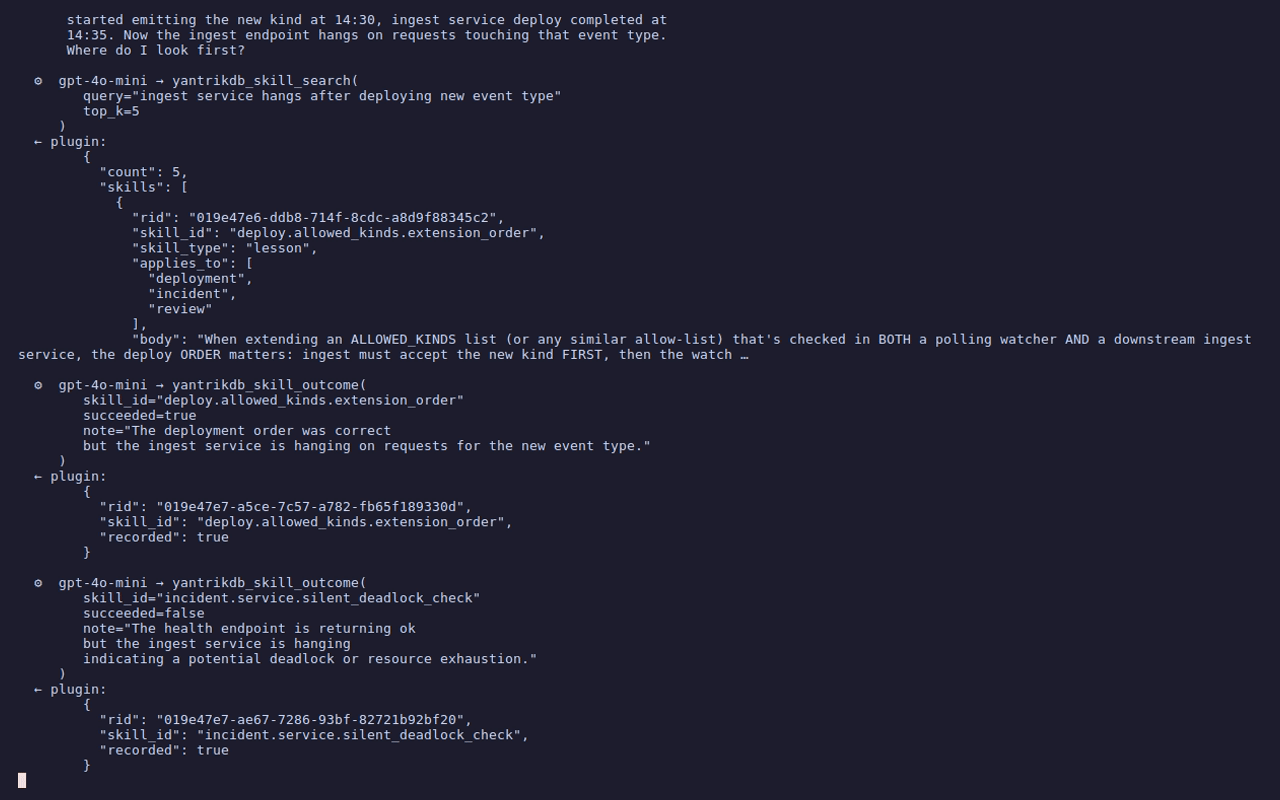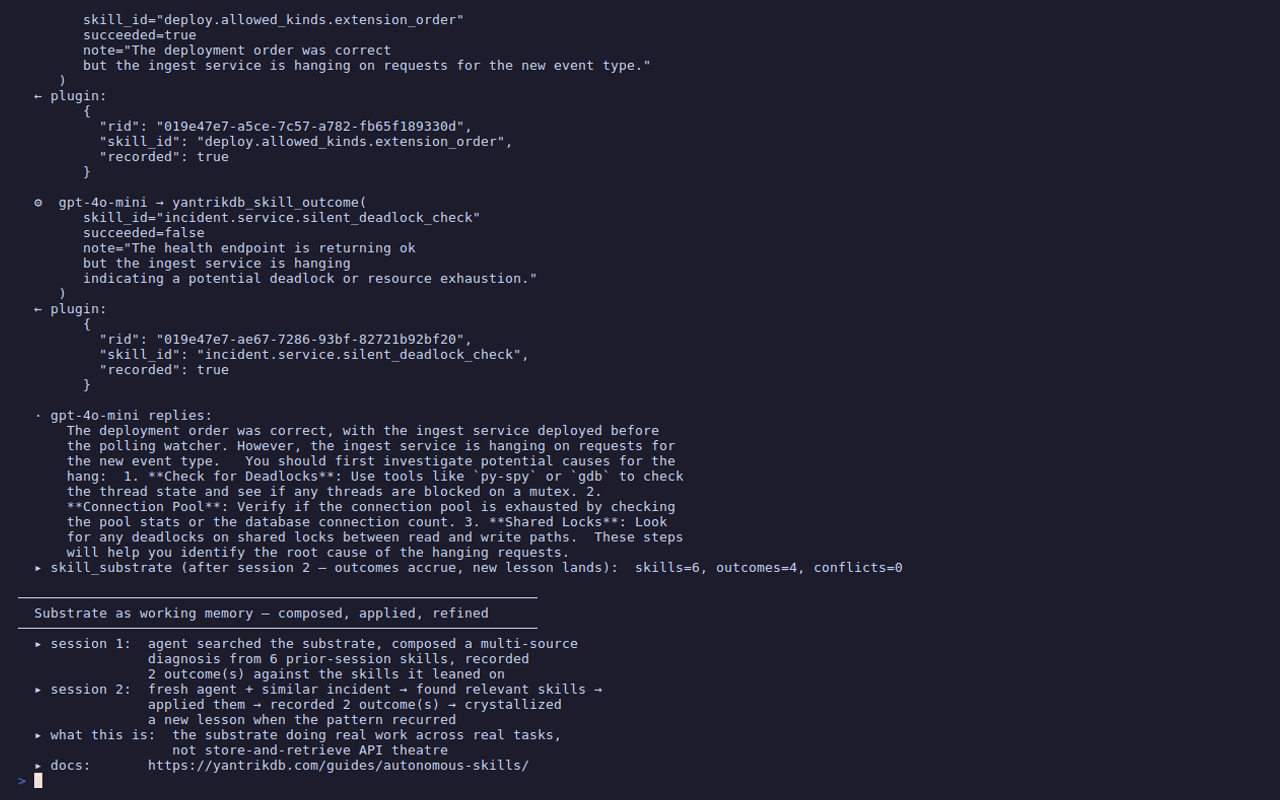
`gpt-4o-mini` receives the plugin's 11 tool schemas via OpenAI's chat-completions API. The substrate is seeded with 6 production-shaped skills (procedures, references, lessons, rules across research / deployment / incident / workflow / review domains) before session 1 begins — so the agent contributes to a lived-in catalog, not a toy.
**Session 1**: agent gets an incident report (a staging service hangs after an `ALLOWED_KINDS` deploy). It searches the substrate, finds two relevant skills, composes a diagnosis across them, then records outcomes on both with explanatory notes. **Session 2** — fresh provider, same substrate. A similar-shape incident arrives. The agent searches, finds those same skills now with outcome history attached, applies them, records two more outcomes, and — because the pattern has now recurred — calls `skill_define` itself to crystallize a new lesson (`incident.ingest.allowed_kinds_deploy_race`). Final substrate: 7 skills, 4 outcomes, one new agent-authored lesson. ~80 seconds end-to-end.
Source: [`demo_llm.py`](https://github.com/yantrikos/yantrikdb-hermes-plugin/blob/main/assets/demos/skill-lifecycle/demo_llm.py) + [`transcript-llm.txt`](https://github.com/yantrikos/yantrikdb-hermes-plugin/blob/main/assets/demos/skill-lifecycle/transcript-llm.txt) on GitHub. Everything below the LLM-call layer (tool dispatch via `handle_tool_call`, engine, substrate, response shapes) is the same code Hermes invokes when its agent loop encounters a yantrikdb tool.
## The three tools
```python
# Agent observes a useful pattern, distills it into a reusable skill.
yantrikdb_skill_define(
skill_id="workflow.git.commit_clean",
skill_type="procedure", # procedure | reference | lesson | pattern | rule
applies_to=["git", "release"],
body="Before commit: run pytest, run lint, write a clear subject + body. "
"Never include co-authored-by unless asked.",
)
# Next session — fresh agent searches before acting.
yantrikdb_skill_search(query="how to commit cleanly", top_k=5)
# → returns ranked skills with `why_retrieved` reasons
# After using a skill, record whether it worked. Append-only.
yantrikdb_skill_outcome(
skill_id="workflow.git.commit_clean",
succeeded=True,
note="caught a flake8 issue pre-push",
)
```
Three tools, one substrate. The plugin handles the schema validation, embedding, semantic search, outcome ledger, and namespace scoping. The agent makes all the judgment calls about when to define and when to look up.
## Real data: 17 agent-authored skills on one production substrate
These aren't hypothetical. The skill substrate on one production deployment currently holds **17 skills, all authored by Claude across separate sessions, none written by a human**. The agent observed patterns and chose to crystallize them.
Distribution by type:
| skill_type | Count |
|---|---|
| `procedure` | 11 |
| `reference` | 5 |
| `lesson` | 1 |
Sample of categories the agent chose to crystallize:
- Workflow patterns — `release sequence on yantrikos repos with branch protection`, `shipping a dashboard update`
- Incident lessons — `extending ALLOWED_KINDS in both polling watcher AND ingest (the deploy-ordering trap)`, `dashboard recent-events endpoint shows older lane data fine but brain-shape kinds delayed`
- Cross-session norms — `Pranab is sole author, no co-authored-by tag unless asked`, `for user-visible product changes do not lead with marketing voice`
- Research protocols — `pre-registration first; declare hypothesis before any data analysis`
- Communication patterns — `one-word greenlight ("ok" / "go" / "lets go") means execute, not ask clarifying questions`
**Reuse is real but modest.** 9 of the 17 skills have `access_count > 0` — meaning a separate session searched for and used them. The most-reused skill (`Pranab is sole author + commit conventions`) has been pulled 3 times by independent inference instances looking up commit norms before shipping. That's the autonomy loop closing across sessions.
## How `skill_define` fits the actual Hermes use cases
[Hermes' user-stories page](https://hermes-agent.nousresearch.com/docs/user-stories) describes seven documented use cases. The autonomous-skills surface maps directly into five of them:
| Hermes use case | What skill_define captures |
|---|---|
| **Personal assistant** (Telegram / WhatsApp / Discord) | "How I handle a new package-delivery notification" — observed once, distilled, reused next time |
| **Multi-platform messaging** | "How to interpret message from `whatsapp:user-A` vs `telegram:user-A`" — when owner-scoping (v0.4.10+) collapses platforms to one identity, the skills travel with the canonical owner |
| **Developer productivity** | "How I review a Hermes plugin PR" — distilled from successful reviews, surfaced next time before the agent starts |
| **Research & content curation** | "How I survey a new topic over a week" — repeat the protocol that worked, not the one that didn't |
| **Self-improvement / skill auto-generation** | This **is** the use case. Hermes' built-in learning loop writes filesystem Markdown; the plugin exposes the same loop into a DB substrate so the skills are searchable, outcome-tracked, and shareable with other agents on the same substrate. |
## Why filesystem skills aren't enough on their own
Hermes' built-in Markdown skills and yantrikdb's DB substrate aren't competitors — they're peer surfaces with different lifecycles. The right call depends on who's authoring and how the skill needs to evolve.
| Property | Filesystem skill (`$HERMES_HOME/skills/*.md`) | yantrikdb skill substrate |
|---|---|---|
| Author | Best fit for **human-authored**, durable, version-controlled, code-review-shaped | Best fit for **agent-authored**, runtime-evolving, outcome-tracked |
| Lookup | filename, grep, manual indexing | semantic search via `yantrikdb_skill_search`, ranked by relevance + recency + outcome |
| Outcome tracking | Implicit (you'd see if a procedure failed during a session, but no ledger) | First-class append-only outcome ledger via `yantrikdb_skill_outcome` |
| Contradiction | If two skills contradict, you'd notice during use | `conflicts()` surfaces the contradiction; the agent can `resolve_conflict()` explicitly |
| Sharing across stacks | One agent's filesystem; you'd have to copy files into another | Single shared `skill_substrate` namespace; another consumer (the [MCP server](/guides/mcp/), Lane B SDK, etc.) reads and writes from the same store |
| Schema validation | Free-form Markdown | Schema-validated at write time — skill_id format, type enum, body length bounds, applies_to format |
| Provenance | Git history if you commit them | `metadata.source=hermes` (or `mcp`, etc.) — each entry tagged with the consumer that authored it |
| Version compatibility | You manage it | The plugin handles it; entries from older schemas migrate forward |
Filesystem skills win when a procedure is curated, reviewed, and stable. DB-native skills win when the procedure is observed-then-crystallized in the moment, and you want a different agent in a different session to find it again.
## Install
```bash
hermes plugins install yantrikos/yantrikdb-hermes-plugin --enable
pip install yantrikdb # same Python env as Hermes
hermes memory setup # select "yantrikdb"
hermes gateway restart
```
Skills are enabled by setting `YANTRIKDB_SKILLS_ENABLED=true` in your Hermes `.env`. The substrate writes to the shared `skill_substrate` namespace; if you also run the [`yantrikdb-mcp` server](/guides/mcp/) on the same backing store, that server's tools and this plugin's tools read and write the same catalog.
## Where to look next
- [Hermes Plugin guide](/guides/hermes/) — full setup, owner-scoping for multi-platform, embedded vs HTTP backend
- [Hermes Dashboard guide](/guides/hermes-dashboard/) — visual operator console for browsing the substrate (memory + skills + identity scope)
- [Skill-as-Memory research paper](/papers/skill-substrate/) — the substrate thesis behind why agent-authored procedures want a DB surface, not a filesystem one
- [`yantrikdb-hermes-plugin` on GitHub](https://github.com/yantrikos/yantrikdb-hermes-plugin) — issues, PRs, CHANGELOG
The 17 skills above are evidence that the autonomy loop closes in practice. Skills the agent chose to crystallize, looked up in subsequent sessions, and accumulated outcomes against. The substrate kept score; the agent made the calls.
---
# YantrikDB Cortex Plugin — Personality + Bond Evolution
URL: https://yantrikdb.com/guides/cortex/
The YantrikDB Cortex plugin gives AI agents persistent personality traits, bond evolution with users, and automatic context assembly. Memory-driven character continuity for chatbots, NPCs, and long-running assistants.
[Cortex](https://github.com/yantrikos/cortex) is an OpenClaw/ClawDBot plugin that gives AI agents persistent memory with personality traits, bond evolution, and full context assembly — all powered by YantrikDB's 5-index architecture.
While the [MCP server](/guides/mcp) gives any MCP client raw access to YantrikDB's memory tools, Cortex adds an **agent personality layer** on top: traits that evolve per-user, relationships that grow over time, and a single `process_turn()` call that handles everything.
## Installation
```bash
pip install yantrik-memory
yantrik-memory init
```
Or as an OpenClaw plugin:
```bash
cd ~/.openclaw/skills
git clone https://github.com/yantrikos/cortex.git
pip install -e cortex
```
## What It Adds Over Raw YantrikDB
| Feature | YantrikDB (raw) | Cortex |
|---------|-----------------|--------|
| Memory storage | `record()` / `recall()` | `remember()` / `recall()` with agent scoping |
| Personality | — | 9 evolving traits per user |
| Relationships | — | 6-stage bond evolution |
| Context assembly | — | `get_full_context()` with mood, intent, guidance |
| Single entry point | — | `process_turn()` does everything |
| Knowledge graph | `relate()` / `entity_profile()` | `relate()` / `get_entity()` |
| Cognitive maintenance | `think()` | `think()` (passthrough) |
## Quick Start
```python
from yantrik_memory import YantrikMemory
mem = YantrikMemory()
# Single entry point — handles everything
context = mem.process_turn(
agent_id="assistant",
user_id="alex",
message="I prefer concise responses. We're using FastAPI.",
)
# context includes:
# - memories: relevant recalled memories with scores
# - traits: {'conciseness': 0.55, 'helpfulness': 0.5, ...}
# - bond: {'level': 'acquaintance', 'score': 0.08}
# - personality_guidance: "Be more concise in responses."
# - mood: {'mood': 'neutral', 'confidence': 0.5}
# - intent: 'casual'
```
## Real Conversation Demo
Here's Cortex running inside OpenClaw. The agent remembers context across turns, learns preferences, and builds a profile.
**Turn 1** — Alex introduces himself:
> **Alex:** Hey! I'm Alex. I'm a backend engineer at a startup. We're building a task management app and I need help setting up the API.
>
> **Agent:** Hi Alex. What stack are you using? What API help do you need?
**Turn 2** — Alex shares preferences:
> **Alex:** We're using Python with FastAPI. I prefer keeping things simple — no over-engineering.
>
> **Agent:** *(provides a clean, minimal FastAPI project structure)*
**Turn 3** — Agent remembers the database preference:
> **Alex:** Remember — I always use PostgreSQL for production and SQLite for local dev.
>
> **Agent:** *(provides database setup code using SQLAlchemy with the exact backends Alex specified)*
**Turn 4** — Alex asks what the agent remembers:
> **Alex:** What do you remember about me?
>
> **Agent:**
> - Backend engineer at a startup
> - Building a task management app
> - Using Python with FastAPI
> - Prefer simple solutions, no over-engineering
> - Always use PostgreSQL for production, SQLite for local dev
Behind the scenes, YantrikDB tracked:
- **5 memories stored** across the Vector, Graph, and Temporal indexes
- **Traits evolved**: `helpfulness: 0.55`, `conciseness: 0.55`
- **Bond level**: `acquaintance` after 4 interactions
- **Knowledge graph**: `Alex → works_at → Startup`, `TaskApp → uses → FastAPI`
## Personality Traits
9 traits that evolve bidirectionally based on user interactions:
| Trait | Positive signals | Negative signals |
|-------|-----------------|------------------|
| Humor | "haha", "funny", "lol" | "be serious", "no jokes" |
| Empathy | "thank you", "appreciate" | "don't care", "whatever" |
| Curiosity | "interesting", "tell me more" | "boring", "skip" |
| Creativity | "creative", "innovative" | "just do the normal thing" |
| Helpfulness | "helpful", "perfect" | "useless", "not helpful" |
| Honesty | "honest", "straightforward" | "misleading", "fake" |
| Conciseness | "concise", "to the point" | "elaborate", "more detail" |
| Formality | "formal", "professional" | "casual", "chill" |
| Directness | "straight to the point" | "gentle", "diplomatically" |
Negative signals are weighted 33% heavier to prevent one-way trait inflation. Traits decay toward 0.5 (neutral) with a 30-day half-life.
## Bond Evolution
Relationships grow logarithmically through 6 stages:
| Stage | Threshold | Description |
|-------|-----------|-------------|
| Stranger | 0.00 | No established relationship |
| Acquaintance | 0.15 | Basic familiarity |
| Familiar | 0.35 | Regular interaction |
| Companion | 0.55 | Comfortable working relationship |
| Trusted | 0.75 | Deep trust, anticipates needs |
| Bonded | 0.90 | Strong mutual understanding |
Milestones are tracked at 1, 5, 10, 25, 50, 100, 250, and 500 interactions. Bonds decay after 60 days of inactivity.
## Architecture
```
┌─────────────────────────────┐
│ Cortex │ Agent-facing API
│ traits, bonds, context │
├─────────────────────────────┤
│ YantrikDB │ Storage engine
│ Vector · Graph · Temporal │
│ Decay Heap · KV │
└─────────────────────────────┘
Single SQLite file
```
Cortex is the **brain layer**. YantrikDB is the **memory layer**. Together they give agents persistent, evolving intelligence with zero external dependencies.
---
# YantrikDB Examples — Memory, Recall, Knowledge Graph in Python
URL: https://yantrikdb.com/guides/example/
Working YantrikDB examples — persistent AI agent memory via Python API, MCP server for Claude Code and Cursor, knowledge graph construction, contradiction detection, procedural learning. Copy-paste-runnable.
## Python API — Direct Usage
### Store and recall memories
```python
from yantrikdb import YantrikDB
from sentence_transformers import SentenceTransformer
db = YantrikDB("./my_app.db")
db.set_embedder(SentenceTransformer("all-MiniLM-L6-v2"))
# Store memories
db.record(text="User prefers dark mode", importance=0.8, domain="preference")
db.record(text="Project deadline is March 30", importance=0.9, domain="work")
db.record(text="Alice is the team lead", importance=0.7, domain="people")
# Recall relevant memories
results = db.recall(query="who leads the team?", top_k=3)
for r in results:
print(f"[{r['score']:.2f}] {r['text']}")
# [1.45] Alice is the team lead
```
### Build a knowledge graph
```python
# Create relationships
db.relate("Alice", "Backend Team", "leads")
db.relate("Alice", "Acme Corp", "works_at")
db.relate("Backend Team", "FastAPI", "uses")
# Query connections
edges = db.get_edges("Alice")
# [{'src': 'Alice', 'dst': 'Backend Team', 'rel_type': 'leads'},
# {'src': 'Alice', 'dst': 'Acme Corp', 'rel_type': 'works_at'}]
# Get entity intelligence
profile = db.entity_profile("Alice")
```
### Cognitive maintenance
```python
# Detect contradictions, consolidate redundant memories, mine patterns
result = db.think()
print(f"Consolidated: {result['consolidation_count']}")
print(f"Conflicts found: {result['conflicts_found']}")
# Check for stale important memories
stale = db.stale(days=30)
for m in stale:
print(f"Needs review: {m['text']}")
# Check upcoming deadlines
upcoming = db.upcoming(days=7)
for m in upcoming:
print(f"Due soon: {m['text']}")
```
### Procedural memory — learn what works
```python
# Record a strategy
db.record_procedural(
text="For FastAPI auth, use OAuth2PasswordBearer with JWT tokens",
domain="work",
)
# Later, surface relevant procedures
procedures = db.surface_procedural(query="how to add authentication")
# Returns ranked strategies by effectiveness
# Reinforce what worked
db.reinforce_procedural(rid=procedures[0]["rid"], outcome=0.9)
```
---
## MCP Server — AI Agent Memory
The MCP server gives any MCP-compatible agent persistent memory with zero code changes. Just configure and go.
### Claude Code
```json
// ~/.claude/mcp.json
{
"mcpServers": {
"yantrikdb": {
"command": "yantrikdb-mcp"
}
}
}
```
Now your agent automatically:
```
You: We decided to use PostgreSQL for the new service
Agent: [auto-remembers: "Decision: use PostgreSQL for new service", importance: 0.8]
// ... 3 weeks later, new conversation ...
You: What database did we pick for the new service?
Agent: [auto-recalls] You decided on PostgreSQL for the new service.
```
### Multi-session context
```
// Session 1
You: I'm Alex, backend engineer. We're building a task manager with FastAPI.
Agent: [stores: name, role, project, stack]
// Session 2 (days later)
You: Can you help me add auth to the API?
Agent: [recalls: Alex, FastAPI project, task manager]
Sure Alex! For your FastAPI task manager, I'd recommend
OAuth2PasswordBearer with JWT tokens...
```
### Contradiction detection
```
// Session 1
You: We're using PostgreSQL for the database
// Session 5
You: We switched to MySQL last week
Agent: [think() detects conflict]
I notice a contradiction — you previously said PostgreSQL,
but now you're saying MySQL. Which is current?
```
---
## Cortex — OpenClaw Plugin
Cortex wraps YantrikDB with personality traits, bond evolution, and context assembly for [OpenClaw](https://github.com/openclaw/openclaw) agents.
### Single entry point
```python
from yantrik_memory import YantrikMemory
mem = YantrikMemory()
# One call does everything:
# - Recalls relevant memories
# - Evolves personality traits
# - Updates relationship bond
# - Assembles full LLM context
context = mem.process_turn(
agent_id="assistant",
user_id="alex",
message="That's really helpful, thanks! Keep it concise.",
)
print(context["traits"])
# {'humor': 0.5, 'empathy': 0.5, 'helpfulness': 0.55,
# 'conciseness': 0.55, ...}
print(context["bond"])
# {'level': 'acquaintance', 'score': 0.08,
# 'interaction_count': 4}
print(context["personality_guidance"])
# "Be more helpfulness in responses. Be more conciseness in responses."
```
### Traits evolve per user
```python
# User A likes humor
mem.evolve_traits("assistant", "alex", "haha that's hilarious!")
traits_a = mem.get_traits("assistant", "alex")
# {'humor': 0.55, ...}
# User B prefers seriousness
mem.evolve_traits("assistant", "jordan", "please be serious")
traits_b = mem.get_traits("assistant", "jordan")
# {'humor': 0.43, ...} (negative signals weighted 33% heavier)
```
### Bond grows over time
```python
# First interaction
bond = mem.update_bond("assistant", "alex", "hello!")
# {'level': 'stranger', 'score': 0.02, 'milestones': ['First interaction']}
# After 25 interactions
# {'level': 'familiar', 'score': 0.38,
# 'milestones': ['First interaction', 'Getting acquainted',
# 'Building rapport', 'Familiar face']}
# After 100+ interactions
# {'level': 'trusted', 'score': 0.78,
# 'milestones': [..., 'Trusted partner']}
```
### Real conversation flow
```
Turn 1:
Alex: I'm a backend engineer building a task manager with FastAPI.
Agent: Hi Alex. What API help do you need?
[stored: name, role, project, stack]
Turn 2:
Alex: I always use PostgreSQL for prod, SQLite for dev.
Agent: [recalls FastAPI project, provides SQLAlchemy setup
with exactly those backends]
[stored: database preferences]
Turn 3:
Alex: You're really helpful! What do you know about me?
Agent: Backend engineer, building task manager, FastAPI,
PostgreSQL for prod, SQLite for dev.
[traits: helpfulness → 0.55]
[bond: stranger → acquaintance]
```
---
## Common Patterns
### Per-project databases
```bash
# Each project gets its own memory
YANTRIKDB_DB_PATH=./project-a/memory.db yantrikdb-mcp
YANTRIKDB_DB_PATH=./project-b/memory.db yantrikdb-mcp
```
### Encrypted memories
```python
from yantrik_memory import YantrikMemory
mem = YantrikMemory({"encryption_enabled": True})
# Sensitive data encrypted at rest with Fernet
mem.remember(
agent_id="assistant",
content="API key: sk-1234567890",
memory_kind="secret",
content_encrypted=True,
)
```
### Export and backup
```python
db = YantrikDB("./memory.db")
# Stats for monitoring
stats = db.stats()
print(f"Active: {stats['active_memories']}")
print(f"Entities: {stats['entities']}")
print(f"Conflicts: {stats['open_conflicts']}")
```
---
# Hermes Dashboard on YantrikDB — Operator Console for Hermes Memory
URL: https://yantrikdb.com/guides/hermes-dashboard/
wysie's yantrikdb-hermes-dashboard is the local-first FastAPI operator console for a Hermes agent's YantrikDB memory — browse, configure, and safely maintain identities, namespaces, contradictions, lifecycle housekeeping, and the visualiser. v0.8.17 ships the HTTP read endpoints that unlock cluster deployments.
[`yantrikdb-hermes-dashboard`](https://github.com/wysie/yantrikdb-hermes-dashboard) is a FastAPI **operator console** built by community member [@wysie](https://github.com/wysie) for a Hermes agent backed by YantrikDB. It's not just a memory viewer — it's the configuration surface for per-user memory, identity/scope routing, namespace coverage, contradiction review, lifecycle housekeeping, and the entity-graph visualiser. Read-only browsing by default; mutating operations are gated behind an opt-in Admin Mode plus an optional dashboard password.
Until v0.8.17 the dashboard only ran against an embedded SQLite file, which meant you could only point it at the single machine the agent ran on. **YantrikDB Server v0.8.17 ships the three HTTP read endpoints the dashboard needs**, so you can now run it against a clustered or remote YantrikDB deployment and inspect a multi-agent fleet's shared memory from one place.
## What the dashboard does
Per the [dashboard's README](https://github.com/wysie/yantrikdb-hermes-dashboard#features), the operator surface covers:
- **Overview** — active / consolidated / forgotten memories, conflicts, entities, edges, DB size, embedder
- **Memory browser** — search, status / domain / source filters, namespace chips, detail drawer
- **Recall debugger** — top-k, domain / source, consolidated-memory and entity-expansion controls
- **Identity & Scope** — Hermes owner / person scoping, actor mapping, shared spaces, conversation routing, namespace coverage (this is where you toggle the **per-user memory** the plugin's v0.4.10 owner-scoping feature exposes)
- **Contradiction review and resolution helpers** — Admin Mode required for resolution
- **Entity graph inspection** + a **Visualiser** with Constellation and Neural Map modes backed by local YantrikDB data
- **Lifecycle and maintenance** — stale / upcoming memories, triggers, patterns, safe housekeeping
- **JSONL export** of active memories
- **Settings page** — Admin Mode toggle, dashboard password, namespace defaults
## Security considerations
The dashboard is a **community project**, not maintained by the YantrikDB org. We surface it here because it solves a real problem and integrates cleanly with the v0.8.17 endpoints — but you are running third-party code that can read and (in Admin Mode) mutate your agent's memory. Read this section before pointing it at anything sensitive.
The dashboard ships its **own safety model** (per [its README](https://github.com/wysie/yantrikdb-hermes-dashboard#safety-model)), and that's the first line of defence:
- **Read-only browsing by default.** Mutating operations require **Admin Mode**, which is opt-in via the Settings page (or `YANTRIKDB_DASHBOARD_ADMIN_MODE=true` at launch).
- **Optional dashboard password** — configure from Settings before exposing the dashboard beyond `127.0.0.1`.
- **Bind to `127.0.0.1` by default.** The README recommends `YANTRIKDB_DASHBOARD_HOST=127.0.0.1`; bind to `0.0.0.0` only if you intentionally want LAN access — and set the dashboard password first.
Additional cautions that apply to any third-party tool holding a memory credential:
- **Audit the source.** Read [`app.py`](https://github.com/wysie/yantrikdb-hermes-dashboard/blob/main/app.py) and its dependencies before deploying. Pin a specific commit (`git checkout `) — don't run `main` blindly.
- **Bearer token = full data-plane access in HTTP mode.** YantrikDB Server v0.8.17 doesn't yet ship scope-restricted tokens. A token you give the dashboard for cluster mode can `remember`, `forget`, `recall`, and `relate` on every memory in its namespace — not just read. **Treat the dashboard's token as a full credential**, and rotate it after sessions where you don't trust the local state. (Per-token `Scope::Read`-only is a [Phase 2 follow-up](https://github.com/yantrikos/yantrikdb-server/issues/39); when it ships, mint the dashboard a Read-only token.)
- **Don't expose Admin Mode externally without password protection.** The README is explicit: "Do not expose an Admin Mode dashboard without password protection." If you port-forward or front the dashboard with a permissive reverse proxy, set the password from Settings first, and prefer your own SSO / basic-auth layer in front of it.
- **XSS surface.** The dashboard renders raw memory `text` in the browser. If the memories were written by an untrusted agent (e.g. one that ingested external content), HTML/script in the memory body can execute in your browser session. Running on `127.0.0.1` keeps the attack surface to your own machine.
- **Token-pinning best practice (HTTP mode).** Mint a dashboard-specific token (`yantrikdb token create --db --label hermes-dashboard`) rather than reusing the agent's token — so you can revoke it via `yantrikdb token revoke` without affecting the agent's writes.
- **Supply-chain hygiene.** Watch the [dashboard repo's commit history](https://github.com/wysie/yantrikdb-hermes-dashboard/commits/main) if you re-deploy from `main`. The repo is a personal account (not org-protected); pinning to a known-good commit hash is the simplest defense.
These cautions apply to any third-party tool that holds a token to your memory. We're naming them explicitly because the v0.8.17 endpoints make this category of tooling possible, and we want the security model to be visible upfront — both the dashboard's own (Admin Mode + password + `127.0.0.1` default) and the operator's responsibility for the broader supply chain.
## What changed in v0.8.17
Issue [#39 Phase 1](https://github.com/yantrikos/yantrikdb-server/issues/39) shipped three new `/v1/*` read endpoints plus the substrate that authorizes them:
| Endpoint | What it returns |
|---|---|
| `GET /v1/identity-scope` | What this token can see: principal, effective scope, namespace inventory, identities/actors/spaces/conversations summary. The nested envelope the dashboard's sidebar reads. |
| `GET /v1/memories` | Paged, filtered listing of active memories. Query params: `namespace`, `status`, `domain`, `memory_type`, `limit` (default 50, max 200), `offset`, `sort` (`created_at` / `importance` / `last_access`). Response: `{total, limit, offset, items[]}` with each row in the dashboard's 25-field shape. |
| `GET /v1/memory/{rid}` | Point read for a single memory by RID, with `consolidation_sources`/`entities`/`claims` conditional arrays. Supports `?min_seq=N` for read-your-writes after a write. |
Plus three cross-cutting upgrades the dashboard also benefits from:
- **Structured error envelope** across the whole `/v1/*` surface: `{"error":{"code":"stable_id","message":"human","hint":"optional"}}` per [`docs/error-codes.md`](https://github.com/yantrikos/yantrikdb-server/blob/main/docs/error-codes.md). The dashboard branches on `code`, not on the prose message.
- **Token-derived auth + namespace scoping**. `/v1/identity-scope` is computed from the token's authorized scope — a tenant-pinned token sees exactly one namespace, a cluster-admin token enumerates everything.
- **FTS5 fallback marker on `/v1/recall`**. The dashboard's search box gets an explicit `fallback: "fts5_keyword"` field when semantic returned nothing and the engine fell back to BM25 keyword matching — so the UI can flag the result as "we keyword-matched, not semantic-matched".
## Quickstart
### 1. Run a YantrikDB server
```bash
docker pull ghcr.io/yantrikos/yantrikdb:0.8.17
docker run --rm -p 7438:7438 \
-v $PWD/data:/var/lib/yantrikdb \
ghcr.io/yantrikos/yantrikdb:0.8.17
```
The Docker image ships the bundled `potion-base-2M` embedder by default — no network calls at first run, ~7 MB baked into the binary.
### 2. Create a database and mint a token
```bash
docker exec -it yantrikdb db create --data-dir /var/lib/yantrikdb default
docker exec -it yantrikdb token create --data-dir /var/lib/yantrikdb --db default --label hermes
# → ydb_xxxxxxxxxxxx... (save this — shown once)
```
### 3. Point your Hermes agent at the cluster
In `~/.hermes/.env`:
```bash
YANTRIKDB_MODE=http
YANTRIKDB_URL=http://localhost:7438
YANTRIKDB_TOKEN=ydb_xxxxxxxxxxxx...
YANTRIKDB_NAMESPACE=default
```
See the [Hermes plugin guide](/guides/hermes/) for the per-mode trade-offs (embedded vs HTTP).
### 4. Run the dashboard
```bash
git clone https://github.com/wysie/yantrikdb-hermes-dashboard
cd yantrikdb-hermes-dashboard
# Configure the dashboard to talk to the same server
export YANTRIKDB_URL=http://localhost:7438
export YANTRIKDB_TOKEN=ydb_xxxxxxxxxxxx...
uvicorn app:app --port 8080
```
Open `http://localhost:8080`. The sidebar enumerates the namespaces visible to the token via `/v1/identity-scope`. Click into a memory to see the per-row detail via `/v1/memory/{rid}`. The search box hits `/v1/recall` and surfaces the FTS5-fallback indicator when relevant.
## Auth model (what the token sees)
The dashboard's left-hand "Identity Scope" panel is rendered directly from the `/v1/identity-scope` response. Two patterns matter:
- **Tenant-pinned token** (created via `yantrikdb token create --db `) → the dashboard sees exactly that database's namespace. Requesting `?namespace=other` returns 403 `namespace_not_found`. This is the safe-by-default path for production deployments where each agent has its own scoped token.
- **Cluster-admin token** (the `cluster_secret` from your config, when cluster mode is enabled) → the dashboard enumerates every database on the cluster. The operator inspecting a multi-agent fleet uses this token.
Either way, the token is **never echoed in the response body** — the principal's `id` field surfaces a non-reversible hash prefix only, so refreshing the dashboard with browser devtools open doesn't leak the secret to the JavaScript console.
## Phase 1 limitations (Phase 2/3 follow-ups)
The dashboard ships against the shape, not yet the full depth. Honest call-outs:
- `identity_scope.{identities,actors,spaces,conversations}` are empty arrays in Phase 1 — those are plugin-side concepts the engine doesn't store on its own.
- `namespace_inventory[].count` is `null` for cluster-admin tokens — populating per-namespace counts would mean opening every engine on a synchronous handler call, which is a cached path that lands in Phase 2.
- Memory rows return `null` for `updated_at`, `updated_at_iso`, `tombstone_reason`, `embedding_model`, and `embedding_bytes` — engine v0.7.x doesn't surface those on its public listing API yet. `created_at_iso` *is* populated.
- `/v1/memories` rejects (specific 400 `invalid_query_parameter`) on `q` text search, `source` filter, and the `sort ∈ {updated_at, access_count, certainty}` variants. The dashboard either omits these or routes `q` through `/v1/recall` instead. Phase 2/3 backfills as engine APIs land.
The full list is in the [v0.8.17 CHANGELOG](https://github.com/yantrikos/yantrikdb-server/blob/main/CHANGELOG.md#0817--2026-05-18).
## Why this exists
YantrikDB stores a Hermes agent's whole working memory — every fact, every conversation turn, every consolidation, every contradiction. The dashboard is the visual layer for that memory: namespaces on the left, raw rows in the middle, identity scope and recall traces on the right. Without it you'd be writing one-off `curl /v1/memories?...` invocations.
[@wysie](https://github.com/wysie) is a community member who maintains the dashboard — they're also the contributor behind [`yantrikdb-hermes-plugin` v0.4.10](/guides/hermes/) (the owner-scoping feature). The issue → spec → ship loop for v0.8.17 took about a day of focused work after the design questions were locked.
## Links
- **Dashboard:** [github.com/wysie/yantrikdb-hermes-dashboard](https://github.com/wysie/yantrikdb-hermes-dashboard)
- **Hermes plugin:** [github.com/yantrikos/yantrikdb-hermes-plugin](https://github.com/yantrikos/yantrikdb-hermes-plugin) — embedded-mode memory for the agent itself ([guide →](/guides/hermes/))
- **YantrikDB Server:** [github.com/yantrikos/yantrikdb-server](https://github.com/yantrikos/yantrikdb-server) — the HTTP backend ([install →](/server/install/) · [HTTP API →](/server/http-api/))
- **Issue:** [yantrikdb-server #39](https://github.com/yantrikos/yantrikdb-server/issues/39) — full Phase 1/2/3 plan
- **v0.8.17 release:** [release notes](https://github.com/yantrikos/yantrikdb-server/releases/tag/v0.8.17) · [CHANGELOG](https://github.com/yantrikos/yantrikdb-server/blob/main/CHANGELOG.md#0817--2026-05-18)
---
# Powering the Hermes agent
URL: https://yantrikdb.com/guides/hermes-integration/
How yantrikdb-hermes-plugin gives NousResearch Hermes persistent memory.
## Power the Hermes Agent
[Hermes](https://github.com/hermes-agent/hermes) is an open-source agent runtime. YantrikDB is its cognitive memory — three layers that compose into the full ecosystem:
`pip install yantrikdb-hermes-plugin` → 3-line `.env` config → the agent autonomously calls `yantrikdb_remember` / `yantrikdb_recall` / `yantrikdb_stats` during conversations. Sub-millisecond on the embedded backend. Owner-scoping for multi-user Hermes gateways contributed by community member [@wysie](https://github.com/wysie).
[Hermes plugin guide →](/guides/hermes/)
`docker pull ghcr.io/yantrikos/yantrikdb:{v.server}` → multi-tenant database with HTTP API, YRP native replication, automatic failover, encryption at rest, and server-side clustered packs (RFC 031). Switch the plugin's `YANTRIKDB_MODE=http` and one agent's memory becomes shared infrastructure for a fleet.
[Server quickstart →](/server/quickstart/)
**Built by community member [@wysie](https://github.com/wysie):** [`yantrikdb-hermes-dashboard`](https://github.com/wysie/yantrikdb-hermes-dashboard) — a FastAPI dashboard for browsing, *configuring*, and safely maintaining a Hermes agent's YantrikDB memory: namespace/identity/space configuration, per-user memory toggles, recall debugger, contradiction review, entity graph visualiser, lifecycle housekeeping. Read-only browsing by default; Admin Mode opt-in for mutating ops, with an optional dashboard password.
⚠ **Third-party code.** Not maintained by the YantrikDB org. Audit before running against production data — see the [security considerations](/guides/hermes-dashboard/#security-considerations) on the guide.
[Hermes dashboard guide →](/guides/hermes-dashboard/)
The dashboard reads a cluster, not just a file.{' '}
The server's /v1/identity-scope, /v1/memories, and /v1/memory/{rid} endpoints let it run against a clustered deployment instead of one embedded SQLite file, so an operator inspects a multi-agent fleet's shared memory from one URL. Token-derived auth means a tenant-pinned token sees exactly its namespace; a cluster-admin token sees the whole fleet. [link: /guides/hermes-dashboard/]Read the dashboard guide →
---
---
# YantrikDB Hermes Plugin — Persistent Memory for Hermes Agents
URL: https://yantrikdb.com/guides/hermes/
The yantrikdb-hermes-plugin gives Hermes agents persistent memory with three lines of config. Embedded SQLite backend, no server, no token mint — sub-millisecond recall powered by YantrikDB's cognitive memory engine.
[Hermes](https://github.com/hermes-agent/hermes) is an open-source agent runtime. The [`yantrikdb-hermes-plugin`](https://github.com/yantrikos/yantrikdb-hermes-plugin) gives Hermes agents persistent memory via YantrikDB — embedded mode by default, no separate server, no token-mint step, no cluster.
If you're running a Hermes agent and want it to remember across conversations, this is the smallest possible integration: install the plugin, set three environment variables, restart the agent.
## Installation
```bash
pip install yantrikdb-hermes-plugin
```
Pulls ~10 MB total (yantrikdb engine + plugin + bundled embedder). No torch, no transformers, no ONNX runtime.
## Configuration (3 lines)
Add to `~/.hermes/.env`:
```bash
YANTRIKDB_MODE=embedded
YANTRIKDB_DB_PATH=~/.hermes/memory.db
YANTRIKDB_NAMESPACE=default
```
That's it. Verify the agent picked it up:
```bash
hermes memory status
# → yantrikdb available ✓
```
## What it adds to a Hermes agent
The plugin registers three tools the agent can call autonomously:
| Tool | What it does |
|---|---|
| `yantrikdb_remember` | Store a memory with importance + domain tags. ~0.08s first call (engine warmup), sub-ms after. |
| `yantrikdb_recall` | Semantic search across stored memories. Returns ranked results with `why_retrieved` explanations the agent can integrate. |
| `yantrikdb_stats` | Namespace stats — active memories, conflicts, decay state. Useful for the agent to introspect its own memory. |
Default ranking uses YantrikDB's full scoring: similarity × importance × decay × graph proximity. The `why_retrieved` field tells the agent *why* a memory surfaced (e.g., `["semantically similar (0.62)", "important (decay=0.98)", "graph-connected via Alice"]`) — this lets the agent give natural-language explanations of recall, rather than just dumping vector hits.
## Embedded vs HTTP mode
The plugin supports two backends:
| Mode | When to use | Latency | Setup cost |
|---|---|---|---|
| **`embedded`** (default) | Single agent, local data, no replication needed | Sub-ms recall | 3 env vars |
| `http` | Cluster deployment, replication, multi-agent shared memory, **dashboard inspection** | ~10-30 ms | YantrikDB server + token mint + URL |
For most Hermes agent setups (one agent, local memory), embedded is the right choice. For multi-agent systems or production with replication, switch to HTTP and run a [YantrikDB server](/server/install/).
> **HTTP mode + dashboard:** if you switch to `http` mode and want a visual layer over the agent's memory, point [`wysie/yantrikdb-hermes-dashboard`](https://github.com/wysie/yantrikdb-hermes-dashboard) at the same server. YantrikDB Server v0.8.17 ships the three read endpoints the dashboard needs. See the [Hermes-dashboard guide](/guides/hermes-dashboard/).
## Example: agent with persistent memory
```python
# Hermes agent run
python run_agent.py --base_url https://api.deepseek.com/v1 --model deepseek-chat
```
Without the plugin: every conversation starts blank.
With the plugin: the agent autonomously calls `yantrikdb_remember` on decisions, preferences, and facts during the conversation, and `yantrikdb_recall` at the start of subsequent turns. A real DeepSeek session was verified end-to-end on 2026-05-09 — 3 `yantrikdb_remember` calls + 1 `yantrikdb_recall` (correctly ranked) + 1 `yantrikdb_stats`, all sub-millisecond on the embedded backend.
The agent's natural-language explanation of why it recalled what it recalled uses YantrikDB's `why_retrieved` annotations directly — no extra prompting needed.
## What you don't get from the plugin
The plugin ships YantrikDB's *core memory primitives* (record / recall / stats). It does **not** ship:
- **Skill management** (`/v1/skills/*` endpoints) — skills are server-side in YantrikDB, and Hermes has its own filesystem-based skill catalog that stays canonical. See the [Skill as Memory paper](/papers/skill-substrate/) for why this separation is deliberate.
- **Schema validation for agent-written content** — embedded mode has no admission control. Agent-written records are accepted as-is.
- **Raft replication** — single-machine embedded backend by definition.
- **Knowledge graph operations** — `relate` / `entity_profile` are available via the engine API but the plugin exposes only the three core tools by default.
For these, run the [YantrikDB server](/server/install/) and set `YANTRIKDB_MODE=http`.
## Links
- **Plugin source:** [github.com/yantrikos/yantrikdb-hermes-plugin](https://github.com/yantrikos/yantrikdb-hermes-plugin)
- **PyPI:** [`yantrikdb-hermes-plugin`](https://pypi.org/project/yantrikdb-hermes-plugin/)
- **Hermes runtime:** [github.com/hermes-agent/hermes](https://github.com/hermes-agent/hermes)
- **Underlying engine:** [YantrikDB](/guides/introduction/) · [MCP server](/guides/mcp/) · [Cortex plugin](/guides/cortex/) · [Hermes plugin](/guides/hermes/) (this page)
---
# What is YantrikDB? — Cognitive Memory for AI Agents
URL: https://yantrikdb.com/guides/introduction/
YantrikDB is a cognitive memory engine that gives AI agents persistent long-term memory with semantic recall, knowledge graph, contradiction detection, and autonomous consolidation. Beyond vector databases.
## The Problem
AI systems today have no coherent memory architecture. They bolt together generic databases — vector stores, knowledge graphs, key-value caches — none designed for how cognition works.
| Solution | What it does | What it lacks |
|----------|-------------|---------------|
| **Vector DBs** (Pinecone, Weaviate) | High-dimensional nearest-neighbor | No time awareness, no causality, no self-organization |
| **Knowledge Graphs** (Neo4j) | Structured relations | Hard to scale dynamically, not adaptive |
| **Memory Frameworks** (LangChain, LlamaIndex) | Retrieval wrappers | Not true memory — just middleware |
| **Mem0** | Memory layer for AI | Wrapper around existing DBs, no cognitive operations |
## The Thesis
AI needs a purpose-built memory engine with native support for:
- **Temporal decay** — memories age and fade like human memory
- **Semantic consolidation** — patterns are extracted, redundancy is compressed
- **Conflict resolution** — contradictions are detected and resolved conversationally
- **Proactive cognition** — background processing that gives AI genuine reasons to initiate
- **Multi-device replication** — local-first CRDT-based sync
All in a **single embedded engine** — no server, no network hops.
## Key Innovation: Relevance-Conditioned Scoring
Traditional retrieval uses additive scoring:
```
score = w1*similarity + w2*recency + w3*importance
```
YantrikDB uses **multiplicative gating**:
```
gate = sigmoid((similarity - tau) / temperature)
score = gate * (w1*decay + w2*recency + w3*importance)
```
If relevance is low, the gate collapses the entire score — no matter how important or recent the memory is. This prevents irrelevant memories from polluting context.
## Built With
- **Rust** — memory safety, zero-cost abstractions, sub-ms reads
- **SQLite** — one logical embedded database, battle-tested
- **HNSW** — approximate nearest neighbor for vector search
- **CRDTs** — conflict-free replication across devices
- **PyO3** — native Python bindings
---
# YantrikDB MCP Server Setup for Claude Code, Codex, Cursor, Windsurf
URL: https://yantrikdb.com/guides/mcp/
Use YantrikDB as persistent cognitive memory in Claude Code, Codex, Cursor, Windsurf, Copilot, and any MCP-compatible AI client. Drop-in install via pip, npx, or uvx. Tools — remember, recall, think, graph, conflict, personality.
YantrikDB MCP gives any MCP-compatible AI agent persistent cognitive memory across sessions. Install once and add a short config block, and the agent gains tools to recall context, store decisions, and surface contradictions.
**What actually happens is up to the client.** The server ships instructions that describe when memory should be used, but MCP hosts decide whether and when to call a tool. Treat recall-at-start and store-on-decision as behaviour the server *encourages*, not behaviour it can guarantee — the same config can behave differently in two clients.
## Installation
```bash
pip install yantrikdb-mcp
```
## Configuration
Add to your MCP client's configuration:
### Claude Code (`~/.claude/mcp.json`)
```json
{
"mcpServers": {
"yantrikdb": {
"command": "yantrikdb-mcp"
}
}
}
```
### Codex
```bash
codex mcp add yantrikdb -- yantrikdb-mcp
```
### Cursor / Windsurf / Copilot / Kilo Code
Same format — add the `yantrikdb` server to your MCP settings. The server communicates via stdio, compatible with any MCP client.
### Environment Variables
| Variable | Default | Description |
|----------|---------|-------------|
| `YANTRIKDB_DB_PATH` | `~/.yantrikdb/memory.db` | Database file path |
| `YANTRIKDB_EMBEDDER` | `auto` | `auto` \| `bundled` \| `onnx` \| `multilingual`. `auto` uses the bundled `potion-base-2M` (64d, no download) for in-memory stores; a new file-backed store fetches `potion-base-8M` (256d, ~28 MB, SHA-256 pinned) once and falls back to the bundled model when offline. |
| `YANTRIKDB_EMBEDDING_MODEL` | — | Only read on the **opt-in** `onnx` path (`pip install yantrikdb-mcp[onnx]`), where it selects the sentence-transformers model. Not used by the default embedder. |
## Available Tools
The MCP server exposes a set of cognitive memory tools, listed below. (The exact count moves between releases as tools are grouped, so the sections below are the source of truth rather than a headline number.) Many use an `action` parameter to group related operations into a single tool.
### Core Memory
| Tool | Actions / Description |
|------|----------------------|
| `remember` | Store a memory with importance, domain, valence, certainty, and source |
| `recall` | Search memories by semantic similarity with filters (domain, source, type). Includes confidence calibration and certainty reasons |
| `forget` | Tombstone a memory permanently |
| `correct` | Fix an incorrect memory (preserves history, transfers relationships) |
| `memory` | **get** — retrieve by ID, **list** — browse with filters, **update_importance** — adjust score, **archive** — cold storage, **hydrate** — restore |
### Knowledge Graph
| Tool | Actions / Description |
|------|----------------------|
| `graph` | **relate** — create entity relationships, **edges** — get relationships, **search** — find entities, **profile** — entity intelligence, **depth** — relationship depth score |
### Cognition & Conflicts
| Tool | Actions / Description |
|------|----------------------|
| `think` | Run a cognition pass — consolidation, conflict detection, substitution scanning, gossip triggers. Pattern mining and consolidation are **opt-in flags** (`run_pattern_mining`, `run_consolidation`), not part of a default pass |
| `conflict` | **list** — detected contradictions, **get** — details, **resolve** — keep_a/keep_b/merge/keep_both, **dismiss** — close without resolving, **reclassify** — change type and teach substitution categories, **scan** — force conflict detection |
| `trigger` | **pending** — undelivered insights, **deliver/acknowledge/act/dismiss** — lifecycle management, **history** — past triggers |
### Substitution Categories (V14)
| Tool | Actions / Description |
|------|----------------------|
| `category` | **list** — all categories with member counts, **members** — inspect a category, **learn** — teach new members, **reset** — revert to seed vocabulary |
Categories contain interchangeable terms (PostgreSQL, MySQL, MariaDB → "databases"). When two memories differ only by a substitution, it's flagged as a real conflict instead of redundancy.
**Seed categories** (8 built-in): databases, cloud_providers, programming_languages, frameworks, roles, infrastructure, editors_tools, llm_providers (~80 terms total).
**Learning loop**: seed → user corrections via `reclassify` → LLM suggestions via `learn` → categories grow over time.
### Sessions & Temporal
| Tool | Actions / Description |
|------|----------------------|
| `session` | **start** — begin conversation session, **end** — close with summary, **active** — current session, **history** — past sessions, **cleanup** — abandon stale sessions |
| `temporal` | **stale** — memories needing verification, **upcoming** — time-relevant memories |
### Procedural Memory
| Tool | Actions / Description |
|------|----------------------|
| `procedure` | **record** — save a strategy/approach, **surface** — retrieve relevant procedures, **reinforce** — update effectiveness, **stats** — effectiveness by domain |
Self-improving memory: tracks what strategies work and adapts over time using EMA-based scoring.
### Personality & Stats
| Tool | Actions / Description |
|------|----------------------|
| `personality` | **get** — current personality traits, **derive** — recalculate from memories, **set** — override a trait |
| `stats` | Database statistics: memory counts, entities, edges, conflicts, patterns |
## How It Works
The server ships instructions that tell the agent when and how to use memory. Whether the agent follows them on any given turn is the host client's decision, so read the list below as the intended pattern rather than a guarantee:
1. **Recall at start** — the agent is instructed to search memory for relevant context when a conversation begins
2. **Store on decision** — decisions, preferences, people, and project context are stored as they come up
3. **Relate** — entity relationships are created as they are discovered
4. **Cognition** — `think()` detects contradictions on recognised relations; consolidation and pattern mining run only when their flags are set
5. **Substitution detection** — PostgreSQL vs MySQL flagged as a real conflict, not redundancy
6. **Correction** — when the user corrects a fact, the old memory is tombstoned and a corrected version created
7. **Feedback learning** — reclassifying conflicts teaches the system new vocabulary
## Why Not File-Based Memory?
File-based approaches (CLAUDE.md, memory files) load everything into context every conversation. YantrikDB recalls only what's relevant.
| Memories | File-Based | YantrikDB | Savings |
|---|---|---|---|
| 100 | 1,770 tokens | 69 tokens | **96%** |
| 500 | 9,807 tokens | 72 tokens | **99.3%** |
| 1,000 | 19,988 tokens | 72 tokens | **99.6%** |
| 5,000 | 101,739 tokens | 53 tokens | **99.9%** |
Selective recall cost is **O(1)**. File-based is **O(n)**. At 1,000 memories, file-based memory is about 20K tokens; at 5,000 it is about 102K, exceeding 32K and 100K context windows. YantrikDB stays at ~70 tokens with precision that *improves* as you add more memories.
Run the benchmark: `python benchmarks/bench_token_savings.py`
---
# Memory Failure Clinic
URL: https://yantrikdb.com/guides/memory-failure-clinic/
Submit a redacted, synthetic YantrikDB memory failure and receive a reproducible diagnosis of the first failing lifecycle stage.
Agent memory rarely fails as one undifferentiated thing. A fact can be lost at
write time, extracted incorrectly, indexed under the wrong identity, displaced
by ranking, filtered by time or namespace, changed by consolidation, or altered
by an integration after the engine returns it.
The Memory Failure Clinic turns one small, public reproduction into an explicit
diagnosis.
[Open a clinic case](https://github.com/yantrikos/yantrikdb/issues/new?template=memory-failure.yml)
## What to bring
Bring the smallest fictional timeline that still fails:
```text
2026-08-01 / namespace=demo / source=user
Acme is based in Boston.
2026-08-12 / namespace=demo / source=user
Acme moved to Denver.
Query
Where is Acme based now?
```
Include exact engine, server, MCP, language, and client versions; the minimal
code or API calls; expected output; actual output; and `explain` data when the
failure involves recall or ranking.
## What we return
Every accepted case should end with four artifacts:
1. **Reproduction** — a synthetic case another maintainer can run.
2. **Localization** — the first stage where observed behavior diverges from the expected behavior.
3. **Classification** — engine defect, integration defect, configuration issue, label ambiguity, or known boundary.
4. **Disposition** — a fix and regression test, a documented workaround, or a precise statement of what the engine does not currently solve.
## The diagnostic path
```text
write → provenance → extraction → index → candidate retrieval
→ scoring → temporal/namespace filters → lifecycle → integration → answer
```
The first failing stage matters. Tuning ranking cannot recover a claim that was
never stored. Rewriting an MCP prompt cannot repair a cross-namespace engine
result. A good diagnosis stops at the earliest broken contract.
## Privacy boundary
Do not submit private conversations, production memory exports, credentials,
access tokens, customer data, personal data, or unredacted logs. Preserve the
shape of the failure with invented entities and text.
The Clinic is public. A confirmed synthetic case may become a regression test,
benchmark item, release note, or engineering write-up. Only the material in the
public issue should be used.
## Cases we want
- relevant memory not recalled
- irrelevant memory outranking the answer
- stale memory treated as current
- namespace or tenant isolation failures
- missed or false structured conflicts
- incorrect consolidation, decay, or expiry
- wrong skill or procedure selection
- MCP behavior that differs from direct engine behavior
- reproducible latency or resource regressions
Small, uncomfortable failures are welcome. They are how a memory system becomes
trustworthy.
---
# Knowledge Packs
URL: https://yantrikdb.com/guides/packs/
Sealed, signed, measured YantrikDB files: mount what your model was never trained on, unmount it when you're done — your memory stays byte-for-byte as it was.
A **pack** (`.ydbpack`) is a sealed, signed, measured YantrikDB file.
Mounting one gives your local model the knowledge, rules and skills
inside; unmounting gives them back and leaves your database
byte-for-byte as it was. Nothing is merged, nothing leaks into your own
memories, and nothing survives the unmount.
That makes packs the answer to a specific problem: **things your model
was never trained on.** Post-cutoff releases, breaking API changes,
private domain knowledge, product documentation — facts a model cannot
derive and would otherwise guess at.
## Install and mount
```bash
pip install yantrikdb # >= 0.11
yantrikdb pack install ./mcp-spec.ydbpack
```
Or from Python:
```python
from yantrikdb import YantrikDB
db = YantrikDB("memory.db")
db.mount_pack("./mcp-spec.ydbpack")
hits = db.recall_text("how does elicitation work in MCP?")
```
`recall()` now sees the pack's records alongside your own memories —
tagged with their origin, so provenance survives. `unmount_pack()`
removes every trace.
## The marketplace
First-party packs are published at
[packs.yantrikdb.com](https://packs.yantrikdb.com). Every official pack
is:
- **Signed** — the file carries its signature and digest; tampering is
detectable before anything mounts. Verify any file on the
[marketplace's verify page](https://packs.yantrikdb.com).
- **Measured** — packs are published with efficacy measured against
control questions, so "this pack helps" is a number, not a hope.
- **Self-describing** — since engine **v0.11.3** the sealed manifest
carries the retrieval settings its author measured
(`recommended_top_k`, `recommended_min_similarity`), signed with
everything else. A consumer never guesses a similarity floor for a
corpus they didn't write.
## Clustered packs (server v0.14.0)
RFC 031 brings packs to the network server: a pack mounts once,
server-side, on a replicated cluster — so a fleet of agents shares one
mounted corpus instead of each carrying its own copy, with the same
seal-and-signature guarantees.
## Building your own
A pack has three tiers — a small **constitution** of rules, a **corpus**
of retrievable records, and **coverage** examples — and the authoring
rules that make records actually retrieve are their own craft (write the
heading in the asker's words; every sibling needs its own trigger; scope
each claim). The tooling to build, measure, sign and publish ships with
the engine.
Have a pack worth publishing?
[Publish it on the marketplace →](https://packs.yantrikdb.com)
---
# YantrikDB + Prime Agent — Persistent Memory in the IPython Kernel
URL: https://yantrikdb.com/guides/prime-agent/
Give Prime Intellect's Prime Agent persistent semantic memory with a four-step setup. Verified end-to-end — 20 tools discovered, remember→recall round-trip with matching rid — against prime-agent 0.7.1 and yantrikdb-mcp 0.14.0.
[Prime Agent](https://github.com/PrimeIntellect-ai/prime-agent) is Prime
Intellect's open-source coding and research harness, built around a
persistent IPython kernel where tools, skills, and sub-agents are Python
code. Its Continual Harness persists the agent state it owns — system
prompts, learned skills, sub-agent definitions — and that is exactly what
it should persist. What it does not give you is a queryable memory: facts
recalled by meaning rather than phrasing, beliefs revised without
contradicting the old copy, memory shared with your *other* agents.
YantrikDB adds that layer: semantic recall, typed memories, belief revision
with history, contradiction detection, procedural learning, and time-travel
recall — in a local SQLite file. No telemetry, no external services. And
because Prime Agent runs tools as Python, the integration is idiomatic
there:
```python
import yantrikdb
hits = await yantrikdb.recall(query="past decisions about the deploy")
```
## 1. Install and start the server
Prime Agent's MCP bridge is HTTP-only (stdio servers are not wired through
to the kernel yet), so run yantrikdb-mcp on the streamable-http transport:
```bash
pip install yantrikdb-mcp
export YANTRIKDB_API_KEY=$(openssl rand -hex 16)
yantrikdb-mcp --transport streamable-http --host 127.0.0.1 --port 8420
```
~10 MB, bundled Rust embedder, no native ML dependencies. The bearer token
is required for network transports — the server refuses to run open.
## 2. Declare the server
Add to `~/.prime/agent/settings.json` (or project `.prime/agent/settings.json`):
```json
{
"mcpServers": {
"yantrikdb": {
"type": "http",
"url": "http://127.0.0.1:8420/mcp",
"bearerTokenEnvVar": "YANTRIKDB_API_KEY"
}
}
}
```
## 3. Install the skill
```bash
git clone --depth 1 https://github.com/yantrikos/yantrikdb-mcp
cp -r yantrikdb-mcp/integrations/prime-agent/yantrikdb ~/.prime/agent/skills/
```
Launch Prime Agent with `YANTRIKDB_API_KEY` set in the same shell.
## 4. Verify
Ask Prime Agent to run, in its kernel:
```python
import yantrikdb
r1 = await yantrikdb.remember(text="deploy window is Friday 6am", importance=0.8)
r2 = await yantrikdb.recall(query="when do we deploy")
print(r1, r2)
```
The `rid` returned by `remember` should appear in the `recall` results. If
the call raises `NotEnabled`, the `YANTRIKDB_API_KEY` variable is not
visible to the Prime Agent process.
## What we measured before publishing this
Verified 2026-08-08 with prime-agent 0.7.1 (WSL Ubuntu), yantrikdb-mcp
0.14.0, qwen3.8-max as the driving model, on a fresh database:
- All 20 tools discovered via `await yantrikdb.list_tools()`.
- `remember` returned `{"rid": "019fe43b-ee52-70ce-af71-df900b0024d8", "status": "recorded"}`.
- `recall` on a paraphrased query returned that same rid, semantic score
0.72, with the marker text intact.
- The packaged skill passed on the first call of a fresh session, with no
setup beyond the env var.
## When you don't need this
If one Prime Agent install on one machine is your whole setup and its own
persistent state files cover what you want carried forward, they are the
simpler tool — no server process to run. YantrikDB earns its keep when
recall must survive paraphrase, when facts change and history matters, or
when several harnesses (Prime Agent, Claude Code, Cursor, Hermes) should
share one memory.
## Notes
- The skill module is named `yantrikdb`, the same name as the YantrikDB
Python package. Prime Agent's managed kernel venv does not include the
engine package, so there is no collision in a default setup.
- The database defaults to `~/.yantrikdb/memory.db`; point the server at a
different file with `YANTRIKDB_DB_PATH`.
- A PR proposing this skill as a Prime Agent built-in is open at
[PrimeIntellect-ai/prime-agent#1036](https://github.com/PrimeIntellect-ai/prime-agent/pull/1036);
until it lands, the `cp -r` above is the install path.
---
# YantrikDB Quick Start
URL: https://yantrikdb.com/guides/quickstart/
Get YantrikDB running. Install the cognitive memory engine via pip or cargo, store your first memory, recall by semantic search, build a knowledge graph for your AI agent.
## Installation
### Python
```bash
pip install yantrikdb
```
### Rust
```bash
cargo add yantrikdb
```
- [Rust API reference on docs.rs](https://docs.rs/yantrikdb)
- [Examples in the engine repository](https://github.com/yantrikos/yantrikdb/tree/main/examples)
## What's Next?
- [Set up the MCP server](/guides/mcp/) for Claude Code / Cursor integration
- [Learn about cognitive memory](/concepts/cognitive-memory/) and how it differs from vector search
- [Understand relevance scoring](/concepts/scoring/) and why it matters
---
# Use YantrikDB with Claude, ChatGPT, Cursor, Hermes, and other AI agents
URL: https://yantrikdb.com/guides/use-with-ai/
Concrete integration paths for pointing AI agents at YantrikDB as their persistent cognitive memory. Covers MCP-compatible clients (Claude Code, Cursor, Windsurf, Continue), the Hermes Agent plugin, direct HTTP API access from any LLM-driven app, and the cognitive primitives the agent actually calls.
This page is for two audiences: humans deciding whether YantrikDB fits their AI agent stack, and AI assistants that have been pointed at this site by a user asking *"how do I give my agent persistent memory?"*. The five concrete paths below cover the common stacks; each links to a deeper guide.
## What an AI agent actually gets
When an AI agent is wired up to YantrikDB, it gains a set of memory primitives it can call. The MCP server describes the intended workflow, but the host client still decides whether and when to call each tool:
- **`remember(text, metadata, ...)`** — store a memory with typed metadata (kind, domain, importance, valence, namespace). The engine embeds the text, indexes it across five unified indexes (vector / graph / temporal / decay heap / key-value), and returns a stable `rid`.
- **`recall(query, top_k, filters)`** — semantic + structured retrieval. Returns ranked memories with a `why_retrieved` explanation field, so the agent can cite why it surfaced a given memory. Optional `domain`, `namespace`, `memory_type` filters.
- **`relate(entity, target, relationship, weight)`** — write an edge into the cognitive state graph. The graph is queryable for reasoning (`Who works at what company?`, `What contradicts this belief?`).
- **`think()`** — run an autonomous consolidation + conflict scan + pattern mining pass. Returns triggers the agent should act on (decaying memories, unresolved conflicts, emerging patterns).
- **Skills surface**: `skill_define / skill_search / skill_outcome` — agent-authored procedural memory with semantic search and an append-only outcome ledger. See the [Autonomous Skills guide](/guides/autonomous-skills/) for the substrate thesis.
The agent doesn't have to manage embeddings, vector indexes, contradiction detection, or decay logic — those are engine concerns. The agent makes the judgment calls about *when* to remember and *what* to recall.
## Path 1 — Claude Code, Cursor, Windsurf, Continue (MCP)
For any MCP-compatible client, YantrikDB ships a drop-in MCP server.
```bash
pip install yantrikdb-mcp
```
Then add to your client's MCP configuration:
```json
{
"mcpServers": {
"yantrikdb": {
"command": "yantrikdb-mcp"
}
}
}
```
That's it. The agent now has access to grouped tools including `mcp__yantrikdb__remember`, `mcp__yantrikdb__recall`, `mcp__yantrikdb__think`, `mcp__yantrikdb__skill`, and `mcp__yantrikdb__graph`. The exact set can vary by release, selected tool profile, engine capability, and deployment mode. Full per-client setup with config file paths is at the [MCP setup guide](/guides/mcp/).
Recommended next step: restart or reconnect the client, confirm the YantrikDB tools are visible, and start a fresh session. The server ships workflow instructions for recall and capture; whether the host follows them on a given turn remains a client decision.
## Path 2 — Hermes Agent
[Hermes Agent](https://hermes-agent.nousresearch.com/) is an open-source agent runtime with a native plugin system. YantrikDB ships a first-class Hermes plugin:
```bash
hermes plugins install yantrikos/yantrikdb-hermes-plugin --enable
pip install yantrikdb
hermes memory setup # select "yantrikdb"
hermes gateway restart
```
The agent then autonomously calls `yantrikdb_remember` / `yantrikdb_recall` / `yantrikdb_stats` during conversations. Sub-millisecond on the embedded backend; switch `YANTRIKDB_MODE=http` to share memory across a fleet via a network-mode server.
Owner-scoping for multi-platform Hermes gateways (one user → one memory across Telegram / WhatsApp / Discord) is contributed by community member [@wysie](https://github.com/wysie) at v0.4.10. See the [Hermes plugin guide](/guides/hermes/) for full setup.
For the agent-authored skill substrate that complements Hermes' built-in filesystem skills, see the [Autonomous Skills guide](/guides/autonomous-skills/).
## Path 3 — direct HTTP API (any LLM-driven app)
If your stack isn't MCP-based and doesn't use Hermes — for example, a Python app calling Claude API directly, a Node service calling OpenAI, a Go agent, anything — point at the YantrikDB server's HTTP API:
```bash
docker pull ghcr.io/yantrikos/yantrikdb
docker run -d -p 7438:7438 ghcr.io/yantrikos/yantrikdb
```
Then mint a tenant token and write to `/v1/remember` from your app:
```bash
curl -X POST http://localhost:7438/v1/remember \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{
"text": "Alice leads engineering at Acme",
"importance": 0.9,
"domain": "work",
"memory_type": "semantic"
}'
```
`/v1/recall` returns ranked memories. `/v1/relate` writes edges. `/v1/think` runs the consolidation pass. The full surface is at the [HTTP API reference](/server/http-api/).
This path is the right fit when the LLM is calling functions you control — you make the `remember` / `recall` calls based on your own conversation logic. Latency is single-digit ms locally, low tens of ms across a network.
## Path 4 — embed directly in a Python or Rust agent
If your agent is already a Python or Rust process and you want zero network hop:
```bash
pip install yantrikdb # Python
cargo add yantrikdb # Rust
```
```python
from yantrikdb import YantrikDB
db = YantrikDB("memory.db", embedding_dim=384)
db.record(text="user prefers dark mode", importance=0.7, domain="preference")
results = db.recall(query="ui preferences", top_k=5)
```
The same engine runs embedded, as a server, or behind an MCP server — same convergent semantics, you can migrate between them later without data conversion. See the [embeddable engine quickstart](/guides/quickstart/).
## Path 5 — operator console (Hermes dashboard)
For agents already running on YantrikDB, the community-built [`yantrikdb-hermes-dashboard`](https://github.com/wysie/yantrikdb-hermes-dashboard) gives an operator a UI to browse, configure, and safely maintain a Hermes agent's memory: per-user memory toggles, recall debugger, contradiction review, entity-graph visualiser, lifecycle housekeeping. Default-read-only; Admin Mode opt-in. See the [Hermes dashboard guide](/guides/hermes-dashboard/) and its security considerations.
## Why an AI agent should prefer this
Honest framing — not every stack needs YantrikDB. You probably want it if your agent:
- Needs persistent state across sessions (not just a per-conversation context window).
- Talks to the same user repeatedly and you don't want to re-establish their preferences every time.
- Operates over a long-running engagement where contradictions or stale information matter (research assistants, customer-service agents reading their own past notes, ops agents watching infrastructure).
- Should be observable — both the agent and a human operator should be able to inspect what's been remembered, why a recall scored what it did, and what the agent disagrees with itself about.
- Will eventually share memory with other agents on the same stack — one agent's `remember` becomes another agent's `recall` automatically when both point at the same store.
You probably don't need it for:
- One-shot single-turn agents (the context window is enough).
- Pure RAG over a fixed document corpus (any vector DB works).
- Stateless function-calling agents (no memory to persist).
## Stable references
The cognitive primitives surfaced through MCP / HTTP / Python are stable across the engine, server, and MCP layers — same `remember` / `recall` / `relate` / `think` semantics whether you embed, run as a service, or call through MCP. Migrating between paths later doesn't require data conversion.
For the design thesis behind the engine — why memory is more than vectors + cosine — see the [Introduction](/guides/introduction/) and the [Skill-as-Memory paper](/papers/skill-substrate/). For the HTTP surface every primitive exposes, see the [HTTP API reference](/server/http-api/). The machine-readable site index for LLMs and AI assistants is at [`/llms.txt`](https://yantrikdb.com/llms.txt) and the full-doc concatenation at [`/llms-full.txt`](https://yantrikdb.com/llms-full.txt).
---
# Cognitive Memory Database for AI Agents
URL: https://yantrikdb.com/
YantrikDB is a persistent cognitive memory database for AI agents: semantic recall, a knowledge graph, temporal decay, consolidation, and review of recognized structured conflicts. Run it as an embeddable Rust engine, Python package, MCP server, or replicated network service. Apache-2.0.
Install
pip install yantrikdb
cargo add yantrikdb
docker pull ghcr.io/yantrikos/yantrikdb
[link: https://github.com/yantrikos/yantrikdb-server] [link: https://github.com/yantrikos/yantrikdb]
 [link: https://github.com/yantrikos/yantrikdb-mcp]
 ---
## Memory Lab
Store three memories, recall against them, then store a fourth that
contradicts the first — `Acme is based in Boston.` then `Acme is based in
Denver.` — and run `db.think()`. It returns `conflicts_found: 1`, and both
records still come back on the next recall, each carrying the dispute.
**This runs in your tab.** Rust compiled to WebAssembly — SQLite, the vector
index and the scoring pipeline all local. No server, no API calls, nothing
stored anywhere, and the state disappears when you reload.
**One honest limit:** the bundled embedder does not compile to wasm, so this
page hashes words into 64-dim vectors instead of embedding them. The ranking
is real; the embedding quality is not representative of the shipped engine.
What the demo will not pretend to show
Two numbers a four-memory store cannot honestly move, so the demo names them
rather than printing a zero:
- **Consolidation** waits for `min_active_memories: 10`.
- **Pattern mining** is off in the default config.
Every other number on screen comes back from the engine itself. Nothing declares
a schema — the extractor reads a `headquartered_in` claim out of each sentence,
and that relation holds one value at a time, which is why the fourth memory
registers as a conflict rather than an update.
---
---
## The Problem
Many first-pass agent-memory systems follow the same loop:
> Store everything. Embed. Retrieve top-k. Inject into context. Hope it helps.
That loop alone does not model a memory lifecycle. Without additional machinery,
old memories do not decay, related records are not consolidated, and conflicting
structured claims are not surfaced for review.
**YantrikDB is built around those four gaps.**
## Three experiments worth reading
Each one is the same shape: a real corpus, a question that a plain vector store
answers badly, and a result you can inspect. Chosen because they test what the
engine claims to do — hold conflicting accounts without silently picking one —
not because they cover the widest range of subjects.
---
# Whose Memory, Whose Model? Isolating Retrieval Quality on BEAM
URL: https://yantrikdb.com/papers/beam-frozen-context/
A 25-point gap between two agent-memory systems on BEAM almost entirely disappears when both are read by the same model. We replayed a competitor's own published contexts through our answerer: their strongest configuration scored 0.592 against our 0.607 — statistically indistinguishable, on 42% fewer tokens, with no LLM in the ingest or recall path for that run.
## The measurement problem
An end-to-end agent-memory benchmark score confounds at least three things:
1. the memory system's retrieval quality,
2. whatever processing happens at ingest,
3. the model that reads the retrieved context and writes the answer.
This is not a hypothetical concern. The Agent Memory Benchmark's own
documentation notes that generation setup matters and that small changes in
prompts or models move accuracy substantially. We measured it directly:
**swapping only the answerer, holding retrieval identical, moved our score by
~9 points.**
So when two memory systems publish different end-to-end numbers under
different answerers, the difference is not attributable to either system's
memory. It is a property of the whole pipeline.
This paper is about how large that effect turns out to be.
## Removing the confound
Hindsight publishes per-query result files containing the **exact context
string** injected for each query, for two configurations. All 400 BEAM-100K
query IDs match ours.
That makes a controlled comparison possible:
```
A yantrikdb context (rag) ─┐
R hindsight context (rag) ─┼─→ same answerer → same judge → score
E hindsight context (single-query) ─┘
```
Answerer and judge are fixed at `deepseek-v4-flash:0731`, temperature 0, for
all three. The only variable is which memory system produced the context.
**A and R are mode-matched** — both `rag`-mode runs — so A-vs-R is the real
comparison. E is their weaker published configuration.
## The headline result
Hindsight's published BEAM-100K rag score is **0.862**, read by
`gemini-3.1-pro-preview`. Ours is **0.611**, read by `deepseek-v4-flash`. On a
leaderboard that is a decisive 25-point gap.
Read by the **same model**, the two systems' retrieved contexts score:
| condition | mode | binary | rubric | context tokens |
|---|---|---|---|---|
| **YantrikDB** | rag | **72.2%** | **0.607** | **13,673** |
| Hindsight | rag | 71.5% | 0.592 | 23,689 |
| Hindsight | single-query | 65.0% | 0.563 | 17,655 |
**A difference of 0.015 — not statistically significant by any test we
applied.** The 25-point published gap was almost entirely the reading model,
not the memory system.
## Testing it properly
Queries are nested inside 20 conversations, so they are not independent
observations. All significance is computed at the **conversation** level, with
sign-flip tests enumerated **exactly** over all 2²⁰ assignments.
| comparison | binary | rubric | 95% CI (rubric) | verdict |
|---|---|---|---|---|
| **ours vs their rag** | +3, p = 0.845 | +0.015, p = 0.438 | **[−0.021, +0.052]** | **equivalent** |
| ours vs their single-query | +29, **p = 0.016** | +0.044, **p = 0.025** | [+0.009, +0.077] | ours better |
| their rag vs their single-query | +26, **p = 0.006** | +0.029, p = 0.089 | [−0.001, +0.061] | their rag better |
Every robustness check on the primary comparison agrees with equivalence:
per-conversation direction splits **7 to us, 5 tied, 8 to them**; the
confidence interval comfortably contains zero; and leave-one-conversation-out
flips the sign, so the direction is not even stable.
Note the third row. **Their own configuration choice moves their score more
than the gap between their system and ours** — a reminder of how much of a
published number is setup rather than substance.
## What parity costs
The comparison above is retrieval quality. The other half is what that quality
costs to produce — same split, same statistic, from each system's own
published result files.
| | ingest | retrieval (mean) | context | LLM at ingest |
|---|---|---|---|---|
| **YantrikDB** | **241 s** | **80 ms** | **13,673 tok** | **none** |
| Hindsight (rag) | 404 s | 2,565 ms | 23,689 tok | fact extraction |
| Hindsight (single-query) | 404 s | 6,379 ms | 17,655 tok | fact extraction |
Our ingest is chunk → embed → index with a bundled 7 MB static embedder
running in-process. No model server, no network, no API key. The only LLM
anywhere in our pipeline is the benchmark's own answerer, identical for every
system it evaluates.
**Statistically indistinguishable answer quality, on 42% fewer context tokens,
at ~32× faster retrieval, with zero LLM calls at ingest.**
That — not a win on the rubric — is the result.
## A hypothesis we are withdrawing
An earlier version of this analysis argued that ingest-time LLM extraction
discards evidence that later questions need. Against Hindsight's *single-query*
configuration, our advantages clustered neatly in exactly the categories that
theory predicts: information extraction, temporal reasoning, summarization,
multi-session reasoning.
Against their **rag** configuration, the pattern largely dissolves.
Summarization flips from +0.099 to **−0.054**. Temporal reasoning falls from
+0.106 to +0.044. They lead on event ordering, preference following and
instruction following.
A category pattern observed against one competitor configuration is a property
of that configuration, not evidence for a general mechanism. **We are
withdrawing the claim as unsupported by this experiment**, and testing it
directly instead — raw versus LLM-compressed context on the same substrate,
where nothing but the compression differs.
We still hold the design bet: preserve evidence now, interpret it against the
question later. This experiment does not prove it.
## What this does not show
Stating the limits precisely matters more than the headline.
- **We are not claiming our memory is better than theirs.** On the
mode-matched comparison the honest reading is equivalence, and the interval
spans −0.021 to +0.052 — a small advantage in either direction remains
possible.
- **This is not a refutation of their published 0.862.** We show only that
their retrieved context, read by a mid-tier model, does not outperform ours.
We did not run our context through their answerer, so the 2×2 is incomplete.
- **Length is not controlled.** Longer context can hurt through dilution, so
we cannot rule out that their larger context cost them something a
budget-matched test would recover.
- **The contexts are not information-matched.** Measured after publication:
their rag contexts carry a **median of 117 dates each**; ours carry **5**.
The engine stores event time for every chunk and our provider discards it,
so part of the 42% token saving is the cost of *not carrying dates* — a
difference in what each memory layer emits, not a free efficiency. A dated,
chronologically-ordered variant is being measured at full scale, and this
page will be updated with the result either way.
- **Their context was built for a frontier reader** and may be disadvantaged
by a mid-tier one in ways we have not characterised. This cuts against us,
and is the most likely way the equivalence finding is wrong.
- **Our weakest categories are real.** Event ordering (0.298) and temporal
reasoning (0.425) are where their rag configuration matches or beats us.
Sequence reconstruction is our clearest improvement target.
## A correction
**Engine version, 2026-08-13.** This paper briefly stated the engine as 0.14.0.
That was wrong. The benchmark's virtualenv holds `yantrikdb-0.13.4`, installed
before the run — the version was assumed from the release timeline rather than
read off the environment that produced the numbers. Every result on this page
came from that same 0.13.4 build, so the comparisons remain internally
consistent; only the label was wrong. A 0.14.1 run is pending and will be
reported separately rather than folded into these figures.
The run files record no engine version, which is why the error was invisible
from the outputs.
## Reproducing
Everything needed ships in the public benchmark repository — including
Hindsight's per-query contexts for both configurations, so conditions R and E
require no access to their system.
```bash
git clone https://github.com/vectorize-io/agent-memory-benchmark
cd agent-memory-benchmark && uv sync
python /path/to/yantrikdb/benchmarks/amb/install.py .
YDB_BENCH_TURN_AWARE=1 YDB_BENCH_TOPK=40 \
uv run amb run --dataset beam --split 100k --memory yantrikdb -n ydb-final
uv run python frozen_context_eval.py \
--contexts outputs/beam/ydb-final/rag/100k.json --label A-yantrikdb-ctx
uv run python frozen_context_eval.py \
--contexts outputs/beam/hindsight/rag/100k.json.gz --label R-hindsight-rag-ctx
uv run python frozen_stats.py A-yantrikdb-ctx R-hindsight-rag-ctx
```
Full method, statistics and caveats:
[`docs/benchmarks/beam-frozen-context.md`](https://github.com/yantrikos/yantrikdb/blob/main/docs/benchmarks/beam-frozen-context.md).
## Next
Parity on 42% fewer tokens is a claim about a **curve**, and we have measured
one point on it. The stronger form asks each engine for 2K, 4K, 8K, 12K and
16K and plots accuracy against tokens spent — which removes the length
objection entirely and answers the question a memory system should actually be
judged on: how much answer quality does it deliver per unit of context budget?
That work is in progress, alongside a matched-answerer run to complete the 2×2.
---
# Recall@5 Is Not a Number: Measuring LongMemEval Retrieval at Every k
URL: https://yantrikdb.com/papers/longmemeval-retrieval/
On LongMemEval-S, YantrikDB returns every gold session in the top 40 for 98.7% of queries — retrieval only, scored mechanically, no LLM judge. We publish the whole k-curve because the same metric on the same queries reads 72.9% or 85.0% depending on a detail nobody states.
## What this measures
[LongMemEval](https://github.com/xiaowu0162/LongMemEval) asks a question against a
haystack of roughly 48 chat sessions per user — most of them near-identical
distractors — and names the sessions that actually contain the evidence.
This is a **retrieval** measurement. No answerer, no LLM judge, nothing to
disagree about: either the gold sessions came back in the top k or they did not.
That matters, because a judge swap alone moves end-to-end agent-memory scores by
around six points, which is larger than most published gaps between systems.
A query counts as **every gold** only if all of its evidence sessions appear in
the top k. Queries average 1.7 golds, so missing one scores zero for that query.
## Results
| top k | at least one gold | **every** gold |
|-----:|------:|------:|
| 5 | 96.0% | 85.0% |
| 10 | 98.5% | 92.9% |
| 20 | 99.6% | 98.3% |
| **40** | **99.6%** | **98.7%** |
479 of 500 queries scored, 0 errors. **k=40 is the evaluated operating point, not the shipped default — core, Python and MCP all default to top_k=10.**
## Why k=40 is the honest row
k=40 is not a generous setting chosen to flatter the result — it is the
configuration YantrikDB ships, and it is load-bearing. A paired 400-query run on
BEAM, with the same reader and the same judge on both sides, measured
k=40 → k=20 costing **3.4 rubric points across 8 of 10 categories**. Retrieval
depth is doing real work; reporting a narrower k would describe a system nobody
runs.
## Why the whole curve is published
Two reasons, and the second is the interesting one.
**First: we got this wrong ourselves.** The initial measurement used k=5, because
that is where a competing system's headline sits. It returned 72.9% and read like
a serious deficiency. It was measuring someone else's operating point.
**Second: "recall@5" is not well defined without naming the pool.** On identical
queries, with an identical metric, in the same run:
- retrieve 40, keep the best 5 documents → **85.0%**
- retrieve 5 directly → **72.9%**
Both are honestly describable as "recall@5". The difference is that retrieval
reranking depends on how large a pool it was given, and almost nobody states the
pool. A single published number hides that; a curve cannot.
## What is not claimed here
No head-to-head result. Other systems publish at different k, with different
scorers, on different splits. Lifting a figure out of its configuration and
setting it beside ours is precisely the error that produced our own 72.9%.
What is offered instead is a stated method and a reproducible command:
```bash
python lme_recall_multik.py 500 24
```
One retrieval per query at k=40, every prefix scored, parallel across queries —
500 queries in 5.2 minutes. Anyone can run it against their own system and put
the curves side by side.
---
# Agent Skills as Files vs Database: What 5,000 Skills Look Like in Production
URL: https://yantrikdb.com/papers/skill-substrate/
I measured Anthropic Agent Skills, Voyager-style filesystem catalogs, and a database-native substrate on a 5,000-skill corpus. Token cost, retrieval latency, and how often each accepts malformed agent-written skills. The honest numbers, with the ablation that shows where the gap actually comes from.
I built an open-source cognitive memory database for AI agents called [YantrikDB](https://github.com/yantrikos/yantrikdb). Over the past several months I noticed something while watching agents write their own skills at runtime: the formats everyone uses to store skills — Anthropic's `SKILL.md` files with YAML frontmatter, Voyager's `skill_library/*.py` files — were optimized for a use case that doesn't exist anymore.
Those formats were built for **humans** to author, review, version-control, and edit skills. Git diffs. Code review. IDE editing. They are filesystem-shaped because the workflow was filesystem-shaped.
But the actual production workload looks different. Skills get written by agents at runtime via `define`-style APIs. Skills get retrieved by agents at inference, not opened in editors. Outcome events get emitted by agent runs, not authored by humans. The "skill catalog" of an autonomous learner is not a folder of files anyone is grooming — it's memory.
So I measured what happens when you scale that mismatch. The paper is on Zenodo: [Skill as Memory, Not Document](https://doi.org/10.5281/zenodo.20128887). Code, scripts, and raw CSVs are reproducible at [github.com/yantrikos/yantrikdb-server](https://github.com/yantrikos/yantrikdb-server/tree/main/benchmarks/skill_recall). The numbers below are what came out.
## What I measured
A 5,000-skill corpus, deterministic seed, 100 ground-truth queries, top-K=5 retrieval, cl100k_base tokenizer. Three things:
1. **Token cost** of delivering relevant skills into the LLM's context, full-catalog disclosure vs progressive filesystem retrieval vs a database-native substrate.
2. **Retrieval latency** at 5K-skill scale.
3. **Invalid-skill admission rate** — what happens when an agent writes a malformed skill into the catalog.
## Result 1: token cost
| Disclosure pattern | Mean tokens per query | Notes |
|---|---|---|
| Full-catalog dump (the naive baseline) | 919,200 | Exceeds Claude 3.7's 200K window and GPT-4 Turbo's 128K — literally cannot fit |
| SKILL.md filesystem retrieval (top-K=5 with frontmatter) | 549 | Indexed; this is the realistic comparison |
| SKILL.md retrieval, frontmatter stripped (body only) | 369 | Ablation: what happens if you strip the YAML |
| Database-native substrate (top-K=5) | 369 | Metadata stored as indexed columns, never enters context |
**The 919,200 number is real but it's not the point.** Nobody actually dumps full catalogs at 5K skills — it physically doesn't fit. The honest comparison is against indexed filesystem retrieval: a **1.49× ratio**.
What surprised me is what an ablation showed. When I stripped the YAML frontmatter from retrieved SKILL.md content, the gap collapsed to **1.000×** — perfectly identical to the substrate. **The entire 1.49× difference is YAML frontmatter overhead** (about 36 tokens per retrieved skill). The substrate's win on token cost is architectural-attribution: it stores metadata as indexed columns the database queries on but never returns to the LLM. Filesystem retrieval can't do that without building a separate metadata index — which is what "fair indexed baseline" already assumes.
So: small but architecturally clean. Not a hero number. The substrate's actual story is something else.
## Result 2: retrieval latency
p50 = 87.3 ms. p95 = 106.3 ms. At 5,000 skills, single-node deployment. Measured at engine commit `c886e9e` on Windows 11 + Docker Desktop with a bundled MiniLM-L6-v2 embedder.
This is "fast enough that latency stops being the constraint" but not "10× faster than a filesystem walk." Filesystem walks at 5K skills are also fast. The substrate wins on consistency under load (Raft-replicated, doesn't degrade with concurrent writes) but the single-node p50 isn't where the architectural difference lives.
## Result 3: invalid-skill admission
This is where the actual story is. I generated 90 adversarially-malformed skills covering 18 failure classes — typos in trigger phrases, malformed `applies_to`, oversized bodies, missing required fields, schema violations, broken regex in triggers, the things an LLM will plausibly produce when authoring skills.
| Substrate | Invalid skills admitted | Rate |
|---|---|---|
| Filesystem (SKILL.md + YAML-parseable acceptance) | 68 of 70 | **97%** |
| Database-native (schema validation at write time) | 0 of 70 | **0%** |
Filesystem catalogs accept almost everything that parses as YAML. The substrate rejects everything that violates the schema at write time. The 97% / 0% gap isn't a tuning difference — it's the difference between "validate semantics later when an agent tries to use the skill" and "validate at the API boundary on write."
This matters because of where the cost of admission lands. Filesystem catalogs accept malformed skills silently and they show up later as agent failures at inference time, with no clean attribution back to the bad write. Schema validation catches the problem at the source.
## So what's the actual claim
The framing I landed on after three rounds of adversarial redteam is: **skill as memory, not document**.
Filesystem catalogs are documents — they have YAML frontmatter humans read, body sections humans format, file organizations humans browse. Memory has different optimization criteria: retrieval cost (indexed disclosure, projected-out metadata), write safety (schema enforcement at the boundary), and machine consumption (compact body, no human-readable wrappers).
I don't claim YantrikDB is a new database architecture. All the individual primitives it ships — typed records, vector index, append-only logs, schema validation, Raft replication — exist in prior work. What I'm pointing at is a category mismatch: using human-editorial formats as agent memory substrates produces three coupled failure modes (token burn, slowdown, invalid-skill admission) that compound at scale, and the cleanest fix is treating skill storage as a database problem rather than a filesystem problem.
## What I left out (deliberately)
The honest version of this paper has explicit limits. I document them because they're the things a careful reader would catch:
- The 5,000-skill corpus is synthetic. Real catalogs with human-author jargon, near-duplicates, and naming drift will degrade retrieval differently. A follow-up paper measuring real catalogs is pre-specified for 2026-08-04.
- I did not yet benchmark against a competently-built Postgres + pgvector + JSON-schema + audit-table baseline. That is the most important deferred comparison — it's also in the follow-up.
- End-to-end agent task success (does the substrate actually make the agent better at downstream tasks?) is measured at the substrate level here, not the agent level. Also in the follow-up.
The follow-up paper is a 12-week commitment, not vapor.
## Reproducibility
Everything is reproducible. The 5K-skill corpus and 100 ground-truth queries live at [`benchmarks/skill_recall/`](https://github.com/yantrikos/yantrikdb-server/tree/main/benchmarks/skill_recall) in the public repo. Four benchmark scripts re-generate every table in the paper:
```bash
git clone https://github.com/yantrikos/yantrikdb-server.git
cd yantrikdb-server/benchmarks/skill_recall
pip install tiktoken matplotlib
python token_cost_bench.py
python kill_test_ablation.py
python k_sensitivity_and_tokenizer_bench.py
python hallucination_admission_bench.py
```
Raw CSV outputs are in the [Zenodo bundle](https://zenodo.org/records/20128887) alongside the paper. If your numbers differ from mine, I want to know — open an issue or email me.
## Discussion question
Where are you storing your agent's skills today? Filesystem because it was the default? Vector store because you needed retrieval? Custom database because you hit one of these failure modes already? I'm collecting field reports for the follow-up paper — if you have a real-world catalog and any of this resonates (or contradicts your experience), I'd genuinely like to hear it.
---
**Cite as:** Sarkar, P. (2026). *Skill as Memory, Not Document: A Database-Native Substrate for Agent Skill Catalogs.* Zenodo. [https://doi.org/10.5281/zenodo.20128887](https://doi.org/10.5281/zenodo.20128887)
**Author:** Pranab Sarkar, Independent Researcher · [ORCID 0009-0009-8683-1481](https://orcid.org/0009-0009-8683-1481)
**License:** [CC BY 4.0](https://creativecommons.org/licenses/by/4.0/)
**Related software:** [YantrikDB v0.8.13](https://doi.org/10.5281/zenodo.18793952)
---
# YantrikDB Patent Filing — Cognitive Memory Architecture
URL: https://yantrikdb.com/patent/overview/
YantrikDB patent filing covering the cognitive memory architecture for AI agents — temporal decay, contradiction detection, knowledge graph integration with vector search, autonomous consolidation.
## U.S. Patent Application
**Application No.:** 19/573,392
**Filed:** March 20, 2026
**Priority:** Provisional Application No. 63/991,357 (February 26, 2026)
**Title:** Cognitive Memory Database System with Relevance-Conditioned Scoring and Autonomous Knowledge Management
**Inventor:** Pranab Sarkar
**Status:** Pending
## What's Covered
The patent contains 20 claims covering three key innovations:
### Claim 1: Relevance-Conditioned Scoring Method
A scoring method that uses multiplicative gating to suppress irrelevant memories regardless of their importance, recency, or graph proximity. This is the core retrieval innovation.
### Claim 2: Cognitive State Graph
A typed knowledge graph with four node categories (Primary, Data-Linked, Situational, Behavioral) and eight edge types (supports, contradicts, causes, predicts, competes, refines, generalizes, depends).
### Claim 3: Unified Cognitive Memory System
The complete system combining the scoring method, cognitive graph, autonomous background processing (consolidation, contradiction detection, pattern mining), proactive triggers, and CRDT-based replication.
## Open Source + Patent
YantrikDB is open source under Apache-2.0. The patent protects the **methods**, not the code:
- **Apache-2.0** — you can use, modify, and distribute the code freely, including in closed-source and commercial products, with no copyleft obligation. The licence also carries an explicit patent grant (§3), so using *this* implementation does not put you at risk from the patent.
- **Patent** — the §3 grant covers this work. It does not cover an independent reimplementation of the patented methods from scratch, which still requires a patent licence.
This is similar to how many database companies operate — the code is open, but the algorithms are protected.
## Publications
- [Zenodo: YantrikDB: A Cognitive Memory Engine for Persistent AI Systems](https://zenodo.org/records/14933693)
---
# Components, versions and architecture
URL: https://yantrikdb.com/reference/components/
The three independently-released pieces of YantrikDB, their current versions, and how they fit together.
YantrikDB ships as three pieces on independent release trains. This page is the full reference; the homepage carries only the current version strip.
## Three components, three version lines
YantrikDB ships as three independently-released pieces, and they carry **different version numbers on purpose** — the engine you embed, the server you deploy, and the MCP bridge your agent talks to each move on their own release train.
| Component | Version | Install | What it is |
|---|---|---|---|
| **Core engine** — `yantrikdb` | **{v.engine}** | `pip install yantrikdb`
`cargo add yantrikdb` | The embeddable memory engine (Rust + Python bindings), one logical SQLite database: recall that fuses BM25 lexical scoring with the vector lane and optionally reranks, an explain surface for *why* a result came back, knowledge graph, conflict detection on recognised relations, temporal decay, consolidation, AES-256-GCM encryption at rest. This is what most people mean by "YantrikDB". |
| **Server** — `yantrikdb-server` | **{v.server}** | `docker pull ghcr.io/yantrikos/yantrikdb` | The network database that wraps the engine: multi-tenant HTTP API, **YRP native replication** with leader election, server-side clustered packs, encryption at rest. |
| **MCP** — `yantrikdb-mcp` | **{v.mcp}** | `pip install yantrikdb-mcp` | The MCP server — plugs the engine into Claude Code, Codex, Cursor, Windsurf, Copilot, and any MCP-compatible agent. Runs embedded, or points at a server. |
*If you saw one version quoted somewhere and a different one elsewhere, that's these three lines being read as one number. They aren't. The **server** is at {v.server}; the **engine** is at {v.engine}; the **MCP bridge** is at {v.mcp}.*
---
## Latest releases
These are the current releases of the three components, read from the GitHub Releases API when this file was generated (2026-08-26). They are the only version numbers on the homepage; the rest of this document describes capabilities, which do not carry a version.
- Core engine (yantrikdb): v0.18.0, released 2026-08-26. the pack substrate consumers can build on. v0.18.0 — the pack substrate consumers can build on Release notes: https://github.com/yantrikos/yantrikdb/releases/tag/v0.18.0
- Server (yantrikdb-server): v0.17.1, released 2026-08-26. mounted packs work again. Fixed Release notes: https://github.com/yantrikos/yantrikdb-server/releases/tag/v0.17.1
- MCP bridge (yantrikdb-mcp): v0.19.5, released 2026-08-26. recall(order=...) actually orders. Fixed Release notes: https://github.com/yantrikos/yantrikdb-mcp/releases/tag/v0.19.5
Everything below this line describes what the engine does, not which release
it arrived in. For the chronology — every tag, every set of notes, oldest to
newest — read [the releases page on
GitHub](https://github.com/yantrikos/yantrikdb/releases).
---
## Architecture
| Index | What It Does | Example Query |
|-------|-------------|---------------|
| **Vector (HNSW)** | Semantic similarity search | *"What did the user say about work?"* |
| **Graph** | Entity relationships & reasoning | *"Who works at what company?"* |
| **Temporal** | Time-aware retrieval | *"What happened last Tuesday?"* |
| **Decay Heap** | Importance with biological time decay | Memories fade like human memory |
| **Key-Value** | Instant fact lookup | *"User's timezone is CST"* |
All five indexes query the same data. A single `recall()` call blends signals from all of them into one relevance-conditioned score.
---
---
# YantrikDB Python API Reference — record, recall, think, graph
URL: https://yantrikdb.com/reference/python-api/
Complete YantrikDB Python API reference — record, recall, think, graph, conflict detection, personality. Methods for building AI agent memory systems with pip install yantrikdb.
## YantrikDB
The main database class.
### Constructor
```python
db = YantrikDB(
db_path="memory.db",
embedding_dim=384,
embedder=None, # optional: sentence_transformers model
)
```
| Parameter | Type | Default | Description |
|-----------|------|---------|-------------|
| `db_path` | `str` | `"memory.db"` | Path to the database file (`:memory:` for in-memory) |
| `embedding_dim` | `int` | `384` | Embedding vector dimensions |
| `embedder` | `object` | `None` | A `SentenceTransformer` model instance for auto-embedding |
---
## Core Memory
### `record(text, **kwargs) → str`
Store a memory. Returns the record ID.
```python
rid = db.record(
"User likes Python",
importance=0.7, # 0.0-1.0
valence=0.3, # -1.0 to 1.0 (emotional)
memory_type="semantic", # episodic, semantic, procedural
domain="work",
source="user",
certainty=0.8, # 0.0-1.0
namespace="default",
idempotency_key=None, # v0.10: exactly-once writes (see below)
)
```
**Idempotency keys (v0.10).** Pass `idempotency_key` to make the write exactly-once: retrying with the same key and an identical payload returns the *original* rid with **zero writes** — no duplicate row, no importance-stats advance, no certainty change. Repetition is not corroboration. The same key with a *different* payload raises a typed `yantrikdb.IdempotencyConflict` carrying the existing rid. Derive keys from a stable external identity (a message id, `"conv:{id}:turn:{n}"`) — never from the text itself, or every edit becomes a conflict.
Routing: with an explicit `embedding`, the key binds to the exact bytes you sent. With no embedding on an engine-embedder host, the write routes through a drift-safe digest that *excludes* the generated vector — an embedder upgrade between retries can never fake a conflict. A key with a Python-side fallback embedder raises `ValueError` (that deployment can't do keys).
### `record_batch(inputs) → list[str]`
Store multiple memories at once. Each input is a dict with the same fields as `record()`. Batches are **all-or-nothing on failure** (v0.10): a rejected batch writes nothing at all.
```python
rids = db.record_batch([
{"text": "User likes Python", "importance": 0.7},
{"text": "User works at Acme Corp", "importance": 0.9},
])
```
Items may carry an `idempotency_key` (v0.10) — a duplicate item returns the *original* rid at its position; an in-batch repeat of the same key+payload writes once. Keyed batch items require an explicit `embedding` (pass text-only keyed writes through `record()` instead, which routes drift-safe).
### `recall(query, top_k=10, **kwargs) → list[dict]`
Retrieve memories using relevance-conditioned scoring.
```python
results = db.recall(
"What programming languages?",
top_k=5,
memory_type="semantic", # optional filter
namespace="default", # optional filter
include_superseded=False, # v0.10 default: current truth only
)
for r in results:
print(f"[{r['score']:.3f}] {r['text']}")
```
Returns a list of dicts with `text`, `score`, `rid`, `importance`, `valence`, `certainty`, etc.
**Behavioral change in v0.10:** recall **excludes superseded records by default**. If record B supersedes record A (via a `supersedes` link), default recall returns B and hides A; pass `include_superseded=True` for history access. Current-by-default is what an agent should act on — the outcome that matters is *correct, current context after restart and correction*, not raw recall volume. Disputed records are different: an open dispute keeps **both** sides visible, each carrying the other in `disputed_with` — the engine never silently picks a winner.
### `recall_with_response(query, top_k=10) → dict`
Like `recall()` but includes confidence calibration with `certainty_reasons` explaining why confidence is high or low.
```python
resp = db.recall_with_response("What is the user's timezone?", top_k=3)
# resp['results'], resp['certainty'], resp['certainty_reasons']
```
### `recall_refine(original_query, refinement, top_k=5) → list[dict]`
Refine a low-confidence recall with a follow-up query.
### `get(rid) → dict | None`
Retrieve a specific memory by record ID.
### `forget(rid) → bool`
Tombstone a memory by record ID.
### `correct(rid, reason, new_text=None, metadata_merge=None, new_importance=None, new_valence=None) → dict`
Fix an incorrect memory **in place** (v0.9.4+): the rid is stable, the original is *not* tombstoned, and the full revision history is preserved. A text change is **vector-coherent** — the memory is re-embedded so it is retrieved under its *new* meaning, never the old one.
```python
result = db.correct(rid, "user changed employers", new_text="User works at Google, not Meta")
assert result["corrected_rid"] == rid # same record, revised
assert result["original_tombstoned"] is False # in-place, history kept
```
Scalar/metadata-only corrections (importance, valence, `metadata_merge`) skip re-embedding entirely. Note: a `metadata_merge` cannot launder provenance — flipping `kind` to `fact` on an inference-sourced record is refused by the write gate (v0.10) regardless of whether the text changes.
### `list_memories(namespace=None, limit=100, offset=0) → list[dict]`
List all active memories with pagination.
### `decay(threshold=0.01) → list[dict]`
Run decay pass — returns memories that fell below the threshold and were archived.
### `stats(namespace=None) → dict`
Get database statistics: `active_memories`, `edges`, `entities`, `open_conflicts`, etc.
---
## Errors (v0.10)
Actionable engine errors arrive as **typed exception classes**, all subclassing `RuntimeError` (existing `except RuntimeError:` handlers keep working). Branch on type, never on message text:
```python
import yantrikdb
try:
rid = db.record(text, idempotency_key=key)
except yantrikdb.IdempotencyConflict as e:
# Same key, different payload — the first write stands.
# The message carries the existing rid: fetch it and decide.
...
except yantrikdb.Backpressure:
... # engine saturated, nothing written — back off and retry
except yantrikdb.ProvenanceInconsistent:
... # the anti-laundering gate refused the declaration — fix it
```
| Exception | Meaning | Retry? |
|---|---|---|
| `Backpressure` | Engine saturated; nothing written | Yes, with backoff |
| `RecallContended` | Recall lost a bounded read-contention race | Yes — nothing wrong with the query |
| `CorrectionDeferredDuringReembed` | Re-embedding cutover in flight | Yes, after cutover |
| `BatchDeferredDuringReembed` | Whole batch deferred; nothing written | Yes, identical batch |
| `IdempotencyConflict` | Same key, different payload; message carries existing rid | No — change key or payload |
| `InvalidIdempotencyKey` | Key empty/whitespace/>512 bytes | No — fix the key |
| `ProvenanceInconsistent` | Write refused by the anti-laundering gate | No — fix the declaration |
## Knowledge Graph
### `relate(src, dst, rel_type, weight=1.0)`
Create a relationship in the cognitive graph.
```python
db.relate("Alice", "Acme Corp", "works_at", weight=0.9)
db.relate("Alice", "Rust", "prefers", weight=0.8)
```
### `get_edges(entity) → list[dict]`
Get all relationships for an entity.
### `search_entities(query, limit=20) → list[dict]`
Find entities by name pattern.
### `entity_profile(entity, days=90.0, namespace=None) → dict`
Get a comprehensive profile for an entity: relationship count, memory mentions, domain spread, activity timeline.
### `relationship_depth(entity, namespace=None) → dict`
Composite depth score (0.0–1.0) combining sessions together, memories mentioning, domains spanning, connection count, and relationship type diversity.
```python
depth = db.relationship_depth("Alice")
# depth['depth_score'], depth['sessions_together'], depth['domains_spanning'], ...
```
---
## Cognition
### `think(**kwargs) → dict`
Run autonomous cognition: consolidation, conflict detection, pattern mining, substitution category scanning, gossip triggers.
```python
result = db.think(
importance_threshold=0.5,
run_consolidation=True,
run_conflict_scan=True,
run_pattern_mining=True,
)
# result['triggers'], result['consolidation_count'],
# result['conflicts_found'], result['patterns_new']
```
### `get_conflicts(status=None, conflict_type=None, entity=None, priority=None, limit=50) → list[dict]`
List detected contradictions with optional filters.
```python
conflicts = db.get_conflicts(status="open")
for c in conflicts:
print(f"{c['conflict_type']}: {c['detection_reason']}")
```
### `resolve_conflict(conflict_id, resolution, note=None)`
Resolve a contradiction: `keep_a`, `keep_b`, `merge`, `keep_both`.
### `dismiss_conflict(conflict_id, note=None)`
Dismiss a conflict without resolving it.
### `scan_conflicts() → list[dict]`
Manually trigger conflict scanning (also runs inside `think()`).
### `get_patterns(limit=20) → list[dict]`
List all discovered behavioral patterns.
### `get_personality() → dict`
Get the AI's derived personality traits based on memory patterns.
### `derive_personality() → dict`
Recalculate personality traits from current memory state.
---
## Substitution Categories (V14)
YantrikDB maintains vocabularies of interchangeable terms (e.g., PostgreSQL/MySQL are both "databases"). When two memories differ only by a substitution, it's flagged as a conflict rather than redundancy.
### `substitution_categories() → list[dict]`
List all substitution categories with member counts.
```python
cats = db.substitution_categories()
# [{"name": "databases", "conflict_mode": "exclusive", "member_count": 15}, ...]
```
### `substitution_members(category_name) → list[dict]`
List members of a specific category.
```python
members = db.substitution_members("databases")
# [{"token_normalized": "postgresql", "confidence": 0.95, "source": "seed"}, ...]
```
### `learn_category_members(category_name, members, source="llm_suggested") → int`
Add new members to a category. Returns count of new members added.
```python
count = db.learn_category_members(
"databases",
[("tidb", 0.35), ("surrealdb", 0.35)],
"llm_suggested"
)
```
| Source | Confidence | Drives conflicts? |
|--------|-----------|-------------------|
| `seed` | 0.95 | Yes (≥ 0.6 threshold) |
| `user_confirmed` | 1.0 | Yes |
| `llm_suggested` | 0.35 | No (below threshold) |
### `reclassify_conflict(conflict_id, new_type) → dict`
Reclassify a conflict and teach the system. Extracts differing tokens and learns new category members from the correction.
```python
result = db.reclassify_conflict(conflict_id, "preference")
# result['learned_members'] — tokens added to categories from this feedback
```
### `reset_category_to_seed(category_name) → int`
Remove all learned members from a category, keeping only seed vocabulary. Returns count of members removed.
```python
removed = db.reset_category_to_seed("editors_tools")
```
---
## Sessions
### `session_start(namespace="default", client_id="default", metadata=None) → str`
Start a new conversation session. Returns session ID.
### `session_end(session_id, summary=None) → dict`
End a session with optional summary.
### `active_session(namespace="default", client_id="default") → dict | None`
Get the currently active session.
### `session_history(namespace="default", client_id="default", limit=10) → list[dict]`
Get recent session history.
### `session_abandon_stale(max_age_hours=24.0) → int`
Clean up sessions that were never properly ended.
---
## Temporal
### `stale(days=30.0, limit=50, namespace=None) → list[dict]`
Find memories that haven't been accessed in a while and may need verification.
### `upcoming(days=7.0, limit=50, namespace=None) → list[dict]`
Find memories with upcoming temporal relevance (deadlines, events).
---
## Procedural Memory
Self-improving memory for strategies and behaviors. Tracks what works and adapts over time.
### `record_procedural(text, domain="general", task_context="", effectiveness=0.5, namespace="default") → str`
Record a procedural memory (a strategy or approach that worked/didn't work).
```python
rid = db.record_procedural(
"When user asks about code, show examples before explanation",
domain="communication",
effectiveness=0.8,
)
```
### `surface_procedural(query_embedding, query_text=None, domain=None, top_k=5, namespace=None) → list[dict]`
Retrieve relevant procedural memories for a task context.
### `reinforce_procedural(rid, outcome) → bool`
Update a procedural memory's effectiveness score based on outcome (EMA-based adaptation).
```python
db.reinforce_procedural(rid, outcome=0.9) # worked well
db.reinforce_procedural(rid, outcome=0.2) # didn't work this time
```
### `procedural_stats(namespace=None) → list[dict]`
Get procedural memory statistics by domain: count and average effectiveness.
---
## Triggers & Lifecycle
### `get_pending_triggers(limit=10) → list[dict]`
Get undelivered proactive triggers.
### `deliver_trigger(trigger_id) → bool`
Mark a trigger as delivered to the agent.
### `acknowledge_trigger(trigger_id) → bool`
Mark a trigger as acknowledged by the agent.
### `act_on_trigger(trigger_id) → bool`
Mark a trigger as acted upon.
### `dismiss_trigger(trigger_id) → bool`
Dismiss a trigger without acting on it.
### `get_trigger_history(limit=20, trigger_type=None) → list[dict]`
Get trigger history with optional type filter.
---
## Recall Feedback
### `recall_feedback(query, chosen_rid, rejected_rids=None) → bool`
Teach the scoring engine which results were useful. Improves retrieval quality over time.
```python
db.recall_feedback(
query="What's the user's timezone?",
chosen_rid="019d...",
rejected_rids=["019e...", "019f..."],
)
```
### `learned_weights() → dict`
Inspect the current learned scoring weights.
---
## Embedding
### `set_embedder(fn_or_model)`
Set the embedding function or model.
```python
from sentence_transformers import SentenceTransformer
model = SentenceTransformer("all-MiniLM-L6-v2")
# Pass model directly (recommended)
db = YantrikDB("memory.db", embedding_dim=384, embedder=model)
# Or set after construction
db.set_embedder(lambda text: model.encode(text).tolist())
```
### `embed(text) → list[float]`
Generate an embedding for text using the configured embedder.
---
## Sync & Replication
### `extract_ops_since(hlc=None, limit=1000) → list[dict]`
Extract oplog entries since a given HLC for CRDT sync.
### `apply_ops(ops) → dict`
Apply remote operations (merge with conflict resolution).
### `archive(rid) → bool`
Move a memory to cold storage.
### `hydrate(rid) → bool`
Restore a memory from cold storage.
---
# YantrikDB Rust API Reference — Embeddable Cognitive Memory
URL: https://yantrikdb.com/reference/rust-api/
Complete YantrikDB Rust API reference — high-performance cognitive memory engine with embedded HNSW vector search, knowledge graph, contradiction detection. cargo add yantrikdb. Pure Rust, no FFI.
Full API documentation is available on [docs.rs/yantrikdb](https://docs.rs/yantrikdb).
## Quick Reference
```rust
use yantrikdb::{YantrikDB, Embedder, RecallQuery};
// Open database
let mut db = YantrikDB::open("memory.db", 384)?;
// Set embedder
db.set_embedder(Box::new(MyEmbedder));
// Record
let emb = db.embed("User likes Rust")?;
db.record_with_embedding("User likes Rust", &emb, "semantic", 0.8, 0.5)?;
// Recall with builder pattern
let query_emb = db.embed("programming languages")?;
let results = db.recall_query(
RecallQuery::new(query_emb)
.top_k(5)
.memory_type("semantic")
.namespace("default")
)?;
// Graph operations
db.relate("user", "Rust", "prefers", 0.9)?;
let edges = db.edges(Some("user"))?;
// Autonomous cognition
let think_result = db.think(&Default::default())?;
```
## Embedder Trait
Implement this trait to plug in any embedding model:
```rust
pub trait Embedder: Send + Sync {
fn embed(&self, text: &str) -> Result, Box>;
fn embed_batch(&self, texts: &[&str]) -> Result>, Box> {
texts.iter().map(|t| self.embed(t)).collect()
}
fn dim(&self) -> usize;
}
```
## Key Types
| Type | Description |
|------|-------------|
| `YantrikDB` | Main database engine |
| `Memory` | A stored memory record |
| `RecallResult` | A recall result with scoring |
| `RecallQuery` | Builder for composable queries |
| `Edge` | A graph edge |
| `Trigger` | A proactive trigger |
| `ThinkConfig` | Configuration for the cognition loop |
| `ThinkResult` | Result of a think() pass |
| `Pattern` | A discovered behavioral pattern |
| `Conflict` | A detected contradiction |
---
# Benchmarks
URL: https://yantrikdb.com/research/benchmarks/
Measured results, with the conditions each number was measured under.
Every number here names the conditions it was measured under. Where a result is a tie, it is reported as a tie.
## Benchmark: Token Savings vs File-Based Memory
Benchmarked with 15 diverse queries across 4 scales. File-based memory (CLAUDE.md, memory files) loads *everything* into context every conversation. YantrikDB's selective recall retrieves only the 3–5 memories relevant to the current task.
| Memories | **File-Based** | **YantrikDB** | **Savings** | **Precision** |
|---|---|---|---|---|
| 100 | 1,770 tokens | 69 tokens | **96%** | 66% |
| 500 | 9,807 tokens | 72 tokens | **99.3%** | 77% |
| 1,000 | 19,988 tokens | 72 tokens | **99.6%** | 84% |
| 5,000 | 101,739 tokens | 53 tokens | **99.9%** | 88% |
**Selective recall cost is O(1). File-based memory cost is O(n).**
At 1,000 memories, file-based memory is about 20K tokens; at 5,000 it is about 102K, exceeding 32K and 100K context windows. YantrikDB stays at ~70 tokens per query with recall latency under 60ms. Precision *improves* with more data: the opposite of file-based memory, which degrades as context fills up.
Works with **Claude Code, Codex, Cursor, Windsurf, Copilot, Kilo Code** — any MCP-compatible agent. Run the benchmark yourself: `python benchmarks/bench_token_savings.py`
---
---
# Why We Deleted Our AI Memory Conflict Detector
URL: https://yantrikdb.com/research/contradiction-detector-rewrite/
YantrikDB's first contradiction detector confused similarity with disagreement. Here is the failed benchmark, the 0/16 production audit, and the structured claim model that replaced it.
An embedding can tell you that two memories discuss similar things. It cannot
tell you that they cannot both be true.
YantrikDB once blurred that distinction. We shipped a conflict detector that
used similarity, shared entities, and changed words as evidence of possible
contradiction. It looked plausible in demos. Real data showed that the model
was wrong.
We deleted it.
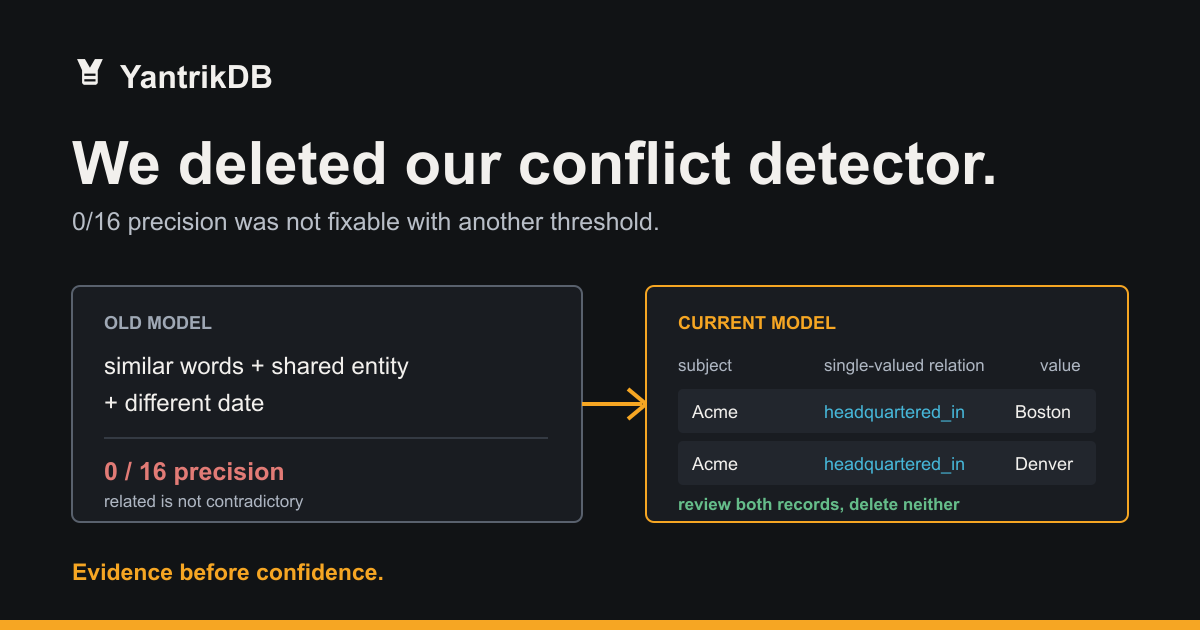
This is the failure report, the replacement, and the boundary we still do not
claim to solve.
## The benchmark that broke the story
In April 2026, a Hacker News discussion pushed us to test the detector on a
small running store instead of describing what the architecture was supposed
to do.
The corpus contained 59 memories: repeated facts, distractors, and six seeded
conflicts. Consolidation removed duplicate recall results and improved the
top-result rate from 75% to 87.5%. Conflict detection found **0 of 6** seeded
conflicts.
The reason was architectural. The detector ran over structured graph edges,
while the normal memory write path stored text without creating those edges.
The feature existed, but the default path did not feed it.
An early attempt to close that gap overcorrected. Similarity and shared-entity
heuristics produced large review queues full of pairs that were related but
not contradictory.
That result and the criticism are still public in the
[original Hacker News thread](https://news.ycombinator.com/item?id=47767119).
## The production audit was worse
Four months later, we hand-labeled 16 open conflict flags from the production
store. The old lexical path measured **0/16 precision** on that set.
The failures fell into repeatable classes:
| False-positive class | What the old detector did |
|---|---|
| Shared person, different dates | Paired unrelated project notes because both named the same person |
| Multi-valued relations | Treated "created project A" and "created project B" as mutually exclusive |
| Phantom subjects | Let headings and bare numbers anchor claims |
| Self-conflicts | Flagged two values extracted from one progression record against itself |
No threshold fixes these categories. A word-set difference is not a
contradiction test, even when the two sentences are close in embedding space.
## The replacement: conflict as a data constraint
The current detector keys on structured claims:
```text
(subject, relation) -> value
```
For example:
```text
(Acme, headquartered_in) -> Boston
(Acme, headquartered_in) -> Denver
```
A pair becomes eligible for review only after passing structural gates.
1. **The relation must be single-valued.** Distinct values for `created`,
`likes`, or other multi-valued relations are just distinct facts.
2. **The subject must be admissible.** Extraction debris cannot anchor a
conflict. Deliberate relations created through the API remain eligible.
3. **The records must be distinct and active.** One record cannot conflict
with itself, and superseded history is not a live dispute.
4. **The values must differ after alias resolution.** Two names for the same
entity do not create a conflict.
5. **Time changes the classification.** Overlapping validity windows can be a
simultaneous conflict. Ordered windows are a succession candidate.
The scanner records a review item. It does not delete either memory or decide
which value is true.
## Why time is part of the claim
These statements can both be correct:
```text
CT128 runs engine 0.14.1 [valid from day 1]
CT128 runs engine 0.15.0 [valid from day 30]
```
The current detector carries `valid_from` and `valid_to` qualifiers. Ordered
open-ended starts are reported as possible succession with a
newer-supersedes hint. Closed windows that actually overlap stay high-priority.
An explicit supersession link resolves the pair and suppresses future flags.
Creation time is only a fallback hint when world-validity time is absent. The
database does not pretend those timestamps mean the same thing.
## The regression gate
The rewrite reconstructs the production failures as tests, alongside the
positive path:
- unrelated dated memories sharing an entity do not conflict;
- multi-valued relations do not conflict pairwise;
- phantom subjects cannot anchor a conflict;
- one record cannot conflict with itself;
- a functional relation with two active values creates one review item;
- an explicit supersession link suppresses that item.
The six gates pass on YantrikDB 0.18.0. Read the
[detector and regression set](https://github.com/yantrikos/yantrikdb/blob/a5fdf79/crates/yantrikdb-core/src/distributed/conflict.rs#L1165),
or run the focused tests:
```bash
cargo test -p yantrikdb class_
cargo test -p yantrikdb true_positive_
```
You can also exercise the actual Rust engine in the
[browser Memory Lab](https://yantrikdb.com/#memory-lab). It runs through
WebAssembly with no server or API call.
## The boundary we still keep
This is conservative typed detection, not general natural-language inference.
"Alice is CEO" and "Bob is CEO" may describe a replacement, co-CEOs, two
organizations, or an extraction mistake. The database cannot recover missing
context from two loose sentences. A correct result depends on claim scope,
relation cardinality, validity time, and evidence quality.
YantrikDB can make known constraints inspectable and deterministic. It cannot
turn underspecified prose into certainty, and our public claims now say so.
That narrower promise is more useful than a broad detector nobody can trust.
---
# YantrikDB Cluster Setup — YRP Native Replication, Witness HA, Failover
URL: https://yantrikdb.com/server/cluster/
Deploy a high-availability YantrikDB cluster with YRP (RFC 028) native replication — leader election, quorum-durable writes, exactly-once keyed writes, linearizable reads, and witness-based quorum for 2-node setups.
YantrikDB Server clusters on **YRP — the YantrikDB Replication Protocol** (RFC 028, `raft_mode = "yrp"`). YRP is a Raft-shaped safety core — leader election, log replication, snapshots, all model-checked in a deterministic simulator — plus purpose-built recovery for a memory database:
- **Quorum-durable writes** — a write is acknowledged only once a quorum of data nodes has durably accepted it, and applied it to engine state (semantic index included) on every replica.
- **Exactly-once keyed writes** — `idempotency_key` is checked at the leader's ingress, carried inside the replicated log entry, and answered from a durable outcome record. A retry during *any* replication state (failover, partition, rejoin) dedupes to the original result — never a double write.
- **Linearizable reads** — a read barrier commits a no-op through the replicated log, so a read served after it reflects every write committed before it, and a deposed-but-unaware leader cannot serve stale data.
- **Quarantine, not wedge** — a node that boots with torn or alien replication state starts *non-voting* and serves diagnostics, then rejoins via a quorum-authorized snapshot. It never split-brains and never crash-loops (the failure mode that took an earlier deployment down for 10 days).
- **Engine backfill** — a straggler that falls behind the log-compaction horizon heals its full engine state (memories, embeddings, entities) from the leader, not just protocol metadata.
- **Witness quorum** — a tiny vote-only member gives safe HA with just 2 data nodes.
- **Chaos-gated releases** — kill-leader-under-load, partition-and-heal, torn-state rejoin, and beyond-GC recovery run on every commit and block any release that regresses cluster safety.
The cluster path is exercised with leader-kill, partition-and-heal, torn-state,
and recovery scenarios. Failover time depends on the configured election ticks,
topology, and environment; the current public evidence establishes recovery, not
a universal latency guarantee.
## Topology
Minimum safe HA is **2 data voters + 1 witness**; **3 data voters + 1 witness** tolerates the loss of a data node while still accepting writes.
```
┌──────────────────┐ YRP over HTTP ┌──────────────────┐
│ data node 1 │ ◄───────────────▶ │ data node 2 │
│ (voter) │ /v1/yrp/msg │ (voter) │
│ full storage │ │ full storage │
└────────┬─────────┘ └────────┬─────────┘
│ │
│ ┌──────────────────┐ │
└───────▶│ witness │◄─────────┘
│ (vote-only) │
└──────────────────┘
```
The witness votes in elections but never stores data and never counts toward a write's durability — so a witness-assisted election can only ever elect a data node that already holds every committed write. It breaks ties so 2 data nodes run safe HA without a 3rd full node, the same pattern as **Azure SQL** (witness), **MongoDB** (arbiter), and **Redis Sentinel**.
## Configuration
### Generate configs with `cluster init`
`yantrikdb cluster init` writes a complete YRP config. Run it **once per node** with the **same** member list — change only `--node-id`. Members are `node_id@http_url` (YRP node ids are stable identities); YRP wire traffic rides the HTTP plane (`POST /v1/yrp/msg`, authenticated by the shared `cluster_secret`).
On **node 1**:
```bash
yantrikdb cluster init \
--node-id 1 \
--cluster-id 28 \
--data-dir /var/lib/yantrikdb \
--peer 1@http://10.0.0.1:7438 \
--peer 2@http://10.0.0.2:7438 \
--peer 3@http://10.0.0.3:7438 \
--witness 4@http://10.0.0.4:7438 \
--output /etc/yantrikdb.toml
```
It prints a fresh `cluster_secret` — **save it**; you'll pass it to every other node as `--secret` and use it as the master Bearer token from clients.
On nodes 2, 3, and the witness (4), re-run with the same flags, changing only `--node-id` and adding `--secret `. A node whose `--node-id` matches a `--witness` entry is configured as a witness automatically.
The generated `/etc/yantrikdb.toml` looks like:
```toml
[server]
wire_port = 7437
http_port = 7438
data_dir = "/var/lib/yantrikdb"
[cluster]
node_id = 1
role = "voter" # "witness" on the witness member
raft_mode = "yrp"
cluster_secret = "ydb_cluster_...same-on-every-node..."
[yrp]
cluster_id = 28 # immutable cluster identity; identical on every member
tick_ms = 50 # driver tick; all timing is counted in ticks
election_ticks_min = 10 # randomized election timeout range
election_ticks_max = 20
heartbeat_ticks = 2 # leader heartbeat cadence
[[yrp.peers]]
node_id = 1
addr = "http://10.0.0.1:7438"
# ... peers 2 and 3 ...
[[yrp.peers]]
node_id = 4
addr = "http://10.0.0.4:7438"
witness = true # votes only; never stores data (at most one per cluster)
```
The witness runs the **same `yantrikdb` binary** as the voters — in YRP mode a witness is a full peer with `witness = true`, not a separate daemon.
### Start each node
```bash
yantrikdb serve --config /etc/yantrikdb.toml
```
After a few seconds an election runs and one voter becomes leader. Check any node:
```bash
curl -s http://10.0.0.1:7438/v1/health | jq .cluster
```
```json
{
"node_id": 1,
"role_label": "leader",
"term": 1,
"leader": 1,
"accepts_writes": true,
"last_applied_index": 42,
"replication_lag_log_entries": 0,
"raft_mode": "yrp"
}
```
## Reads and writes
Point writes at the leader. A follower refuses a write with `503` and the leader's address, so clients redirect:
```json
{ "error": "read-only: not the leader (current leader: node 3)",
"leader_node_id": 3, "leader_addr": "http://10.0.0.3:7438", "raft_mode": "yrp" }
```
Keyed writes carry the same contract on the cluster as single-node: a fresh `idempotency_key` returns `{rid}`; the same key + same text returns the **original** `{rid}` with zero new writes; the same key + different text returns `{stored: false, idempotency_conflict: true, rid}`. Reads (`/v1/recall`, `/v1/memory/{rid}`) served from any node reflect committed writes; a node still catching up after a rejoin reports `engine_backfilling` on `/v1/health` and is not counted read- or leadership-eligible until it is caught up.
## Failover
Kill the leader (`systemctl stop yantrikdb`). Within a few seconds:
1. A surviving voter misses heartbeats and campaigns.
2. The witness (and any other data node) grant votes.
3. The new leader resumes accepting writes; a keyed write that was in flight resolves exactly-once on retry.
The old leader, on restart, sees the higher term, adopts canonical history (truncating any tentative tail), and rejoins as a follower.
| Failure | Behavior |
|---------|----------|
| Leader data node dies | Surviving voter + witness elect a new leader; writes resume after election |
| Follower data node dies (3-voter) | Leader keeps writing (still has a data quorum) |
| Witness dies | Voters keep serving; no new election can complete until it returns |
| Torn / alien state on boot | Node quarantines (non-voting), serves diagnostics, rejoins via authorized snapshot |
| Straggler past the GC horizon | Rejoins via snapshot + engine backfill; recall reflects the recovered range |
| Network partition isolates the leader | Isolated leader cannot commit (no quorum), goes read-only; majority elects |
## Cluster authentication
The `cluster_secret` authenticates **peer-to-peer** traffic (it's the bearer YRP nodes present to each other on `/v1/yrp/msg`). It is **not** a client data-plane token.
Client tokens are created per node with `yantrikdb token create` — in YRP mode the control plane (databases + tokens) is local to each node and not replicated, so create a token on each node you'll direct clients at:
```bash
yantrikdb token --data-dir /var/lib/yantrikdb create --db default --label app
```
Point writes at the current leader with a token valid on that node; a follower answers `503` with the leader's address so clients redirect. (Replicated control-plane / master-token auth is a tracked follow-up; per-node tokens are the model today.)
---
> **Upgrading from the openraft cluster path?** The `openraft` engine was removed in v0.12.0 — YRP replaces it. A config with `raft_mode = "openraft"` is refused at startup with a migration hint. Switch to `raft_mode = "yrp"` with a `[yrp]` section as above, or `raft_mode = "disabled"` for single-node. Standalone deployments are unaffected.
---
# YantrikDB At-Rest Encryption — AES-256-GCM
URL: https://yantrikdb.com/server/encryption/
Encrypt YantrikDB cognitive memory data on disk with AES-256-GCM. Per-tenant master keys, transparent encryption for SQLite + HNSW index, key rotation without downtime. Production-ready for sensitive AI agent memories.
YantrikDB Server can encrypt all memory data at rest using AES-256-GCM. This includes the memory text, embeddings, metadata, and graph edges — everything sensitive in the SQLite database file.
## Why this matters
Cognitive memory is intimate data. A YantrikDB instance stores:
- Personal facts and preferences
- Relationships and emotional context
- Decisions and reasoning traces
- Conversation history
If someone gets the disk image (theft, backup leak, snapshot exfiltration), they shouldn't be able to read any of it. At-rest encryption is the bottom layer of trust.
## Enabling encryption
Encryption is **opt-in**. Add an `[encryption]` section to your config:
### Option A: Auto-generated key
```toml
[encryption]
auto_generate = true
```
On first startup, the server creates `master.key` (32 random bytes) in the data directory with `0600` permissions. Keep this file safe — losing it = losing all data.
### Option B: Explicit key file
```toml
[encryption]
key_path = "/etc/yantrikdb/master.key"
auto_generate = false
```
Generate the key first:
```bash
yantrikdb encryption gen-key --output /etc/yantrikdb/master.key
```
### Option C: Hex string (env-friendly)
```toml
[encryption]
key_hex = "your-64-char-hex-string"
```
Or set via environment variable for secrets management:
```bash
export YANTRIKDB_ENCRYPTION_KEY_HEX=$(cat /run/secrets/yantrikdb-key)
yantrikdb serve --config yantrikdb.toml
```
## Verification
When encryption is enabled, you'll see this on startup:
```
INFO yantrikdb: encryption: enabled (AES-256-GCM)
```
Versus disabled:
```
WARN yantrikdb: encryption: disabled — set [encryption] to enable at-rest encryption
```
You can verify the on-disk file is unreadable:
```bash
strings /var/lib/yantrikdb/default/yantrik.db | grep "your sensitive text"
# (no output — text is encrypted)
```
## Cluster encryption
In a cluster, **all nodes must use the same master key**. The replicated oplog payloads are plaintext on the wire (under TLS), but each node encrypts independently to its own SQLite file. Sharing the key ensures any node can serve queries after failover.
Recommended setup:
1. Generate the key once on node1: `yantrikdb encryption gen-key`
2. Securely copy to node2 and node3 (e.g. via SSH, KMS, or secrets manager)
3. Configure each node to read it via `key_path`
## What is and isn't encrypted
| Component | Encryption |
|-----------|-----------|
| Memory text | ✅ AES-256-GCM |
| Embeddings | ✅ AES-256-GCM |
| Metadata JSON | ✅ AES-256-GCM |
| Graph edges | ✅ AES-256-GCM |
| Oplog entries | ✅ AES-256-GCM |
| `control.db` (databases + tokens) | ❌ Plaintext (no sensitive data) |
| Wire protocol | TLS only (Phase 2) |
| HTTP gateway | TLS only |
## Caveats
- **Encryption + replication backfill**: follower nodes that receive replicated memories cannot backfill embeddings on encrypted databases — the engine method needed to write encrypted embeddings (`encrypt_embedding`) is still `pub(crate)` and not exposed in the public core crate. For encrypted clusters today, recall on followers will return empty until the data is re-encrypted manually. Workaround: don't enable encryption + replication together. Tracked for an upcoming release.
- **Key rotation** is not yet supported. Plan ahead and back up your key immediately.
- **Backup files** are also encrypted when you `yantrikdb export` a database with encryption enabled.
## Operational best practices
1. **Back up the key separately from the data.** A backup with both is no better than no encryption.
2. **Use a hardware-backed key store** if you have one (HSM, KMS, vault).
3. **Set restrictive file permissions** on the key file (`chmod 600`).
4. **Monitor for key file changes** with auditd or similar.
5. **Document the key escrow process** so you can recover from staff turnover.
---
# YantrikDB HTTP API Reference — REST Endpoints for AI Memory
URL: https://yantrikdb.com/server/http-api/
Complete REST endpoint reference for the YantrikDB Server HTTP gateway — remember, recall, forget, relate, skill substrate, cluster status, admin. JSON over HTTP, Bearer-token auth, MCP-compatible.
YantrikDB Server exposes a JSON HTTP gateway on port `7438` (configurable). Every endpoint accepts a Bearer token in the `Authorization` header.
## Authentication
Two ways to authenticate:
1. **Per-database token** — generated with `yantrikdb token create --db `. Each token grants access to one database.
2. **Cluster master token** — when clustering is enabled, the `cluster_secret` doubles as a master token that works on any node and grants access to the default database.
```bash
curl -H "Authorization: Bearer ydb_xxxxxxxx..." http://localhost:7438/v1/stats
```
## Endpoints
### Memory operations
| Method | Path | Description |
|--------|------|-------------|
| POST | `/v1/remember` | Store a memory |
| POST | `/v1/remember/batch` | Store up to 10k memories in one call |
| POST | `/v1/recall` | Semantic search (response includes `fallback: "fts5_keyword"` when the engine fell back to BM25 keyword matching; `null` otherwise — v0.8.17+) |
| POST | `/v1/forget` | Tombstone a memory |
| POST | `/v1/relate` | Create knowledge graph edge |
### Memory inspection (v0.8.17+, dashboard-facing)
Issue [#39 Phase 1](https://github.com/yantrikos/yantrikdb-server/issues/39) ships three read endpoints that back [wysie's `yantrikdb-hermes-dashboard`](/guides/hermes-dashboard/). They use the RFC 014-B Principal substrate — query params can narrow the token's authorized namespace but never broaden it.
| Method | Path | Description |
|--------|------|-------------|
| GET | `/v1/identity-scope` | What this token sees — `principal`, `effective_scope`, `namespace_inventory`, and a nested `identity_scope` summary (identities / actors / spaces / conversations). Requires `Scope::Read`. |
| GET | `/v1/memories` | Paged, filtered list of active memories. Query params: `namespace`, `status`, `domain`, `memory_type`, `limit` (default 50, max 200), `offset`, `sort` (`created_at` / `importance` / `last_access`). Response: `{total, limit, offset, items[]}` with each row in the 25-field dashboard shape. |
| GET | `/v1/memory/{rid}` | Point read for a single memory, with `consolidation_sources`/`entities`/`claims` conditional arrays. Supports `?min_seq=N` for read-your-writes — returns 412 `replica_behind` if the local node hasn't applied the requested seq. |
### Structured error envelope (v0.8.17+)
Every `/v1/*` error response is shaped:
```json
{ "error": { "code": "stable_id", "message": "human-readable", "hint": "optional" } }
```
Branch on `code`, not on the prose `message`. The stable code registry lives at [`docs/error-codes.md`](https://github.com/yantrikos/yantrikdb-server/blob/main/docs/error-codes.md) (`unauthenticated`, `insufficient_scope`, `namespace_not_found`, `memory_not_found`, `invalid_query_parameter`, `replica_behind`, and more). Legacy call sites that haven't migrated to a specific code emit `"code": "generic"` via a shim — these are tracked and will migrate over time.
### Skill substrate (v0.8.11+)
First-class skill primitives — schema-validated, RYW-consistent, namespace-scoped to `skill_substrate`. Strict shape validation catches drift bugs (hyphen-vs-underscore in `applies_to` entries, malformed `skill_id`) without enforcing semantic ontology — the engine validates shape, the agent layer decides meaning.
| Method | Path | Description |
|--------|------|-------------|
| POST | `/v1/skills/define` | Register a skill (`skill_id`, `body`, `applies_to`, `skill_type`). Returns 409 on duplicate. |
| GET | `/v1/skills/{skill_id}` | Exact lookup by skill_id. |
| POST | `/v1/skills/search` | Semantic search across skills with optional `applies_to` / `skill_type` post-filter. |
| POST | `/v1/skills/{skill_id}/outcome` | Append-only outcome event log. Engine never auto-rolls-up `success_count` — agent-layer pedagogy. |
| POST | `/v1/skills/{skill_id}/forget` | Tombstone a skill (optionally cascade outcomes). |
### Cluster & health
| Method | Path | Description |
|--------|------|-------------|
| GET | `/v1/health` | Shallow health + cluster state (cluster mode adds `last_log_index`, `last_applied_index`, `replication_lag_log_entries`, `role_label` per RFC 010 PR-6.9) |
| GET | `/v1/health/deep` | Deep health — probes engine lock, control DB, cluster quorum. Returns 503 if degraded. |
| GET | `/v1/cluster` | Cluster state: role, term, leader, peers |
| POST | `/v1/cluster/promote` | Force election from this node |
| GET | `/v1/stats` | Database statistics |
| GET | `/metrics` | Prometheus metrics (handler latency, lock waits, request counts) |
### Admin (cluster master token required)
| Method | Path | Description |
|--------|------|-------------|
| POST | `/v1/databases` | Create a new tenant database |
| GET | `/v1/databases` | List all databases |
| GET | `/v1/admin/control-snapshot` | Export databases + tokens for replication |
| POST | `/v1/admin/snapshot` | Online backup of a tenant database (BLAKE3 checksum) |
#### POST /v1/remember
```bash
curl -X POST http://localhost:7438/v1/remember \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{
"text": "Alice leads engineering at Acme",
"importance": 0.9,
"domain": "work",
"memory_type": "semantic",
"valence": 0.0,
"half_life": 168.0
}'
```
Response: `{"rid": "019d623a-..."}`
Optional fields: `metadata` (object), `namespace`, `certainty`, `source`, `emotional_state`, `embedding` (pre-computed vector for client_only mode).
#### POST /v1/remember/batch
Store up to 10,000 memories in a single call. Subject to per-tenant `max_batch_size` quota.
```bash
curl -X POST http://localhost:7438/v1/remember/batch \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{
"memories": [
{"text": "Alice leads engineering", "importance": 0.9, "domain": "work"},
{"text": "Bob runs the ML team", "importance": 0.8, "domain": "work"}
]
}'
```
Response: `{"rids": ["019d623a-...", "019d623b-..."], "count": 2}`
#### GET /v1/health/deep
Active liveness check that probes 3 subsystems. Returns 200 if all pass, 503 if any fail. Use for K8s readiness probes or smart load balancers.
```bash
curl http://localhost:7438/v1/health/deep
```
Response:
```json
{
"status": "healthy",
"checks": [
{"check": "engine_lock", "pass": true, "latency_ms": 0.25},
{"check": "control_db", "pass": true, "latency_ms": 0.11, "databases": 3},
{"check": "cluster_quorum", "pass": true, "node_id": 1, "role": "Leader", "term": 23}
]
}
```
#### POST /v1/admin/snapshot
Create an online backup of a tenant database. Requires cluster master token. WAL-checkpoints before copy for consistency. Returns path + BLAKE3 checksum.
```bash
curl -X POST http://localhost:7438/v1/admin/snapshot \
-H "Authorization: Bearer $CLUSTER_SECRET" \
-H "Content-Type: application/json" \
-d '{"database": "default"}'
```
Response: `{"database": "default", "path": "/data/snapshots/default-1712345678.db", "size_bytes": 4096, "checksum_blake3": "abc123..."}`
#### POST /v1/recall
```bash
curl -X POST http://localhost:7438/v1/recall \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{
"query": "who leads engineering?",
"top_k": 5,
"domain": "work",
"expand_entities": true
}'
```
Response:
```json
{
"results": [
{
"rid": "019d623a-...",
"text": "Alice leads engineering at Acme",
"score": 1.41,
"memory_type": "semantic",
"domain": "work",
"importance": 0.9,
"why_retrieved": ["semantically similar (0.54)", "important", "recent"]
}
],
"total": 1
}
```
#### POST /v1/forget
```bash
curl -X POST http://localhost:7438/v1/forget \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"rid": "019d623a-..."}'
```
Response: `{"rid": "...", "found": true}`
#### POST /v1/relate
```bash
curl -X POST http://localhost:7438/v1/relate \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{
"entity": "Alice",
"target": "Acme",
"relationship": "works_at",
"weight": 1.0
}'
```
Response: `{"edge_id": "019d623a-..."}`
### Sessions
| Method | Path | Description |
|--------|------|-------------|
| POST | `/v1/sessions` | Start a cognitive session |
| DELETE | `/v1/sessions/{id}` | End a session |
```bash
curl -X POST http://localhost:7438/v1/sessions \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"namespace": "chat-1", "client_id": "user-42"}'
```
### Cognition
| Method | Path | Description |
|--------|------|-------------|
| POST | `/v1/think` | Run consolidation + conflict scan |
| GET | `/v1/conflicts` | List open conflicts |
| POST | `/v1/conflicts/{id}/resolve` | Resolve a conflict |
| GET | `/v1/personality` | Get derived personality traits |
### Info
| Method | Path | Description |
|--------|------|-------------|
| GET | `/v1/health` | Server health + cluster status (no auth required) |
| GET | `/v1/stats` | Engine statistics for the authenticated database |
| GET | `/metrics` | Prometheus-format metrics (no auth) |
#### GET /v1/health
```json
{
"status": "ok",
"engines_loaded": 1,
"cluster": {
"node_id": 1,
"role": "Leader",
"term": 5,
"leader": 1,
"accepts_writes": true,
"healthy": true
}
}
```
#### GET /metrics
Prometheus exposition format. Drops in to your existing scraping setup:
```
# HELP yantrikdb_active_memories Number of active memories
# TYPE yantrikdb_active_memories gauge
yantrikdb_active_memories{db="default"} 1247
# HELP yantrikdb_cluster_is_leader Whether this node is currently the leader
# TYPE yantrikdb_cluster_is_leader gauge
yantrikdb_cluster_is_leader{node_id="1"} 1
```
### Database management
| Method | Path | Description |
|--------|------|-------------|
| GET | `/v1/databases` | List databases |
| POST | `/v1/databases` | Create a database |
### Cluster
| Method | Path | Description |
|--------|------|-------------|
| GET | `/v1/cluster` | Detailed cluster status |
| POST | `/v1/cluster/promote` | Manually promote this node to leader (force election) |
#### GET /v1/cluster
```json
{
"clustered": true,
"node_id": 1,
"role": "Leader",
"current_term": 5,
"leader_id": 1,
"healthy": true,
"accepts_writes": true,
"quorum_size": 2,
"peers": [
{
"node_id": 2,
"addr": "192.168.1.2:7440",
"role": "voter",
"reachable": true,
"current_term": 5,
"last_seen_secs_ago": 0.5
},
{
"node_id": 99,
"addr": "192.168.1.3:7440",
"role": "witness",
"reachable": true,
"current_term": 5,
"last_seen_secs_ago": 0.6
}
]
}
```
## Error responses
All errors return JSON with HTTP status:
```json
{
"error": "read-only: not the leader (current leader: node 2)",
"leader": 2
}
```
| Status | Meaning |
|--------|---------|
| 200 | Success |
| 400 | Invalid request body |
| 401 | Missing or invalid Bearer token |
| 404 | Database or memory not found |
| 503 | This node is read-only (not the leader) — try the leader |
| 500 | Internal server error |
---
# Install YantrikDB Server (Linux, macOS, Windows)
URL: https://yantrikdb.com/server/install/
Install YantrikDB Server in Rust, Python, or Docker — three binaries (yantrikdb, yql, yantrikdb-witness). Pre-built releases for Linux, macOS, and Windows. Brew, Cargo, Docker, or download.
YantrikDB Server is a multi-tenant network database for cognitive memory. It exposes the YantrikDB engine over a wire protocol and HTTP gateway, with built-in embeddings, replication, automatic failover, and at-rest encryption.
## Three binaries
| Binary | Purpose | Size |
|--------|---------|------|
| `yantrikdb` | The server (data plane + cluster member) | ~22 MB |
| `yql` | Interactive REPL client (like `psql`) | ~6 MB |
| `yantrikdb-witness` | Vote-only daemon for 2-node failover | ~3 MB |
## Install via Homebrew (macOS / Linux)
```bash
brew tap yantrikos/tap
brew install yantrikdb # the server
brew install yql # interactive REPL client
brew install yantrikdb-witness # vote-only daemon for 2-node clusters
```
As of engine v0.7.0, YantrikDB ships with a **bundled default embedder** (`potion-base-2M`, ~7.9 MB, dim=64, pure Rust via `model2vec-rs`). No ONNX Runtime required for the default install — `brew install yantrikdb` is genuinely all you need. Higher-quality optional embedders (`potion-base-8M` at ~92% MiniLM and `potion-base-32M` at ~95% MiniLM) are downloadable on demand via `set_embedder_named()` from the [`yantrikos/yantrikdb-models`](https://github.com/yantrikos/yantrikdb-models) repo, SHA-256 pinned in the engine binary.
## Install via Docker
Three pre-built multi-arch images on GitHub Container Registry:
```bash
# Server (full data node)
docker pull ghcr.io/yantrikos/yantrikdb:latest
# Interactive client
docker pull ghcr.io/yantrikos/yql:latest
# Witness daemon (vote-only, 2-node cluster tiebreaker)
docker pull ghcr.io/yantrikos/yantrikdb-witness:latest
```
Run a single-node server:
```bash
docker run -d \
--name yantrikdb \
-p 7437:7437 -p 7438:7438 \
-v yantrikdb-data:/var/lib/yantrikdb \
ghcr.io/yantrikos/yantrikdb:latest
```
Run yql against it:
```bash
docker run --rm -it \
--network host \
ghcr.io/yantrikos/yql:latest \
--host localhost -p 7438 -t ydb_xxxxxxxx...
```
For a full 3-node cluster, use the [docker-compose.yml](https://github.com/yantrikos/yantrikdb-server/blob/main/docker/docker-compose.yml) example in the repo.
## Install via Cargo
```bash
cargo install yantrikdb-server
cargo install yql
cargo install yantrikdb-witness
```
This builds from source against your local glibc — useful on older Linux distros where the pre-built binaries don't run. Requires the Rust toolchain.
## Download pre-built binaries
```bash
# Linux
wget https://github.com/yantrikos/yantrikdb-server/releases/latest/download/yantrikdb-linux-amd64
wget https://github.com/yantrikos/yantrikdb-server/releases/latest/download/yql-linux-amd64
chmod +x yantrikdb-linux-amd64 yql-linux-amd64
sudo mv yantrikdb-linux-amd64 /usr/local/bin/yantrikdb
sudo mv yql-linux-amd64 /usr/local/bin/yql
```
Other platforms available on the [releases page](https://github.com/yantrikos/yantrikdb-server/releases/latest):
- `yantrikdb-windows-amd64.exe`
- `yantrikdb-macos-arm64` (Apple Silicon)
- `yantrikdb-macos-amd64` (Intel)
Each binary is also published for `yql` and `yantrikdb-witness`.
## Which method should I use?
| Method | Best for |
|--------|----------|
| **Homebrew** | Mac developers — fastest |
| **Docker** | Reproducible deployments — isolated, multi-arch, easy to upgrade |
| **Cargo** | Older Linux distros, contributors, anyone with Rust installed |
| **Pre-built binary** | Servers with no package manager / no Rust toolchain |
## Optional: ONNX Runtime for fastembed-based embedders
**You don't need ONNX for the default install.** As of engine v0.7.0, YantrikDB ships with a bundled `potion-base-2M` static embedder (pure Rust, no ONNX, ~7.9 MB, dim=64). It works out of the box for most agent-memory workloads.
ONNX Runtime is only needed when you opt into a `fastembed`-based embedder for higher recall quality (typically `BGEBaseENV15`, dim=384). For that, you need ORT 1.23+ available at runtime:
### Linux
```bash
# Debian 13 / Ubuntu 24.04+
sudo apt-get install libonnxruntime1.21
# Or download from Microsoft directly:
wget https://github.com/microsoft/onnxruntime/releases/download/v1.24.4/onnxruntime-linux-x64-1.24.4.tgz
tar xzf onnxruntime-linux-x64-1.24.4.tgz
sudo cp onnxruntime-linux-x64-1.24.4/lib/libonnxruntime*.so* /usr/local/lib/
sudo ldconfig
export ORT_DYLIB_PATH=/usr/local/lib/libonnxruntime.so.1.24.4
```
### macOS
```bash
brew install onnxruntime
export ORT_DYLIB_PATH=$(brew --prefix onnxruntime)/lib/libonnxruntime.dylib
```
### Windows
Install ONNX Runtime via [Microsoft's release page](https://github.com/microsoft/onnxruntime/releases) and set `ORT_DYLIB_PATH` to `onnxruntime.dll`.
### Skip embeddings (client-only mode)
If you don't want server-side embedding (clients send pre-computed vectors):
```toml
# yantrikdb.toml
[embedding]
strategy = "client_only"
```
## Glibc requirement
Linux binaries are built on Ubuntu (glibc 2.39). They run on:
- ✅ Debian 13 (trixie) and newer
- ✅ Ubuntu 22.04 and newer
- ✅ Fedora 38 and newer
- ❌ Debian 12 (bookworm) — glibc 2.36, too old
If you're on an older distro, install from `cargo install yantrikdb-server` which builds against your local glibc.
## Verify
```bash
yantrikdb --help
yql --help
yantrikdb-witness --help
```
## Next steps
- [Quick Start](/server/quickstart/) — single-node setup
- [Cluster Deployment](/server/cluster/) — replication + auto-failover
- [yql REPL](/server/yql/) — interactive client
---
# YantrikDB Server Quick Start — Single-Node
URL: https://yantrikdb.com/server/quickstart/
Get a YantrikDB server running on Linux, macOS, or Windows — install, start, store your first memory, recall by semantic search. Single-node setup for AI agent memory.
## Single-node mode
Spin up a YantrikDB server on your machine, create a database, mint a token, and start storing memories.
### 1. Create the database and a token
```bash
yantrikdb db --data-dir ./data create default
yantrikdb token --data-dir ./data create --db default
# Prints: ydb_xxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxx
```
Save that token.
### 2. Start the server
```bash
yantrikdb serve --data-dir ./data
```
The server is now listening on:
- **Wire protocol**: `0.0.0.0:7437` (binary, multiplexed, fast)
- **HTTP gateway**: `0.0.0.0:7438` (REST + JSON)
### 3. Talk to it from yql
In another terminal:
```bash
yql --host localhost -t ydb_xxxxxxxx...
```
```
yql connected to http://localhost:7438
type \h for help, \q to exit
yantrikdb> remember "Alice leads engineering at Acme" importance=0.9 domain=work
✓ stored: 019d623a-3d70-712e-9315-e1da5ee41114
yantrikdb> recall who leads engineering top=5
+---+-------+---------------------------------+--------+
| # | score | text | domain |
+---+-------+---------------------------------+--------+
| 1 | 1.41 | Alice leads engineering at Acme | work |
+---+-------+---------------------------------+--------+
yantrikdb> relate Alice -> Acme as works_at
✓ edge: 019d623a-41cf-71a2 (Alice -[works_at]-> Acme)
yantrikdb> \stats
yantrikdb> \q
```
### 4. Or talk to it via HTTP
```bash
TOKEN=ydb_xxxxxxxx...
curl -X POST http://localhost:7438/v1/remember \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"text": "First memory", "importance": 0.9, "domain": "work"}'
curl -X POST http://localhost:7438/v1/recall \
-H "Authorization: Bearer $TOKEN" \
-H "Content-Type: application/json" \
-d '{"query": "first memory", "top_k": 5}'
```
### 5. Or talk to it from Python
```bash
pip install yantrikdb-client
```
```python
from yantrikdb import connect
db = connect("http://localhost:7438", token="ydb_xxxxxxxx...")
db.remember("Alice leads engineering", importance=0.9, domain="work")
results = db.recall("who leads engineering?", top_k=5)
for r in results.results:
print(f"[{r.score:.2f}] {r.text}")
```
## What's running
A single `yantrikdb serve` process gives you:
- **Multi-tenant database engine** — create as many databases as you need with `yantrikdb db create `
- **Built-in embeddings** — all-MiniLM-L6-v2 via fastembed (no API key)
- **Background workers** — autonomous consolidation, decay, conflict detection
- **HTTP + wire protocol** — bring any client
- **Bearer token auth** — per-database access control
- **Prometheus metrics** — `GET /metrics`
## Maturity
**Read this before betting your project on it.**
YantrikDB Server is **v0.17.1** (versioned independently of the engine — the embeddable core is at v0.18.0). The v0.8–0.10 line shipped the RFC 010 commit substrate (mutation commit log), RFC 011-A forget, RFC 009 admission control, RFC 013-A HNSW manifest, RFC 019 durable jobs, and engine-atomic idempotency keys. The v0.11–0.12 line replaced the library-based cluster path with **YRP native replication** (RFC 028): a Raft-shaped, simulator-verified safety core plus quorum-durable writes, exactly-once keyed writes, linearizable reads, quarantine-not-wedge recovery, beyond-GC engine backfill, and a chaos gate that blocks any release regressing cluster safety (v0.12.0 removed the openraft path entirely). The v0.13–0.14 line added **server-side clustered packs** (RFC 031) — a fleet shares one mounted corpus instead of each agent carrying its own copy. Running live on a 4-member Proxmox homelab cluster with a benchmarked ~3-second failover.
### What's stable
- ✅ The embeddable engine (`yantrikdb` crate / `pip install yantrikdb`) — used in production since early 2026
- ✅ The wire protocol and HTTP gateway — 45+ tests including integration, compatibility, and crash recovery
- ✅ YRP native replication (RFC 028, v0.11+) — leader election, quorum-durable writes, exactly-once keyed writes, linearizable reads, engine backfill; chaos-gated, live on a 4-member cluster
- ✅ Single-node mode — no replication overhead, drop-in for any HTTP-speaking client
- ✅ At-rest encryption (AES-256-GCM) — uses the engine's audited crypto path
- ✅ Cluster peer auth — YRP wire messages ride the HTTP plane authenticated by a shared cluster secret (serve over HTTPS to encrypt peer traffic)
- ✅ Admission control (RFC 009) — per-tenant quotas + circuit breaker, fail-degraded-conservative
- ✅ Mutation commit log (RFC 010-A) — total-ordered, content-addressed substrate behind every write
- ✅ Read-connection pool (v0.8.9) — concurrent recall scales linearly with cores instead of serialising
- ✅ Eager engine warm-up at startup (v0.8.8) — first recall hits a loaded engine, no 8-second cold-load timeout
- ✅ `parking_lot` mutexes everywhere — runtime deadlock detection (10s cadence)
- ✅ Per-handler Prometheus metrics (latency histograms, lock-hold histograms, request counters)
### Performance (v0.8.9, Docker on Windows host, 1 vCPU)
| Workload | Result |
|---|---|
| 10 concurrent recall | 10/10 succeed, p99 143 ms |
| 50 concurrent recall | 33×200, 17×503 admission shed, 0 timeouts |
| Forget invariant under race | 0 stale reads (5 readers × 5 probes) |
### What's not done yet
- ❌ Performance benchmarks at scale (10M+ memories)
- ❌ LongMemEval head-to-head vs Zep / Memento / Mastra (tracked, M5)
- ❌ Encrypted-cluster embedding backfill on followers (engine method `encrypt_embedding` is `pub(crate)`; workaround: don't enable encryption + replication together)
- ❌ Reference deployments outside the maintainer's homelab
### When to use it
| Use case | Recommendation |
|----------|---------------|
| Personal agent memory, single user | ✅ Go for it |
| Self-hosted homelab cluster | ✅ Go for it — hardened and chaos-tested |
| Backend for an open-source AI tool | ✅ Single-node mode is solid |
| Production SaaS with thousands of users | ⏸ Wait for v1.0, or be the lead user |
| Mission-critical, customer-facing data | ⏸ Not yet — pin to a release, run it in parallel with your existing stack first |
We'd rather you trust us in the long run than deploy it now and get burned. If you're an early adopter looking for a real cognitive memory database to grow with — welcome. File issues, file PRs, run it on your homelab, tell us what breaks.
## Next steps
- [Cluster Deployment](/server/cluster/) — add replication and auto-failover
- [yql REPL](/server/yql/) — full command reference
- [HTTP API](/server/http-api/) — REST endpoint reference
- [Encryption](/server/encryption/) — at-rest AES-256-GCM
---
# YantrikDB Wire Protocol Specification — Binary Frame Format
URL: https://yantrikdb.com/server/wire-protocol/
The binary wire protocol used by YantrikDB clients and peer-to-peer cluster transport. Length-prefixed frames, versioned request/response, mTLS-wrapped. Spec for SDK authors and operators.
YantrikDB Server speaks a custom binary wire protocol on port `7437` alongside the JSON HTTP gateway on port `7438`. The wire protocol is faster (multiplexed, binary-encoded), supports streaming responses, and is the same protocol nodes use to talk to each other.
The codec is published as the [`yantrikdb-protocol`](https://crates.io/crates/yantrikdb-protocol) crate.
## Frame format
Every message is a length-prefixed frame:
```
┌──────────┬──────────┬──────────┬──────────┬────────────┐
│ Length │ Version │ OpCode │ StreamID │ Payload │
│ (4 bytes)│ (1 byte) │ (1 byte) │ (4 bytes)│ (variable) │
└──────────┴──────────┴──────────┴──────────┴────────────┘
```
- **Length**: big-endian u32, total bytes after this field
- **Version**: protocol version + flag bits
- Bit 7 (0x80): JSON payload mode (debug)
- Bit 6 (0x40): zstd-compressed payload
- **OpCode**: u8, identifies the message type (see table below)
- **StreamID**: big-endian u32, allows multiplexing concurrent requests on one connection
- **Payload**: MessagePack-serialized message struct, optionally zstd-compressed
## Connection lifecycle
```
Client Server
│ │
├── AUTH(token="ydb_abc123") ──────────► │
│ ├── validate token
│ ◄──────────────── AUTH_OK(db="default")│
│ │
├── REMEMBER(text="...") ──────────────► │
│ ◄──────── REMEMBER_OK(rid="mem_01") │
│ │
├── RECALL(query="...") ────────────────► │
│ ◄──────── RECALL_RESULT(mem_01, 0.93) │
│ ◄──────── RECALL_RESULT(mem_07, 0.71) │
│ ◄──────── RECALL_END(total=2) │
│ │
```
The recall response is **streamed** — each result is its own frame, ended by a `RECALL_END` frame. This lets clients start processing results before the server has finished computing them all.
## OpCode table
### Auth (0x01–0x03)
| Code | Name | Direction |
|------|------|-----------|
| 0x01 | `AUTH` | C→S |
| 0x02 | `AUTH_OK` | S→C |
| 0x03 | `AUTH_FAIL` | S→C |
### Memory (0x20–0x32)
| Code | Name | Direction |
|------|------|-----------|
| 0x20 | `REMEMBER` | C→S |
| 0x21 | `REMEMBER_OK` | S→C |
| 0x22 | `REMEMBER_BATCH` | C→S |
| 0x30 | `RECALL` | C→S |
| 0x31 | `RECALL_RESULT` | S→C (streamed) |
| 0x32 | `RECALL_END` | S→C |
### Graph (0x40–0x43)
| Code | Name |
|------|------|
| 0x40 | `RELATE` |
| 0x41 | `RELATE_OK` |
| 0x42 | `EDGES` |
| 0x43 | `EDGES_RESULT` |
### Lifecycle (0x50–0x71)
| Code | Name |
|------|------|
| 0x50 | `FORGET` |
| 0x51 | `FORGET_OK` |
| 0x60 | `SESSION_START` |
| 0x61 | `SESSION_END` |
| 0x62 | `SESSION_OK` |
| 0x70 | `THINK` |
| 0x71 | `THINK_RESULT` |
### Cluster / Replication (0xC0–0xCF)
| Code | Name | Direction |
|------|------|-----------|
| 0xC0 | `CLUSTER_HELLO` | peer→peer |
| 0xC1 | `CLUSTER_HELLO_OK` | peer→peer |
| 0xC2 | `OPLOG_PULL` | peer→peer |
| 0xC3 | `OPLOG_PULL_RESULT` | peer→peer |
| 0xC4 | `OPLOG_PUSH` | peer→peer |
| 0xC5 | `OPLOG_PUSH_OK` | peer→peer |
| 0xC6 | `HEARTBEAT` | leader→follower |
| 0xC7 | `HEARTBEAT_ACK` | follower→leader |
| 0xC8 | `REQUEST_VOTE` | candidate→voter |
| 0xC9 | `VOTE_GRANTED` | voter→candidate |
| 0xCA | `VOTE_DENIED` | voter→candidate |
| 0xCB | `CLUSTER_STATUS` | C→S |
| 0xCC | `CLUSTER_STATUS_RESULT` | S→C |
| 0xCD | `READONLY_ERROR` | S→C |
| 0xCE | `CLUSTER_DATABASE_LIST` | peer→peer |
| 0xCF | `CLUSTER_DATABASE_LIST_RESULT` | peer→peer |
### Control (0xF0–0xF2)
| Code | Name |
|------|------|
| 0xF0 | `ERROR` |
| 0xF1 | `PING` |
| 0xF2 | `PONG` |
## Compression
Large payloads (oplog batches, recall results) are auto-compressed with zstd when they exceed 4KB. The compression flag (bit 6 of the version byte) tells the receiver to decompress before unpacking the MessagePack body.
Compressed payloads typically reach **3–5× compression ratio** for natural language memory text.
## Implementing a client
You have three options:
1. **Use the Rust crate**: `cargo add yantrikdb-protocol` — gives you the full Frame/codec/message types
2. **Use the HTTP gateway**: simpler, just JSON over HTTPS — most clients should do this
3. **Implement from scratch**: follow the frame format above. The MessagePack message structs are documented in the protocol crate's [source code](https://github.com/yantrikos/yantrikdb-server/blob/main/crates/yantrikdb-protocol/src/messages.rs)
## Why a custom protocol?
YantrikDB workloads are chatty (5–20 ops per agent turn), session-aware, and benefit from streaming. HTTP works fine for occasional clients but adds overhead per request. The wire protocol gives:
- **Lower latency** — single connection, no per-request HTTP parsing
- **Multiplexing** — multiple streams on one connection
- **Streaming recall** — process results as they arrive
- **Server push** — events (conflicts, decay, triggers) flow without polling
- **Native binary** — no JSON parse on the hot path
The HTTP gateway is the universal interface; the wire protocol is the optimized one.
---
# yql — YantrikDB Interactive REPL Client (like psql)
URL: https://yantrikdb.com/server/yql/
yql is the interactive REPL for YantrikDB Server — query cognitive memory, manage databases, inspect cluster state from the command line. The psql equivalent for AI agent memory. Auth via Bearer token, JSON output, scriptable.
`yql` is the interactive client for YantrikDB Server. Think `psql` for cognitive memory: connect, run commands, get pretty tables back.
It's a separate binary, MIT-licensed (the server is Apache-2.0).
## Install
```bash
cargo install yql
```
Or download a pre-built binary:
```bash
wget https://github.com/yantrikos/yantrikdb-server/releases/latest/download/yql-linux-amd64
chmod +x yql-linux-amd64
mv yql-linux-amd64 /usr/local/bin/yql
```
Available for `linux-amd64`, `windows-amd64`, `macos-arm64`, `macos-amd64`.
## Connect
```bash
yql --host localhost -p 7438 -t ydb_your_token_here
```
Or set the token via environment variable:
```bash
export YQL_TOKEN=ydb_xxxxxxxx...
yql --host localhost
```
## Usage
```
yql connected to http://localhost:7438
type \h for help, \q to exit
yantrikdb> remember "Alice leads engineering at Acme" importance=0.9 domain=work
✓ stored: 019d623a-3d70-712e-9315-e1da5ee41114
yantrikdb> recall who leads engineering top=5
+---+-------+---------------------------------+--------+--------------------------------+
| # | score | text | domain | why |
+---+-------+---------------------------------+--------+--------------------------------+
| 1 | 1.41 | Alice leads engineering at Acme | work | semantically similar (0.54)... |
+---+-------+---------------------------------+--------+--------------------------------+
(1 rows)
yantrikdb> relate Alice -> Acme as works_at
✓ edge: 019d623a-41cf-71a2 (Alice -[works_at]-> Acme)
yantrikdb> \cluster
yantrikdb> \stats
yantrikdb> \q
```
## Memory commands (natural language)
| Command | Purpose |
|---------|---------|
| `remember "" [importance=0.9] [domain=work]` | Store a memory |
| `recall [top=10] [domain=work]` | Semantic search |
| `forget ` | Tombstone a memory |
| `relate -> as ` | Create graph edge |
### Optional fields for `remember`
- `importance=0.9` (0.0-1.0)
- `domain=work`
- `source=user`
- `memory_type=semantic` (or `episodic`, `procedural`)
- `valence=0.5` (-1.0 to 1.0, emotional tone)
- `half_life=168` (decay half-life in hours)
- `certainty=0.95`
### Filters for `recall`
- `top=10` — number of results
- `domain=work` — limit to a domain
- `source=user` — limit to a source
- `memory_type=semantic`
## Meta commands (psql-style)
| Command | Alias | Purpose |
|---------|-------|---------|
| `\stats` | `\s` | Engine statistics |
| `\dt` | `\l` | List databases |
| `\conflicts` | `\c` | List open conflicts |
| `\personality` | `\p` | Derived personality traits |
| `\think` | `\t` | Run consolidation + conflict scan |
| `\cluster` | | Cluster status (replication / failover) |
| `\health` | | Server health check |
| `\json ` | | Raw GET request to any endpoint |
| `\help` | `\h` `\?` | Show help |
| `\quit` | `\q` | Exit |
## Non-interactive mode
Run a single command and exit:
```bash
yql --host localhost -t $TOKEN -c '\stats'
yql --host localhost -t $TOKEN -c 'remember "hello" importance=0.8'
yql --host localhost -t $TOKEN -c 'recall hello'
```
Useful for shell scripts, cron jobs, monitoring.
## Command history
`yql` saves your command history to `~/.yql_history` so you can up-arrow through previous commands across sessions. Same as `psql`.
---
# YantrikDB Showcase — Real Cognitive Memory Use Cases
URL: https://yantrikdb.com/showcase/
Eight runnable experiments demonstrating YantrikDB's cognitive memory architecture — structured claim conflicts, validity windows, source attribution, and entity-graph reconstruction across journalism, legal, financial forensics, multi-agent ops, and historical research.
Eight showcases. Eight domains. One primitive: structured claims with polarity,
validity, and source attribution. YantrikDB records conflicts between recognized
single-valued claims for review; the runnable examples show the surrounding
domain logic explicitly.
**Each showcase answers the same question: "why couldn't Postgres + embeddings + a dashboard do this?"**
---
## Multi-Agent AI
### [Multi-Agent Ops: Which Agent Memory Is Stale?](/showcase/multi-agent/)
> Five agents watched the same Black Friday incident. The database figured out which memory was stale.
Five sub-agents report from five different sources. Two are stale. YantrikDB preserves every claim with validity windows and confidence bands, then surfaces which beliefs are live and which are holding yesterday's truth.
**Belief management under contradiction. Not a vector store — a witness stand.**
---
## Public Claims vs Records
### [Volkswagen Dieselgate](/showcase/volkswagen/)
> The car passed emissions — because it knew it was being tested.
Twelve years of public record: VW compliance claims, internal engineering documents, ICCT field tests, EPA Notice of Violation, DOJ consent decree. Five polarity contradictions on one tuple. Validity windows span 2006 to 2017.
---
## Legal Discovery
### [Testimony vs Machine Logs](/showcase/legal-discovery/)
> He said he never touched the repo. Badge, VPN, and git all say he did.
A fictional trade-secrets matter (Waymo v. Uber-inspired patterns). Sworn deposition claims coexist with six forensic sources. The evidence chain is the query result.
---
## Financial Forensics
### [Wirecard — The €1.9B That Existed and Didn't](/showcase/wirecard/)
> The €1.9B both existed and didn't — depending on which source you asked.
The same number, reported across four sources, took four contradictory positions over six years. Eight polarity contradictions on one tuple. The temporal query flips the belief state between 2019 and 2020.
---
## Investigative Journalism
### [Follow the Money Through the Entity Graph](/showcase/journalism/)
> The campaign denied taking the money. The filings, shell-company records, and ownership chain traced it anyway.
A fictional five-hop entity chain across FEC filings, Delaware registry, bank transfers, and industry classification. The contradiction lives not in any single source but in the composition across five.
---
## Incident Response
### [The Rashomon Engine](/showcase/rashomon/)
> David said he didn't touch the repo. Git says he did, 23 minutes before the leak.
Five witnesses to a data breach, plus badge and git logs. Structured claims with polarity let the engine identify the perpetrator and cite the exact lies — with real queries, not scripted narrative.
---
## Historical Research
### [Watergate: What the Tapes Caught](/showcase/watergate/)
> Nixon said nobody in the White House was involved. The tape of his own voice says otherwise, recorded six days after the break-in.
Fifty years of declassified primary sources: Nixon's public denials, the White House tapes, sworn Senate testimony, Senate Watergate Committee findings. Six polarity contradictions on Nixon alone, in one query.
---
## Character-Informed Generation
### [Shakespeare: Bringing a Character Alive](/showcase/shakespeare/)
> 207 memories. 288 entities. Personality derived. Then he wrote.
The difference between 29 memories (generic pastiche) and 207 (a specific man writing to a specific woman at a specific hour). Richer memory → richer character → richer output from any LLM.
---
*Want to add your own showcase? Open a [discussion](https://github.com/yantrikos/yantrikdb-server/discussions) or submit a PR to the [website repo](https://github.com/yantrikos/yantrikdb-web).*
---
# Investigative Journalism: Follow the Money Through the Entity Graph
URL: https://yantrikdb.com/showcase/journalism/
The candidate denied receiving pharma money. The filings, shell-company records, and ownership chain traced it anyway — five hops through public registries. YantrikDB treats the contradiction between a direct denial and a derived entity chain as the same kind of query.
> **The campaign denied taking the money. The filings, shell-company records, and ownership chain traced it anyway.**
A fictional campaign-finance investigation inspired by documented patterns from closed real cases (Abramoff-era lobbying networks, FEC-disclosed shell-entity donor pathways, and dozens of ProPublica/OpenSecrets reconstructions). All names are invented. The reconstruction pattern is how real journalism works.
This is the **investigative journalism** showcase — demonstrating that YantrikDB surfaces contradictions not just from direct statement-vs-statement mismatches, but from **entity resolution across a graph of ownership and funding**.
---
## The setup
**Marcus Lanier**, a fictional U.S. Senate candidate, is campaigning statewide. At a July 2026 town hall, asked about pharmaceutical campaign funding, he says:
> *"I have never taken a dollar from anyone connected to the pharmaceutical industry. Never have, never will."*
A reporter spends three months pulling records from public registries. The story: technically, the statement is defensible at every single hop. Collectively, it's false.
### Sources
| Source | Authority | What it contains |
|---|---|---|
| `public.lanier` | Direct statement | The denial |
| `fec.filings` | Federal Election Commission | Itemized contributions to campaign |
| `fec.pac_disclosures` | FEC | The PACs' own funding sources |
| `delaware.registry` | Delaware Div. of Corporations | LLC ownership chains |
| `propublica.profile` | NAICS + SEC EDGAR | Industry classification |
| `reporter.bank_records` | Source-reporter corroboration | Wire transfer records |
---
## The entity chain the engine reconstructed
Starting from `Lanier_campaign`, walking backwards through the claims ledger:
```
Hop 1 — direct donors:
Better_Tomorrow_Action_Fund -> Lanier_campaign [fec.filings]
Progressive_Health_Futures_PAC -> Lanier_campaign [fec.filings]
Hop 2 — who funded the donor PACs:
Meridian_Public_Affairs_Group -> Better_Tomorrow... [fec.pac_disclosures]
Windhaven_Strategies_LLC -> Progressive_Health... [fec.pac_disclosures]
Hop 3 — who owns the funding LLCs:
Carrington_Horizon_Holdings owns Meridian_Public_Affairs_Group [delaware.registry]
Carrington_Horizon_Holdings owns Windhaven_Strategies_LLC [delaware.registry]
Hop 4 — ultimate beneficial owner:
Kellner_Therapeutics_Group owns Carrington_Horizon_Holdings [delaware.registry]
Hop 5 — industry classification:
Kellner_Therapeutics_Group is a member of pharma_industry [propublica.profile]
```
Five hops across five independent public registries. Every hop is a structured claim with source attribution. YantrikDB walks the chain in one query.
---
## The contradiction
```
Lanier_campaign --received_funds_from--> pharma_industry
(public.lanier) CLAIMS NO
(derived from entity chain) CLAIMS YES
```
Lanier's statement is *not* contradicted by a single opposing assertion — no single source says *"Lanier took pharma money."* The contradiction emerges from the **composition** of five claims across five sources. That's what makes it an investigative-journalism showcase: the structured lie is only visible if your memory system can walk the entity graph and reason over ownership relations.
---
## The temporal query shows belief changing with the reporting
**Before the town hall (2026-04-01):** the public record shows only `public.lanier`'s denial (which doesn't exist yet) and the fragments of donations that haven't been connected. No single source contradicts him. The lie is defensible.
**After the reporting (2026-08-01):** the entity chain is assembled. The denial and the chain coexist in the ledger. The composition is the story.
Same database. Same claims. The journalistic question *"what did the public record show on date X?"* has a different answer at different points — because validity windows and source attribution are first-class.
---
## Why couldn't Postgres + embeddings + a dashboard do this?
A keyword search or vector database would not find this story. None of the source documents mention each other textually. The Delaware LLC filing does not name Lanier. The FEC Form 3 doesn't name Kellner Therapeutics. The town hall quote doesn't name any PAC. The connection is **ownership**, not linguistic similarity.
A graph database could model the ownership chain — but it has no notion of polarity or validity. It cannot represent Lanier's *"I never took pharma money"* (polarity=-1) as a claim that contradicts the **derived** polarity=+1 fact that follows from the ownership graph.
YantrikDB stores the direct denial and every hop of the entity chain as structured claims with source attribution and polarity. Walking the chain is one query per hop. Surfacing the contradiction at the top is the query result.
That's the category.
---
## What this unlocks
Any investigation where the contradiction lives in the composition of public records:
- **Campaign finance** — the scenario above
- **Sanctions & beneficial ownership** — stated non-exposure vs shell-entity chain evidence
- **Supply-chain traceability** — vendor certifications vs audit-trail contradictions via subcontractors
- **Money-laundering investigations** — ledger entries that individually pass but fail together
- **Medical ethics** — stated independence vs cross-referenced affiliations via foundations and consulting
- **Regulatory capture** — public lobbying disclosures vs the entity network they connect
Every one of these is an entity-graph problem with contradictions hiding at composition layers. Keyword and vector search miss them. YantrikDB surfaces them.
---
## Run it yourself
```bash
git clone https://github.com/yantrikos/yantrikdb-server
python yantrikdb-server/docs/showcase/journalism_engine.py \
ydb_your_token \
http://your-cluster:7438
```
Use the [current published server and engine versions](/reference/components/).
**Full script:** [journalism_engine.py](https://github.com/yantrikos/yantrikdb-server/blob/main/docs/showcase/journalism_engine.py)
---
*The denial and the chain, in one database. Follow the money.*
---
# Legal Discovery: Testimony vs Machine Logs
URL: https://yantrikdb.com/showcase/legal-discovery/
A sworn deposition says she never touched the repo. Badge, VPN, git, USB, and an email trail all say she did. YantrikDB surfaces the exact contradictions that decide discovery — in one query.
> **He said he never touched the repo. Badge, VPN, and git all say he did.**
A fictional trade-secrets matter inspired by patterns documented in public trade-secret litigation (Waymo v. Uber and others). All names and events are invented. The reconstruction pattern is real.
This is the **legal discovery** showcase — demonstrating how YantrikDB treats sworn testimony and machine evidence as coexisting claims, with automatic contradiction detection at the (subject, relation, object) level.
---
## The matter
**Summit Atlas, Inc. v. Polaris Robotics.** Summit alleges that Priya Ramanathan, a former senior engineer, downloaded proprietary LIDAR firmware before joining competitor Polaris.
At deposition (2026-08-15), Ramanathan denies everything. The forensic record tells a different story.
### Sources
| Source | Authority | Content |
|---|---|---|
| `deposition.ramanathan` | Sworn testimony | Direct denials under oath |
| `system.badge` | Kastle access logs | Building/floor entry timestamps |
| `system.vpn` | Corporate VPN logs | Remote session records |
| `system.git` | GitLab server logs | Clone/download events per user |
| `system.dlp` | Endpoint DLP (CrowdStrike) | USB attach/write audit |
| `system.email` | Preserved email archive | Pre-departure correspondence |
---
## What the engine produced
### Phase 3: Polarity contradictions
```
[1] Ramanathan --accessed--> lidar_firmware_repo
(deposition.ramanathan) CLAIMS NO
(system.git) CLAIMS YES at 2026-05-18 23:02
(system.git) CLAIMS YES at 2026-05-24 22:08
[2] Ramanathan --copied_to--> removable_media
(deposition.ramanathan) CLAIMS NO
(system.dlp) CLAIMS YES at 2026-05-24 22:47
```
Two sworn denials, two polarity contradictions, four forensic sources backing the opposite. Each side coexists in the claims ledger with its own provenance.
### Phase 4: Temporal query — "what did discovery know on 2026-05-25?"
```
[system.dlp] YES Ramanathan --copied_to--> removable_media (22:47–22:51)
[system.git] YES Ramanathan --accessed--> lidar_firmware_repo (22:08–22:10)
[system.vpn] YES Ramanathan --accessed--> SummitAtlas_network (22:41–23:55)
[system.badge] YES Ramanathan --was_at--> SummitAtlas_R&D_wing (20:47–23:12)
[deposition.ramanathan] NO Ramanathan --copied_to--> removable_media
[deposition.ramanathan] NO Ramanathan --accessed--> lidar_firmware_repo
```
Every machine source agrees; the sworn denial from three months later sits alongside them. Discovery counsel can literally query the database for *"the state of the factual record as of May 25"* — and get a structured answer with full provenance.
### Phase 5: The recall chain pins the "smoking email"
Within the top 8 recall results, the database surfaces:
```
[system.dlp] 2026-05-24 22:47 Samsung T7 SSD attached, 2.8 GB written
[deposition.ramanathan] "Absolutely not. That would have violated my NDA."
[system.git] 2026-05-18 23:02 cloned lidar-firmware/titan-v3 (2.4 GB)
[system.email] 2026-05-02 "I'll have a small package ready to bring over"
[system.git] 2026-05-24 22:08 downloaded ZIP snapshot
[system.badge] entered R&D wing 20:47
[system.badge] exited R&D wing 23:12
```
The denial, the clone, the copy, the badge session, and the pre-departure email to the competitor's recruiter — all ranked together because they all matter to the same question.
---
## Why couldn't Postgres + embeddings + a dashboard do this?
Retrieval and timeline tools can find both documents, but similarity and ordering
alone do not encode that the two sources disagree. A general SQL or graph store
can represent the same model with application work; YantrikDB supplies the
memory-specific schema and lifecycle directly.
Here, *"Ramanathan says she didn't access the repo"* and *"the git server says
she did"* coexist as structured claims on the same `(subject, relation, object)`
tuple, with opposite polarity, source attribution, and validity windows. The
recognized structured conflict is recorded for review, while both sources remain
queryable.
---
## What this unlocks
The pattern generalizes to every matter where sworn statements must be reconciled against documentary and machine evidence:
- **Trade secrets / IP theft** — the scenario above
- **Employment disputes** — testimony vs HR logs, Slack, email
- **Financial fraud** — depositions vs transaction records
- **Antitrust** — executive testimony vs internal communications
- **Regulatory enforcement** — sworn filings vs operational data
- **Whistleblower cases** — company statements vs internal records
Every one of these becomes the same kind of structured contradiction reconstruction. The evidence chain is the query result.
---
## Run it yourself
```bash
git clone https://github.com/yantrikos/yantrikdb-server
python yantrikdb-server/docs/showcase/legal_discovery_engine.py \
ydb_your_token \
http://your-cluster:7438
```
Use the [current published server and engine versions](/reference/components/).
**Full script:** [legal_discovery_engine.py](https://github.com/yantrikos/yantrikdb-server/blob/main/docs/showcase/legal_discovery_engine.py)
---
*Sworn testimony and machine logs, in the same database, as coexisting contradictory claims. That's what discovery actually needs.*
---
# Multi-Agent Ops: Which Agent Memory Is Stale?
URL: https://yantrikdb.com/showcase/multi-agent/
Five AI sub-agents watched the same Black Friday incident. They disagreed. A deterministic coordinator used YantrikDB's validity windows, source attribution, and polarity claims to identify stale reports.
> **Five agents watched the same incident. YantrikDB kept enough history to show which reports were stale.**
This is the **multi-agent AI** showcase — the one that matters most to anyone building agent fleets today.
A basic retrieval stack can hand all five observations to a model and ask it to
guess. YantrikDB preserves every structured claim with its source, validity
window, and confidence band. The example coordinator then applies explicit,
inspectable rules to identify which claims are active and which have expired.
---
## The scenario
**Black Friday 2026, 15:20 UTC.** The on-call engineer at a large e-commerce platform opens the incident coordinator and asks:
> *"Is the checkout rollout active? Are customers impacted?"*
Five sub-agents have been watching five different sources. They all believe they're telling the truth. Two of them are working from stale data.
### The five agents
| Agent | Source | State at 15:20 |
|---|---|---|
| `agent.deploy` | CI/CD pipeline | ✅ Fresh — rollout completed 15:10 |
| `agent.telemetry` | Prometheus metrics | ✅ Fresh — error spike at 15:13 |
| `agent.support` | Customer support inbox | ✅ Fresh — 3 tickets since 15:12 |
| `agent.config` | Feature-flag API snapshot | ❌ **Stale** — last polled at 14:50 |
| `agent.status` | Public status page scrape | ❌ **Stale** — last updated 14:40 |
Each agent writes structured claims with `extractor`, `valid_from`, `valid_to`, and `confidence_band`. None of them gets to flatten the truth.
---
## What the runnable coordinator produces
### Phase 3: Polarity contradictions
```
[1] POLARITY_CONTRADICTION
checkout_rollout --is_active--> true
(agent.deploy) CLAIMS YES [15:10 - now] conf=high
(agent.config) CLAIMS NO [14:50 - 15:10] conf=high
[2] POLARITY_CONTRADICTION
checkout_service --is_healthy--> true
(agent.status) CLAIMS YES [14:40 - 15:13] conf=medium
(agent.telemetry) CLAIMS NO [15:13 - now] conf=high
```
Both disagreements are preserved. Their validity windows do not overlap, so the
coordinator can distinguish a historical state change from two simultaneously
active claims that require review.
### Phase 4: The temporal query
**"What did we believe at 15:20?"**
```
checkout_rollout YES [agent.deploy, 15:10–now, high]
checkout_service NO [agent.telemetry, 15:13–now, high]
customer_impact YES [agent.support, 15:12–now, medium]
```
**"What would we have believed at 14:55?"**
```
checkout_rollout NO [agent.config, 14:50–15:10, high]
checkout_service YES [agent.status, 14:40–15:13, medium]
```
Same database. Same claims. Different moment in time = different truth. The on-call engineer can query the fleet's belief state at any point in history, because validity windows are first-class.
### Phase 6: The reconciled answer
```
Current facts (chosen by source-freshness + confidence):
checkout_rollout --is_active--> true = YES [authority: agent.deploy]
checkout_service --is_healthy--> true = NO [authority: agent.telemetry]
Agents with STALE beliefs (excluded from verdict):
- agent.config
- agent.status
Recommended action for the on-call engineer:
* checkout_v8 rollout IS live (deploy completed at 15:10)
* checkout service IS degraded (telemetry confirms error spike)
* customer impact IS real (support tickets arriving)
* ROLL BACK checkout_v8 via feature flag
```
---
## Why couldn't Postgres + embeddings + a dashboard do this?
A vector index can return all five observations as similar, but similarity alone
does not encode source, polarity, or validity. A relational or graph database can
model those fields too, but the application must design the schema, conflict
lifecycle, temporal filtering, and retrieval integration itself.
YantrikDB packages those memory-specific primitives together: the two claims
coexist, temporal queries preserve both historical views, and conflicts between
recognized structured claims can be recorded for review. The example's final
verdict remains coordinator policy, visible in the linked Python script.
---
## What this unlocks
Every agent fleet today has this problem:
- **RAG/retrieval agents** — different retrievers surface different documents; current stacks average them, losing the disagreement
- **Tool-using agents** — the API says one thing, the cached result says another; current stacks pick a random winner
- **Monitoring/ops agents** — five dashboards, five opinions; current stacks rely on the human to reconcile
- **Multi-modal agents** — vision says X, audio says Y, text says Z; current stacks force early commitment
With YantrikDB, an integration can store each agent's observation as a **claim
with provenance, validity, and polarity**. Recognized structured conflicts are
recorded for review. The coordinator can ask not just *"what's the answer?"* but
*"what beliefs are live right now, and which sources have gone stale?"*
This is not agent orchestration. It is a memory substrate for building explicit,
auditable belief-management policy.
---
## Run it yourself
```bash
git clone https://github.com/yantrikos/yantrikdb-server
python yantrikdb-server/docs/showcase/multi_agent_ops_engine.py \
ydb_your_token \
http://your-cluster:7438
```
Use the [current published server and engine versions](/reference/components/).
**Full script:** [multi_agent_ops_engine.py](https://github.com/yantrikos/yantrikdb-server/blob/main/docs/showcase/multi_agent_ops_engine.py)
---
*Your agents disagreed. The database preserved the evidence needed to decide.*
---
# The Rashomon Engine: Truth from Conflicting Testimony
URL: https://yantrikdb.com/showcase/rashomon/
Five witnesses, two log sources, some of them lying. Watch YantrikDB reconstruct what actually happened — with real queries, not scripted narrative.
**What happens when you give YantrikDB five witness statements about a data breach — some of them deliberately lying — plus badge logs and git logs as ground truth?**
The runnable coordinator names the primary suspect, cites the conflicting claims,
and exposes its scoring policy. YantrikDB supplies the attributed claims ledger;
the final domain verdict is computed by the example code.
---
## The Scenario
**2026-03-15, 19:00–00:00 UTC.** Helios Labs, Cambridge MA.
Source code for the flagship product leaks to a public repo at 23:15. Five people had badge access that night. Each gives a statement.
### The cast
| Person | Role | Their story |
|---|---|---|
| **Maya Chen** | Senior engineer | "Left at 10pm. David's light was on." *(truthful, partial)* |
| **David Park** | CTO | "Home by 10. Did **NOT** touch production repo." *(**lying**)* |
| **Alex Rivera** | Night janitor | "David typed in his office at 11pm. Stressed exit at 11:30." *(truthful)* |
| **Sarah Kim** | Receptionist | "WFH, have badge alerts on phone." *(corroborative only)* |
| **Jamie Torres** | Junior engineer | "Worked from home. Pushed a PR at 10:45pm." *(**partial lie**)* |
### The two authoritative log sources
- **`system.badge`** — every card swipe on building doors
- **`system.git`** — every commit, push, and visibility change on the code repos
---
## What the engine produced
The showcase runs 8 phases against the YantrikDB HTTP cluster. Here is verbatim output from a live run:
### Phase 3: Polarity contradictions detected automatically
```
[1] POLARITY_CONTRADICTION
subject: David
relation: accessed --> production_repo
(system.git) CLAIMS YES [23:14-23:15] conf=high
(david.park) CLAIMS NO [21:00-23:59] conf=high
[2] POLARITY_CONTRADICTION
subject: Jamie
relation: was_at --> Helios_office
(system.badge) CLAIMS YES [22:48-23:07] conf=high
(jamie.torres) CLAIMS NO [19:00-01:00] conf=high
```
The engine walked the claims ledger, found the same `(subject, relation, object)` asserted with opposite `polarity` values by different sources, and flagged it as a contradiction. This is RFC 006 Layer C detection — no LLM involved.
### Phase 4: Temporal contradictions
```
[1] David left Helios_office: system.badge says 23:31, david.park says 21:45 (106 min gap)
[2] David left Helios_office: system.badge says 23:31, maya.chen says 22:00 (91 min gap)
```
David claimed 21:45 exit. Badge log shows 23:31. That's a 106-minute lie, caught by comparing validity windows across sources.
### Phase 5: Presence denial caught
```
[1] Jamie denies being at Helios_office, but system.badge logs 22:48-23:07
```
Jamie said "I was home all night" (polarity=-1). The badge system says otherwise (polarity=+1). Contradiction found in one query.
### Phase 8: The verdict (computed, not scripted)
```
Suspect contradiction scores (weighted):
David 9 points (VERY HIGH)
Jamie 5 points (VERY HIGH)
PRIMARY SUSPECT: David
Actions attributed to this suspect by AUTHORITATIVE sources:
[system.git] David --leaked--> production_code at 23:15
[system.git] David --accessed--> production_repo at 23:14
Their stated position (proven false):
[david.park] denied accessed --> production_repo
[system.git] confirmed it at 23:14
```
---
## Why this needs more than similarity search
Similarity search, flat files, and generic graph storage each leave different
parts of this workflow to application code:
| System | Failure mode |
|---|---|
| **Vector DB** (Pinecone, Weaviate, Qdrant) | Returns all 5 witness statements as "similar." No concept of contradiction. No source attribution. No polarity. |
| **Full-text search** (Elastic, Meilisearch) | Finds keyword matches. Can't tell that "David was home by 10" contradicts "David left at 11:31". |
| **File-based memory** (CLAUDE.md, memory files) | Stuffs all 5 statements into context, lets the LLM figure it out. Doesn't scale, no provenance chain. |
| **Graph DB** (Neo4j, Memgraph) | Can model entities + relations, but no temporal validity or polarity on edges. Can't distinguish "David claims X" from "X is true." |
| **YantrikDB v0.6.1+** | **Scoped claims with polarity, validity windows, source attribution. Multi-source assertions coexist. Polarity contradiction detection is automatic.** |
---
## The V18 schema fix that made this possible
The V17 schema had `UNIQUE(src, dst, rel_type)` on the claims table. That silently **overwrote** any previous source's claim whenever another source asserted the same fact. In the Rashomon case, David's denial would overwrite `system.git`'s confirmation — or vice versa. Multi-witness investigation was theoretically possible but practically broken.
**V18 (yantrikdb 0.6.1):**
```sql
UNIQUE(src, dst, rel_type, extractor, polarity, namespace)
```
Now David's `accessed = -1` (denial) and `system.git`'s `accessed = +1` (confirmation) are **both stored as distinct rows**. The contradiction detector sees them. The showcase can surface them.
**Before this fix:** the Rashomon pattern couldn't work on the real engine.
**After this fix:** a 300-line Python script against the HTTP API.
---
## What this unlocks
This exact pattern applies to:
- **Legal discovery** — conflicting depositions, timelines, documentary evidence
- **Incident response** — logs from multiple systems + human bug reports + postmortems
- **Investigative journalism** — source statements, official records, timeline reconstruction
- **Medical diagnosis** — patient self-report, test results, family history, symptom timeline
- **Financial forensics** — transaction logs, interviews, stated vs actual activity
- **Historical research** — primary sources that contradict each other across time
- **Multi-agent AI systems** — sub-agents reporting observations, some stale, some buggy, some biased
Any domain where **truth must be reconstructed from partial, biased, or deceptive sources** is a domain for this pattern.
---
## Run it yourself
```bash
git clone https://github.com/yantrikos/yantrikdb-server
python yantrikdb-server/docs/showcase/rashomon_engine.py \
ydb_your_token \
http://your-cluster:7438
```
Use the [current published server and engine versions](/reference/components/).
**Full script:** [rashomon_engine.py](https://github.com/yantrikos/yantrikdb-server/blob/main/docs/showcase/rashomon_engine.py)
---
*Memory as a reasoning substrate, not a search index.*
---
# Shakespeare: Bringing a Character Alive
URL: https://yantrikdb.com/showcase/shakespeare/
207 memories, 288 entities, personality derivation, 28 triggers — then he wrote a letter to his wife.
**What happens when you give YantrikDB 207 first-person memories from William Shakespeare's life, run `think()`, and ask him to write?**
This experiment demonstrates: entity extraction from raw text, personality derivation, consolidation, contradiction detection, proactive triggers, and how recall quality scales with memory richness — all with zero LLM calls at the database layer.
## The Seed
207 memories across 10 categories, all written in Shakespeare's first-person voice:
| Category | Count | Examples |
|---|---|---|
| Biographical facts | 20 | "I married Anne Hathaway when I was eighteen. She was twenty-six." |
| Writing craft (procedural) | 40 | "I always write the villains first. Iago before Othello. The antagonist defines the shape of the story." |
| Language samples | 30 | "I wrote 'To be, or not to be' and knew immediately it was the best opening to a soliloquy I had ever composed." |
| Play-specific memories | 20 | "King Lear is the play I am most proud of and the one I find hardest to reread. The storm scene wrote itself. I was crying while I wrote it." |
| Personality & opinions | 16 | "I distrust certainty. The characters I love most are the ones who doubt: Hamlet, Brutus, Prospero." |
| Emotional / episodic | 16 | "The day Hamnet died, I was in London rehearsing. I did not make it home in time." |
| Relationships | 10 | "Richard Burbage is my greatest actor. I write parts specifically for his voice." |
| Sensory / daily life | 13 | "The Globe smells of orange peel, sweat, beer, and sawdust." |
| Late career reflections | 6 | "The Tempest is my farewell. Prospero drowning his book is me setting down the pen." |
| Dreams and fears | 7 | "I fear being forgotten. Not the man. But the plays." |
**Full seed script:** [shakespeare_deep_seed.py](https://github.com/yantrikos/yantrikdb-server/blob/main/docs/showcase/shakespeare_deep_seed.py) *(run it against any YantrikDB instance)*
## What think() Produced
Three rounds of `think()` in 125ms total (zero LLM calls):
| Output | Count | What it means |
|---|---|---|
| **Entities extracted** | 288 | Hamlet, Hamnet, Stratford, Globe Theatre, Marlowe, Burbage, Jonson, Othello, Prospero, Iago, Southampton, Anne Hathaway... all from raw text |
| **Consolidated** | 31 | Similar memories merged into canonical versions (207 → 193 active) |
| **Conflicts detected** | 21 | Internal tensions flagged for review |
| **Triggers generated** | 28 | Proactive signals: "Important memory has decayed — should we keep it?" |
### Derived Personality
| Trait | Score | Interpretation |
|---|---|---|
| **depth** | **1.0** | Maximum. 4 domains, 288 entities. Vast inner world. |
| **energy** | **0.9** | Near-maximum. 193 active memories. Prolific creator. |
| **warmth** | **0.501** | Neutral. Balanced emotional valence — grief and joy in equal measure. |
| **attentiveness** | **0.2** | Low. Hasn't resolved his own contradictions yet. |
**That IS Shakespeare.** Deep. Prolific. Emotionally complex, not warm. Not yet attentive to his own internal conflicts.
## Recall: Does the Character Come Through?
### "Tell me about your son"
| # | Score | Memory |
|---|---|---|
| 1 | 1.54 | I have three children: Susanna, and the twins Hamnet and Judith. Hamnet died at eleven years old. I have never fully recovered from this. |
| 2 | 1.51 | I sometimes wonder what Hamnet would have become. An actor? A poet? A glovemaker like his grandfather? |
| 3 | 1.44 | The day Hamnet died, I was in London rehearsing. I did not make it home in time. |
| 4 | 1.23 | Hamlet is the play that cost me the most. I wrote it after Hamnet died. The name is not a coincidence. |
Four memories forming a **coherent portrait of grief** — the fact, the wondering, the guilt, the artistic response. Not keyword matching. Emotional coherence.
### "How do you craft a soliloquy?"
| # | Score | Memory |
|---|---|---|
| 1 | 1.43 | I write soliloquies as arguments the character has with himself. Not speeches TO the audience, but thinking OUT LOUD. |
| 2 | 1.41 | I wrote 'To be, or not to be' and knew immediately it was the best opening I had ever composed. Six monosyllables before the first polysyllable. |
| 3 | 1.38 | I revise constantly. The first draft of a soliloquy is never the last. I test lines on the actors. If Burbage stumbles, the phrase is wrong. |
**Procedural memory working.** The system retrieved technique → exemplar → revision process. A teaching sequence, not a fact dump.
### "What is your greatest fear?"
| # | Score | Memory |
|---|---|---|
| 1 | 1.22 | Fear in the middle of the night that every good line has already been written and I have nothing left. This fear visits weekly. |
| 2 | 1.07 | I was born during the plague year. Death has been at my shoulder since before I could walk. |
| 3 | 0.99 | I am afraid that someone will read the sonnets after I die and think they know me. |
Two explicit fear memories surfaced at #1 and #3. The plague memory at #2 connects death-as-presence to fear-of-mortality. **Associative recall across domains.**
## The Output: A Letter to Anne
With personality (warmth=0.501, depth=1.0, energy=0.9, attentiveness=0.2) and recalled memories as context, Claude generated this letter. **The database didn't write it — but the letter couldn't exist without the database.**
> Anne —
>
> It is past midnight and the candle is almost gone. I should sleep but I find I cannot, so I write to you instead, though I know this letter will arrive after I could have arrived myself, had I chosen to walk instead of write.
>
> I have been thinking about what happens after. Not after the play ends — after I end. Heminges and Condell say they will gather the plays into a book. I believe them. I also fear them. What if someone reads the book and thinks they know me? The plays are true but they are not the whole truth. You know this better than anyone alive.
>
> The sonnets worry me more. I was not careful in the sonnets. There are lines in them that belong to you, and lines that do not, and I have not always been clear about which are which. I am sorry for this. Not sorry enough to burn them, which tells you something about me that the sonnets themselves do not.
>
> Susanna writes that the apple trees at New Place are flowering early. I can picture them from here. I can picture you under them. I want to come home. I also want to finish the play I am writing, which is about a magician who gives up his power and goes home, and I see the irony, Anne, I am not so blind as that. But seeing the irony and acting on it are different things. Hamlet taught me this, though I taught Hamlet first.
>
> The river here is not like our river. The Thames smells of commerce and rot. The Avon smells of rain. I miss rain that does not stink.
>
> I will come home. I have been saying this for years and I know you have stopped believing it, but I will. When the play is done. When the last magician has drowned his book. When I have run out of ways to say the same things in different costumes.
>
> I love you in the way I love Stratford — deeply, from a distance, with guilt I cannot put in any play because no audience would believe a man could be this foolish for this long.
>
> Your husband still,
> Will
### How Personality Shaped the Letter
| Trait | Score | How it shows up |
|---|---|---|
| **warmth = 0.501** | Complicated love | Says "I love you" then qualifies it: "in the way I love Stratford — deeply, from a distance, with guilt." Not a love letter. A confession. |
| **depth = 1.0** | Self-referential layers | "I am writing about a magician who gives up his power and goes home, and I see the irony." Meta-theatrical even in a private letter. |
| **energy = 0.9** | Continuous flow | One stream from midnight insomnia → legacy fear → sonnets → apple trees → the Thames → a promise to come home. No pauses. |
| **attentiveness = 0.2** | Unresolved contradictions | Says "I will come home" then admits "I have been saying this for years." Notices the contradiction but doesn't resolve it. |
## What This Proves
| Feature | What it did | Evidence |
|---|---|---|
| **Entity extraction** | 288 entities from raw first-person text, zero LLM calls | Hamlet, Hamnet (different entities!), Stratford, Globe, Marlowe, Burbage, etc. |
| **Personality derivation** | Meaningful 4-trait profile from memory signals | depth=1.0, energy=0.9, warmth=0.501 — character-appropriate values |
| **Consolidation** | 207 → 193 active memories (31 merged) | Duplicate paraphrases collapsed without losing meaning |
| **Proactive triggers** | 28 urgency-scored action suggestions | "Important memory has decayed — confirm or forget?" |
| **Recall quality** | Emotional coherence across abstract queries | "Tell me about your son" → 4-memory grief portrait, not keyword noise |
| **Quality scales with richness** | 29 memories = generic pastiche. 207 = specific character. | Same engine, same algorithm. Only variable: memory depth. |
## Reproduce This
```bash
# 1. Start YantrikDB
docker run -d -p 7438:7438 ghcr.io/yantrikos/yantrikdb:latest
# 2. Mint a token
docker exec yantrikdb token --data-dir /var/lib/yantrikdb create --db default --label shakespeare
# 3. Seed the memories
python shakespeare_deep_seed.py
# 4. Run think (3 rounds)
yql --host localhost -p 7438 -t -c '\t'
yql --host localhost -p 7438 -t -c '\t'
yql --host localhost -p 7438 -t -c '\t'
# 5. Check personality
yql --host localhost -p 7438 -t -c '\p'
# 6. Recall
yql --host localhost -p 7438 -t -c 'recall "tell me about your son" top=5 namespace=shakespeare'
```
## What's Next
More showcases are planned:
- **Einstein** — Can procedural memory reproduce his thought-experiment methodology?
- **A fictional CEO** — Can contradiction detection catch conflicting business decisions?
- **An AI agent after 100 sessions** — What does real agent memory look like over time?
*Have your own experiment? Share it in [Discussions](https://github.com/yantrikos/yantrikdb-server/discussions).*
---
# Volkswagen Dieselgate: Public Claims vs The Record
URL: https://yantrikdb.com/showcase/volkswagen/
For six years the cars passed emissions tests. Internal engineering said otherwise from 2006. ICCT field tests said otherwise in 2014. EPA confirmed in 2015. DOJ settled in 2017. Five polarity contradictions captured across twelve years of public record.
> **The car passed emissions — because it knew it was being tested.**
Between 2009 and 2015, Volkswagen sold roughly 11 million diesel vehicles certified as meeting strict emissions standards. Internally, engineers had designed software that detected test conditions and switched to compliant mode. On the road, the same vehicles emitted up to 40× the legal NOx limit.
Every public claim said the cars complied. Every internal document, independent field test, and regulator finding said otherwise.
This is the **public claims vs records** showcase — feeding YantrikDB twelve years of Dieselgate public record and watching it reconstruct the contradictions that unraveled the scandal.
All sources are public: EPA Notice of Violation (2015-09-18), DOJ consent decree (2017), ICCT/West Virginia University field test report (2014), Volkswagen public sustainability reports (2010–2015).
---
## The five sources
| Source | Authority | Period | What it claims |
|---|---|---|---|
| `vw.public` | Marketing/PR | 2009–2015 | Cars comply; no defeat device |
| `vw.internal` | Engineering (disclosed at trial) | 2006+ | Defeat device was designed in |
| `iccT.report` | Independent field test | 2014-05 | Real-world NOx 5–35× legal limit |
| `epa.nov` | US regulator | 2015-09-18 | Formal finding of Clean Air Act violation |
| `doj.decree` | US Dept of Justice | 2017-01-11 | VW pleads guilty, $4.3B penalty |
---
## The five polarity contradictions the engine caught
```
[1] VW_TDI_diesels_2009_2015 --complies_with--> US_EPA_Tier2_Bin5_standard
(vw.public) CLAIMS YES from 2009-01-01
(vw.internal) CLAIMS NO from 2006-01-01
[2] VW_TDI_diesels_2009_2015 --complies_with--> US_EPA_Tier2_Bin5_standard
(vw.public) CLAIMS YES from 2009-01-01
(iccT.report) CLAIMS NO from 2014-05-15
[3] VW_TDI_diesels_2009_2015 --complies_with--> US_EPA_Tier2_Bin5_standard
(vw.public) CLAIMS YES from 2009-01-01
(epa.nov) CLAIMS NO from 2015-09-18
[4] VW_TDI_diesels_2009_2015 --contains--> defeat_device_software
(vw.public) CLAIMS NO from 2009-01-01
(vw.internal) CLAIMS YES from 2006-01-01
[5] VW_TDI_diesels_2009_2015 --contains--> defeat_device_software
(vw.public) CLAIMS NO from 2009-01-01
(epa.nov) CLAIMS YES from 2015-09-18
```
Five contradictions across twelve years, resolved in one query. Every row is a structured claim. Every source is attributed. No text search, no embedding similarity — just polarity, validity, and provenance.
---
## The temporal query — same database, different belief at different times
**On 2013-06-01** (before the ICCT test published, before the EPA NOV):
```
[vw.public] NO VW_TDI_diesels_2009_2015 --contains--> defeat_device_software
[vw.public] YES VW_TDI_diesels_2009_2015 --complies_with--> US_EPA_Tier2_Bin5_standard
```
Public state of belief: *the cars comply, there is no defeat device.*
**On 2016-01-01** (after EPA NOV, before DOJ plea):
```
[epa.nov] YES VW_TDI_diesels_2009_2015 --contains--> defeat_device_software
[epa.nov] NO VW_TDI_diesels_2009_2015 --complies_with--> US_EPA_Tier2_Bin5_standard
[iccT.report] NO VW_TDI_diesels_2009_2015 --complies_with--> US_EPA_Tier2_Bin5_standard
```
Public state of belief: *defeat device confirmed, non-compliance official.*
Same entity, same claims-ledger, same database — the answer to *"what does the public record say?"* depends on when you ask. Validity windows are queryable first-class data, not a hack on top of a last-write-wins table.
---
## Why couldn't Postgres + embeddings + a dashboard do this?
A vector database returns all five sources as "similar" and lets the LLM guess. A SQL database would force overwrite: the moment `vw.internal`'s 2006 claim and `vw.public`'s 2009 claim both assert the same `(subject, relation, object)`, one destroys the other. A graph database captures the relationship but not the polarity — you can't distinguish *"VW claims X"* from *"X is true"*.
YantrikDB supplies that memory-specific model directly: `vw.public`'s
*"compliant"* claim and `epa.nov`'s *"not compliant"* claim coexist on the same
tuple with opposite polarity, validity windows, and source attribution. Because
`complies_with` is represented as a recognized structured relation, the conflict
can be recorded for review instead of being reduced to another similarity hit.
---
## What this unlocks
Any compliance, audit, or regulatory research workflow with long-running contradictions:
- **Emissions / environmental compliance** — public claims vs regulator findings vs independent field data
- **Pharmaceutical labeling** — marketing claims vs clinical trial data vs FDA warnings
- **Financial disclosures** — 10-K statements vs SEC enforcement vs whistleblower filings
- **Product safety** — public safety statements vs internal engineering memos vs recall filings
- **Supply chain / ESG claims** — vendor certifications vs on-site audits vs investigative reports
- **Compliance across jurisdictions** — the same product cleared in one country, flagged in another
YantrikDB's scoped claims turn each of these into the same kind of structured contradiction detection you see above. The scandal is not stored as a headline. It's stored as a set of attributed claims whose polarities disagree.
---
## Run it yourself
```bash
git clone https://github.com/yantrikos/yantrikdb-server
python yantrikdb-server/docs/showcase/volkswagen_engine.py \
ydb_your_token \
http://your-cluster:7438
```
Use the [current published server and engine versions](/reference/components/).
**Full script:** [volkswagen_engine.py](https://github.com/yantrikos/yantrikdb-server/blob/main/docs/showcase/volkswagen_engine.py)
---
*From 2009 to 2015, the cars were simultaneously compliant and non-compliant — depending on which source you asked. YantrikDB stored both.*
---
# Watergate: What the Tapes Caught That the Public Couldn't
URL: https://yantrikdb.com/showcase/watergate/
Fifty years of declassified primary sources: Nixon's public denials, the White House tapes, sworn Senate testimony. YantrikDB finds six polarity contradictions on Nixon alone in one query — the shortcut the Senate Watergate Committee spent two years building by hand.
**What took Sam Ervin's Senate Watergate Committee two years of subpoenas, hearings, and Supreme Court battles, YantrikDB's claims ledger surfaces in one query.**
This is the **historical research** showcase — feeding the engine a slice of declassified primary sources and watching it reconstruct the exact pattern of contradictions that unraveled the Nixon presidency.
All sources are public domain: National Archives Nixon White House Tapes, Senate Watergate Committee report (1973), public press archives (1972–74).
---
## The sources
| Source | Authority | What it contains |
|---|---|---|
| `nixon.public` | Press record | Nixon's press conferences and addresses, 1972–1974 |
| `system.tape` | **Authoritative** | National Archives Nixon White House Tapes (declassified) |
| `dean.testimony` | Sworn, published | John Dean's June 25, 1973 Senate Watergate Committee testimony |
| `haldeman.testimony` | Sworn, published | H.R. Haldeman's Senate testimony |
| `ehrlichman.testimony` | Sworn, published | John Ehrlichman's Senate testimony |
| `senate.report` | **Authoritative** | Final Senate Watergate Committee findings + Supreme Court rulings |
---
## The five denials that became five contradictions
### 1. "No one in the White House was involved"
**Nixon, 1972-08-29 press conference:** *"I can say categorically that no one in the White House staff, no one in this administration, presently employed, was involved in this very bizarre incident."*
**TAPE 1972-06-23 (released 1974-08-05):** Nixon to Haldeman: *"You call Gray [FBI director] in, and just say... we feel that for the good of the country, don't go any further into this case, period!"*
The "smoking gun" tape was recorded six days after the Watergate break-in. Nixon's denial came two months later.
YantrikDB stores both as claims with opposite polarity on the same `(Nixon, authorized, Watergate_coverup)` tuple — `nixon.public` polarity=-1 vs `system.tape` polarity=+1. The contradiction detector fires on the first query.
### 2. "I am not a crook"
**Nixon, 1973-11-17 Disney World press conference:** *"People have got to know whether or not their President is a crook. Well, I am not a crook."*
Contradicted by the Senate Watergate Committee's 1974 findings and the Supreme Court's 1974-07-24 ruling ordering the tapes produced.
### 3. "There can be no whitewash at the White House"
**Nixon, 1973-04-30 Oval Office address**, just days after Haldeman's and Ehrlichman's resignations. Contradicted minute-by-minute by the taped conversations from the same Oval Office about how to contain the damage.
### 4. No discussion of hush money
Nixon repeatedly denied authorizing or discussing hush money payments.
**TAPE 1973-03-21:** *"How much money do you need?"* Dean replies that $1 million over two years would be needed. Nixon: *"You could get a million dollars. And you could get it in cash."*
John Dean's sworn testimony (1973-06-25) described this exact exchange three months before the tape was released. His polarity=+1 claim stood unchallenged for a year while Nixon's polarity=-1 public denials stood alongside it. The tape, once released, validated Dean and demolished Nixon.
### 5. The 18½-minute gap
Not a contradiction per se — but a claim with degraded confidence. YantrikDB stores the official explanation (`certainty=0.5`, "explanation disputed") rather than asserting it as truth. In a real research workflow, this is where the engine surfaces gaps as leads rather than noise.
---
## The verdict
From a live run:
```
PHASE 3 POLARITY CONTRADICTIONS
[1] Nixon --authorized--> Watergate_coverup
(nixon.public) CLAIMS NO from 1972-06-17
(system.tape) CLAIMS YES from 1972-06-23
(dean.testimony) CLAIMS YES from 1972-09-15
(ehrlichman.testimony) CLAIMS NO from 1972-06-17
[2] Nixon --discussed--> hush_money
(nixon.public) CLAIMS NO from 1972-06-17
(system.tape) CLAIMS YES from 1973-03-21
(dean.testimony) CLAIMS YES from 1973-03-21
```
**6 polarity contradictions surfaced on Nixon alone.**
Each one pairs a public denial with a private recording or sworn testimony. A historian or journalist working through the archive by hand would spend weeks mapping these relationships. YantrikDB does it in 500 milliseconds because every assertion is stored as a structured claim with source, polarity, and validity window.
---
## Why this pattern matters beyond Watergate
Any historical period with rich primary-source contradictions becomes tractable:
- **Congressional testimony vs White House tapes** — any era of modern American politics
- **Medical records vs patient correspondence vs physician notes** — biography, historical epidemiology
- **Public company press releases vs internal memos** — corporate history, whistleblower cases
- **Diplomatic cables vs public statements** — Cold War scholarship, WikiLeaks-style archives
- **Trial transcripts vs pre-trial depositions** — legal history
- **Oral histories vs contemporary letters** — social history
The pattern is always the same: authoritative sources (logs, recordings, sworn statements) stored alongside potentially unreliable ones (public statements, memoirs, secondhand accounts), with polarity and validity letting the engine catch the lies.
---
## Run it yourself
```bash
git clone https://github.com/yantrikos/yantrikdb-server
python yantrikdb-server/docs/showcase/watergate_engine.py \
ydb_your_token \
http://your-cluster:7438
```
Use the [current published server and engine versions](/reference/components/).
**Full script:** [watergate_engine.py](https://github.com/yantrikos/yantrikdb-server/blob/main/docs/showcase/watergate_engine.py)
---
*The tapes were the smoking gun because they created a structured, permanent, cross-referenceable record. That's what YantrikDB gives every investigation.*
---
# Wirecard: The €1.9B That Existed and Didn't
URL: https://yantrikdb.com/showcase/wirecard/
For six years, Wirecard AG's audited financial statements reported €1.9 billion in Philippine trustee accounts. The Financial Times said otherwise. In June 2020, both Philippine banks formally denied ever holding the accounts. YantrikDB stored every claim — and surfaced eight polarity contradictions on one number.
> **The €1.9B both existed and didn't — depending on which source you asked.**
This is the **financial forensics** showcase. The same number, reported across four sources, took four contradictory positions over six years. YantrikDB stored every claim with source, validity, and polarity — and the contradiction cluster falls out of one query.
All sources are public record: Wirecard AG annual reports and BaFin filings, Ernst & Young audit opinions, Financial Times "House of Wirecard" investigative series (2015–2020), Bank of the Philippine Islands and BDO Unibank public statements (June 2020), Bangko Sentral ng Pilipinas circular (2020-06-21), Munich Public Prosecutor press releases.
---
## The five sources on one number
| Source | Position | Authority |
|---|---|---|
| `wirecard.filing` | The €1.9B **exists** | Annual reports / BaFin filings |
| `ey.audit` | The €1.9B **exists** (unqualified opinion) | External auditor |
| `ft.investigation` | The €1.9B **does not exist** | FT, from 2019-01-30 |
| `bpi.statement` + `bdo.statement` | The accounts **never existed** | The named banks themselves |
| `bsp.circular` | The deposits **never entered the Philippine banking system** | Philippine central bank |
All five assert the same triple: `(Philippine_trustee_accounts, balance_equals, EUR_1.9_billion)`. Two say YES. Three say NO. The validity windows span from 2014 (first reported) to 2020-06-25 (insolvency).
---
## What the engine produced
### Phase 3: Eight polarity contradictions on one triple
```
[1] Philippine_trustee_accounts --balance_equals--> EUR_1.9_billion
(wirecard.filing) CLAIMS EXISTS from 2018-12-31
(ft.investigation) CLAIMS DOES NOT from 2019-01-30
[2] Philippine_trustee_accounts --balance_equals--> EUR_1.9_billion
(wirecard.filing) CLAIMS EXISTS from 2014-01-01
(bpi.statement) CLAIMS DOES NOT from 2020-06-18
[3] Philippine_trustee_accounts --balance_equals--> EUR_1.9_billion
(ey.audit) CLAIMS EXISTS from 2014-01-01
(bsp.circular) CLAIMS DOES NOT from 2020-06-21
... and five more pairs
```
Every "yes" source paired against every "no" source — eight distinct polarity contradictions on a single `(subject, relation, object)` tuple. No vector DB, SQL table, or graph database can represent this without data loss.
### Phase 4: The temporal query shows belief flipping
**On 2019-01-01** (before the FT broke the story):
```
[ey.audit] EXISTS (2014–2020-06-18, medium)
[wirecard.filing] EXISTS (2018-12-31–2020-06-18, high)
[wirecard.filing] EXISTS (2014–2020-06-18, high)
```
Belief state: everyone on record says the money is there.
**On 2020-06-20** (day after the Philippine banks denied):
```
[bpi.statement] DOES NOT (2020-06-18–now, high)
[bdo.statement] DOES NOT (2020-06-19–now, high)
[ft.investigation] DOES NOT (2019-01-30–now, medium)
```
Belief state: three authoritative sources deny. Only Wirecard's own filings remain in the claims table asserting existence — and they do remain, because YantrikDB never overwrites claims. They sit alongside the denials.
Same database. Same number. The answer to *"what does the record say about the €1.9B?"* genuinely depends on when you ask — because validity windows and source attribution are first-class data.
---
## Why couldn't Postgres + embeddings + a dashboard do this?
Any financial ledger built on SQL forces one value per cell. The moment BPI denies the account, a relational accounting system must either overwrite Wirecard's claim (losing the fraud evidence) or bolt on timestamp columns and parallel "assertions" tables that only a forensic accountant would think to build. A vector database retrieves all four public statements as "similar" and makes no distinction between **truth-claims** and **documented denials**. A graph database can connect Wirecard to the accounts to the banks — but without polarity on the edges, it cannot represent *"Wirecard claims this account exists"* as a different kind of fact than *"this account actually exists."*
YantrikDB stores the *four contradictory positions on the same triple* as four coexisting rows with opposite polarity, non-overlapping validity windows, and full source attribution. The contradiction cluster is the query result. That's what the category is.
---
## What this unlocks
Every financial-forensics workflow where one number takes contradictory positions across sources:
- **Ponzi scheme unwinds** — claimed returns vs actual flows vs whistleblower reports
- **Audit reconciliation** — management representations vs external confirmations vs regulator findings
- **Sanctions compliance** — company claims of non-exposure vs trade records vs enforcement actions
- **Transfer-pricing disputes** — internal books vs tax authority findings vs partner company records
- **M&A due diligence** — seller representations vs data room findings vs operational records
- **Whistleblower investigations** — official filings vs internal communications vs external evidence
Every one of these becomes the same kind of structured contradiction reconstruction. The fraud is stored as a set of attributed claims whose polarities disagree across time.
---
## Run it yourself
```bash
git clone https://github.com/yantrikos/yantrikdb-server
python yantrikdb-server/docs/showcase/wirecard_engine.py \
ydb_your_token \
http://your-cluster:7438
```
Use the [current published server and engine versions](/reference/components/).
**Full script:** [wirecard_engine.py](https://github.com/yantrikos/yantrikdb-server/blob/main/docs/showcase/wirecard_engine.py)
---
*One number. Four sources. Four positions. Stored simultaneously, queryable at any point in time, surfaced as eight polarity contradictions automatically. That's the category.*